Federated Learning Without the Refactoring Overhead Using NVIDIA FLARE
Mirrored from NVIDIA Developer Blog for archival readability. Support the source by reading on the original site.
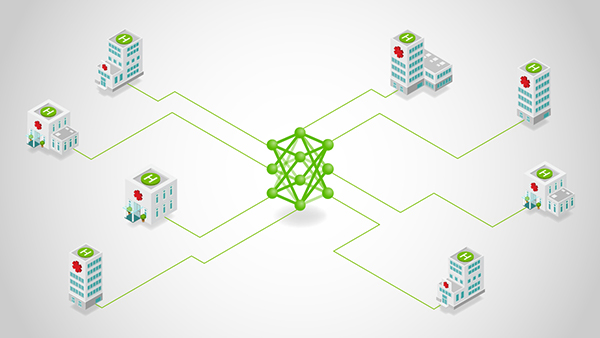 Federated learning (FL) is no longer a research curiosity—it’s a practical response to a hard constraint: the most valuable data is often the least movable....
Federated learning (FL) is no longer a research curiosity—it’s a practical response to a hard constraint: the most valuable data is often the least movable. Regulatory boundaries, data sovereignty rules, and organizational risk tolerance routinely prevent centralized aggregation. Meanwhile, sheer data gravity makes even permitted transfers slow, expensive, and fragile at scale.
More from NVIDIA Developer Blog
-
How to Rewrite Apache Spark UDFs for GPU Acceleration with AI Agents
Oct 13
-
NVIDIA Run:ai Is Now Open Source as Part of NVIDIA DSX AI Factory Platform
Oct 13
-
ReplaySSM: Rethinking State Storage for Faster Hybrid-Model Decoding
Oct 12
-
5 Steps to Create SimReady Assets for Robotics with Frontier AI Models
Oct 8
Discussion (0)
Sign in to join the discussion. Free account, 30 seconds — email code or GitHub.
Sign in →No comments yet. Sign in and be the first to say something.