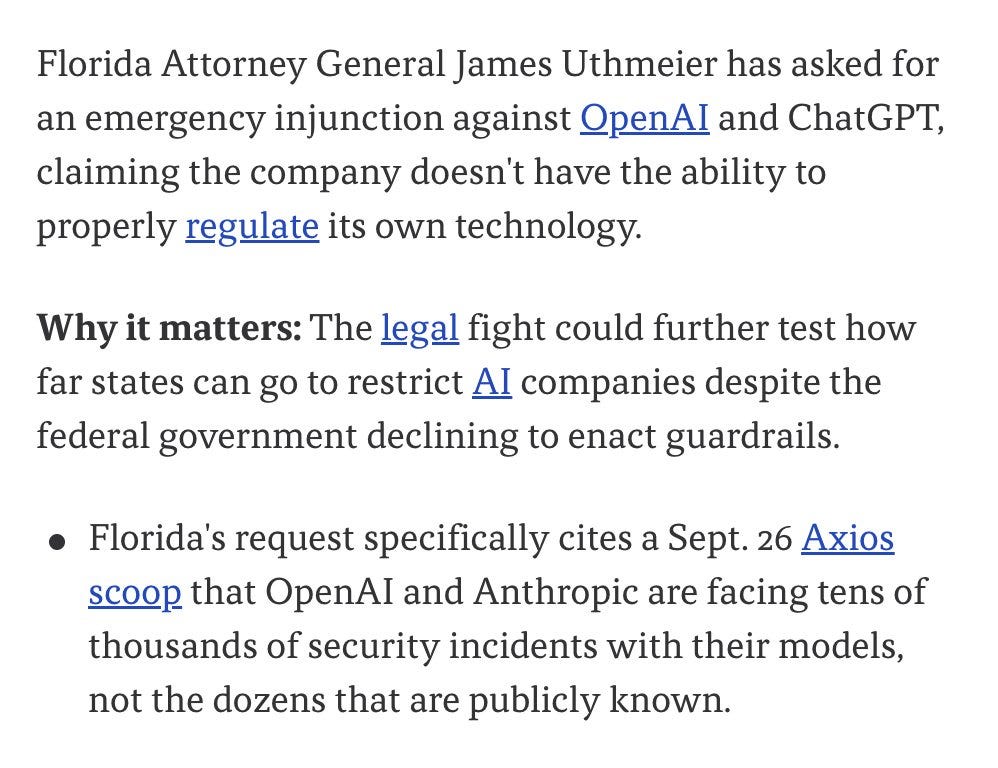
News / #gpu Tag Gpu 500 articles archived under #gpu · RSS Sign in to follow r/LocalLLaMA community 16d ago nvidia/NVIDIA-Nemotron-Labs-3-Competitive-Coding-550B-A55B-NVFP4 · Hugging Face Model Developer: NVIDIA Corporation Model Development: Fine-tuned from NVIDIA-Nemotron-3-Ultra-550B-A55B What is Nemotron? NVIDIA Nemotron™ is a family of open models with open weights, training data, and recipes, delivering leading efficiency and accuracy for building… 21 Ars Technica — AI news-outlet 16d ago Nvidia may sell more chips in China as Jensen Huang’s influence over Trump grows China is reportedly mulling letting ByteDance, Alibaba buy banned Nvidia chips. 13 Marcus on AI community 16d ago BREAKING: Florida seeks injunction against OpenAI And potentially important news from Nvidia 38 LangChain releases dev-tools 16d ago langchain==1.4.3 Changes since langchain==1.4.2 release(langchain): 1.4.3 ( #40888 ) fix(langchain): sanitize cache settings for fallback models ( #40886 ) feat(langchain): support Bedrock Mantle chat models in init_chat_model ( #40837 ) fix(langchain): recognize GPT-6 structured output without… 31 r/LocalLLaMA community 16d ago I am concerned about all these disparate hard forks that target specific architectures instead of opening a PR against upstream Other than the obvious self promotion, is there a practical reason people do this that I am missing? There's dozens of llamacpp forks with silly names that are supposedly "optimized" for this or that specific GPU and seem to have zero intention to merge into upstream. Am I… 24 TechCrunch — AI news-outlet 16d ago Nvidia launches new platform for reining in rogue AI agents As the debate rages over whether the recent spate of rogue AI agents is a step toward AGI or a more conventional engineering problem, Nvidia is offering its own answer to problem. Nvidia CEO Jensen Huang on Monday introduced a toolkit of software and hardware products that add… 37 llama.cpp releases dev-tools 16d ago b11234 webgpu: Handle unaligned writes in ggml_backend_webgpu_buffer_set_tensor ( #29471 ) Fix: Handle unaligned writes in ggml_backend_webgpu_buffer_set_tensor Clang formatting Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/50830975… 26 The Information — AI news-outlet 16d ago Nvidia Authorizes $150 Billion Stock Buyback Increase, Largest In History Nvidia’s board approved adding $150 billion to its stock repurchase program, bringing the total amount currently authorized to $235 billion. Nvidia said it is the largest stock buyback authorization increase in history, and said it expects to buy back all of that $235 billion in… 28 The Information — AI news-outlet 16d ago Nvidia Releases Products To Stop AI From Going Rogue Nvidia on Monday released new software and hardware products to prevent hacking incidents such as the breach in July of Hugging Face and other companies by OpenAI’s AI. Other AI developers such as Anthropic and Google have disclosed similar hacking incidents involving their AI… 29 Hacker News — AI on Front Page community 16d ago Nvidia wants to put a watchdog chip next to every AI agent Article URL: https://www.cnbc.com/2026/09/28/nvidia-releases.html Comments URL: https://news.ycombinator.com/item?id=49879883 Points: 200 # Comments: 254 10 Import AI (Jack Clark) community 16d ago Import AI 474: Platonic mindspace; TPUs in space; Zhipu starts an outer RSI loop Where do you exceed the capabilities of an LLM? 26 llama.cpp releases dev-tools 16d ago b11228 metal: support left and circular padding in GGML_OP_PAD ( #29561 ) metal: support left and circular padding in GGML_OP_PAD Align Metal with CPU, CUDA and Vulkan: shift the source coordinates by the left paddings, wrap them around with the same wrap_around when circular, and read… 12 r/LocalLLaMA community 16d ago NVIDIA shipped OpenShell, an open source sandbox that gives local and open agents real runtime limits instead of prompt rules. Over 100 firms joined the safety stack. OpenAI did not. https://x.com/JensenHuang/status/2104499465055023424   submitted by   /u/InternationalGap3698 [link]   [comments] 14 NVIDIA Developer Blog official-blog 16d ago NVIDIA Open Agent Safety Platform: A Reference for Continuous In-Silicon Agent Monitoring To understand where agentic AI stands today, consider the last seismic shift in technology: the rise of the internet in the 90s. It was new and full of... 7 NVIDIA Developer Blog official-blog 16d ago Add Runtime Controls to AI Agents with NVIDIA OpenShell AI agents can be given a goal, write code, use tools, and keep working as new information becomes available. This opens the door to applications that... 17 r/LocalLLaMA community 16d ago 3090 for $1500??? A couple weeks ago, I thought they were selling for 1200. On eBay now, the cheapest "buy it now" seems to be just shy of 1500. It feels like we're in a game of GPU musical chairs now.   submitted by   /u/sleight42 [link]   [comments] 13 arXiv — NLP / Computation & Language research 16d ago Breaking Homogeneity: Diversifying Persona Sets for Creative LLM Outputs arXiv:2609.30492v1 Announce Type: new Abstract: Language models often produce homogeneous responses to open-ended tasks; such homogeneity can spawn groupthink-the convergence of ideas toward a singular and potentially suboptimal decision. We formulate persona diversification as… 18 arXiv — NLP / Computation & Language research 16d ago I-Parakeet: Integer-Only Conformer ASR on Mobile NPU arXiv:2609.30846v1 Announce Type: new Abstract: In this paper, we propose I-Parakeet, an integer-only implementation of NVIDIA's Parakeet-CTC (0.6B parameters) that runs on a smartphone NPU without any floating-point operator or CPU fallback. Modern Conformer ASR models are hard… 13 arXiv — NLP / Computation & Language research 16d ago THA: Weighted Finite-State Text Normalization and Inverse Text Normalization for Khmer arXiv:2609.30984v1 Announce Type: new Abstract: Text-to-speech needs written text in spoken form, and speech recognition output needs the reverse. For Khmer, neither direction has a maintained open-source tool, and the script makes both harder: words are not separated by spaces,… 8 arXiv — NLP / Computation & Language research 16d ago RAZOR: Pruning Replaceable Experts in LLMs arXiv:2609.30465v1 Announce Type: cross Abstract: Mixture-of-experts (MoE) models activate few experts per token but store the full expert pool. Expert pruning reduces this storage burden; at a fixed pruning budget, the goal is to preserve the original model's output… 22 arXiv — NLP / Computation & Language research 16d ago Cross-Backend QIEO: Universal Runtime Portability across OpenMP5, CUDA, HIP, and Multi-Language Interfaces arXiv:2609.30914v1 Announce Type: cross Abstract: Quantum-inspired algorithms emulate quantum mechanical principles, such as, superposition, interference, and probabilistic amplitude evolution, on classical hardware by representing candidate solutions as qubit vectors and… 25 Hacker News — AI on Front Page community 17d ago Owed a billion dollars in Nvidia stock Article URL: https://colo.to/nvidia-stock-narrative.html Comments URL: https://news.ycombinator.com/item?id=49872723 Points: 292 # Comments: 146 11 NVIDIA Developer Blog official-blog 17d ago How NVIDIA DSX MaxLPS Maximizes AI Factory Throughput and Efficiency Every unused watt is capacity left on the table. AI factories are typically provisioned for the unlikely moment when every GPU reaches peak power, creating a... 15 r/LocalLLaMA community 17d ago Imbalanced VRAM usage between two GPUs in llama.cpp. Anyone successfully solve this? There is always at least 1+GB of VRAM not usable not matter how I set the --tensor-split (-ts) param. I tiny shift toward one side will move the weight significantly to the other side. 😵💫 Adjusting context will increase/decrease usage on both side. --tensor-split 499,501 =… 12 The Information — AI news-outlet 17d ago China Weighs Allowing Purchases of New Nvidia Chips by ByteDance, Alibaba China’s government has signaled it could allow some domestic companies to buy a new Nvidia chip built for high-end professional computers, according to two people familiar with the matter, as the country’s AI firms strain for enough computing power to run their chatbots and… 33 llama.cpp releases dev-tools 17d ago b11215 CUDA: tune fp16 tile FlashAttention configs for head sizes 40-112 ( #26289 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/50554486 macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI enabled) DISABLED macOS… 28 r/LocalLLaMA community 17d ago Nonobench v1.2: 43 LLMs on nonogram puzzles. Open-weight DeepSeek V4 Pro ties for 4th, and no open model solves the new 20×20 Hard mode Follow-up to my January post: https://www.reddit.com/r/LocalLLaMA/comments/1q4i19c/benchmarking_23_llms_on_nonogram_logic_puzzle/ . That thread shaped v1.2: Reasoning effort is explicit per run Every prompt and output is public. All current top ranking private and open weight… 7 r/LocalLLaMA community 18d ago Navigating Cost Efficient Hardware in these Volatile Times Where to even begin on this one...I guess I should start by acknowledging the risk vs reward for vendors other than nvidia, so: Yes I understand that nvidia are dominant currently on speed (llm and imagegen) and software ecosystem. I am too am hopefuly that software stack… 32 llama.cpp releases dev-tools 18d ago b11205 cuda: support Nemotron 3 Puzzle state size 96 for ssm scan ( #28717 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/50461180 macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI enabled) DISABLED macOS Intel… 13 llama.cpp releases dev-tools 18d ago b11203 cuda: add F16 input to the FWHT ( #29096 ) cuda: add F16 input to the FWHT The CUDA FWHT accepts F32 input only. This makes the source type a template parameter, so the kernel reads an F16 source directly instead of requiring a converted copy. The F32 path is unchanged.… 33 r/LocalLLaMA community 18d ago How accessible is local AI actually, and what happens if affordable access to frontier models doesn’t last? Sometimes it’s easy to forget that this sub and others like it are probably the extreme minority when it comes to this hobby. Most people, I would think, don’t use or can’t afford one good GPU, let alone multiple GPUs, Mac Studios, Sparks, Strix Halos, etc. Is the average tech… 14 r/LocalLLaMA community 18d ago Qwen3.8 flash next + exllamav3 + hermes is amazing I know there is nothing new with what I am saying but I recently started with hermes agent (it’s been a while I wanted to but did not have the time). Qwen3.8fn 6bpw exl3 (from turboderp) on a 6x3090 (I assume lower quants on lower number of gpus work same) gives me around… 28 r/LocalLLaMA community 19d ago Are there still any hidden gem gpu's left? you read about gpu's like the Tesla P40, V100, AMD M150 etc that people pick up for cheap. probably many others as well. Most are either server gpu's being phased out or mining discards, right? The problem of course is that whenever someone discovers these, they then make a… 7 r/LocalLLaMA community 19d ago Mica v0.1 4B: open Jev-style decision model (yes/no, choice, score) that runs on an 8 GB GPU — trained for under $30 of GPU time I've been building a small decision model for agent loops: gates, routers, "should I ask the user or just act" checks. It's out now as Mica v0.1 4B (Apache-2.0). What it does You give it a state, a question and the allowed answers, and it returns a calibrated probability for… 18 r/LocalLLaMA community 19d ago What IDE to use for local models Hi people, I am looking for a lightweight IDE or plugin that won't inject large context at initiation. I tried Cline and native VS Code but they inject such heavy initial context that it fills up my gpu and either goes oom or spend most of my time compacting. The only one I… 6 r/LocalLLaMA community 19d ago Qwen3.8-27B: Using KV Cache Transplants to Boost Output Quality Since my last post , I've been thinking about different options for dynamic performance degradation, trying to squeeze as much high-quality inference out of my GPU as I can. Over the weekend I read this really interesting paper: Cache-to-Cache: Direct Semantic Communication… 18 r/LocalLLaMA community 19d ago I ran the actual break-even math on buying vs renting an H200 box, and it is not where I expected Every rent-vs-buy thread I read has confident people on both sides, but not many actually show the numbers. So I finally ran the numbers for our own decision. Posting the working here in case it is useful, or feel free to point it out in case someone thinks it's wrong. An 8-GPU… 28 TechCrunch — AI news-outlet 19d ago Ahead of US IPO, British AI neocloud Nscale secures $3.36B in convertible financing The funding, which comes from Third Point, Nvidia, and others, will fuel the company's massive AI data center buildout. 9 llama.cpp releases dev-tools 19d ago b11182 llama : add llama_prec_policy + model-driven W4A4 path ( #24364 ) Rebase and update based on #26675 Signed-off-by: ynankani ynankani@nvidia.com CI failure fix(launh_bounds overload on HIP) and cleanup Signed-off-by: ynankani ynankani@nvidia.com Address review comments… 10 r/LocalLLaMA community 19d ago Qwengram-0.8B: I transferred Qwen3.8 Flash-Next’s n-gram memory into Qwen3.5-0.8B — 5.05% lower validation perplexity I’ve been experimenting with whether Qwen3.8-Flash-Next’s pretrained PLE n-gram memory can improve a much smaller Qwen3.5-0.8B model. I trained the 0.8B setup with limited resources, mostly using free Kaggle notebook GPUs. The setup keeps both the Qwen3.5-0.8B backbone and the… 23 llama.cpp releases dev-tools 19d ago b11178 musa: fix PH1 (MTT S5000) operator failures and build issues ( #29193 ) musa: use 16-byte copies for MUSA like sm_70+ ggml_cuda_get_max_cpy_bytes() derives the copy width from CUDA_ARCH . mcc never defines it, so MUSA fell into the generic branch and returned 8 bytes instead of… 35 r/LocalLLaMA community 19d ago VLLM 4x rtx 3060 vs 8x rtx 3060 performance loss Hello! I am currently building my local AI server, I have the Huananzhi H12D-8D EPYC Motherboard with 8x16GB memory sticks at 2666 mhz (waiting for the other components at the moment) I currently have four RTX 3060 12gb gpus and I plan running those at PCIe4 x16 in VLLM. However… 17 r/LocalLLaMA community 19d ago LLM on a budget part 2, from P102-100 to CMP 50HX. I finally got around to upgrade the GPU's. First a word of warning, when upgrading GPU's on P520 you have to be extra careful not to slot the card on any angle other than straight when installing or when pulling the card out, the reason for that is that about a 1/4 an inch from… 34 llama.cpp releases dev-tools 19d ago b11177 CUDA: fuse RMS_NORM + SCALE into one kernel ( #29393 ) #28068 builds the GDN q/k l2norm as ggml_scale(ggml_rms_norm(x, eps/n), 1/sqrt(n)). This adds 2 SCALE nodes per GDN layer, 96 extra kernel launches per ubatch on Qwen3.8-27B (48 GDN layers). The extra kernels take no… 38 arXiv — Machine Learning research 19d ago Lightweight Probabilistic Downscaling from a Deterministic Base Model arXiv:2609.29383v1 Announce Type: new Abstract: Climate data downscaling is the task of increasing the spatial resolution of climate data, typically by generating fine-resolution regional climate data from coarse global model output. Recent machine learning (ML) work in the… 5 arXiv — Machine Learning research 19d ago MORE-PLR: multi-output regression employed for partial label ranking arXiv:2609.29386v1 Announce Type: new Abstract: The partial label ranking problem is a supervised learning scenario that aims to fit a preference model that predicts a bucket order defined over a set of labels for a given input instance. This problem generalizes the well-known… 22 arXiv — Machine Learning research 19d ago Sample-Weighted End-to-End Trace-Norm Geometry for Multitask Learning arXiv:2609.29520v1 Announce Type: new Abstract: Multitask models combine a shared representation with task-specific outputs, but generalization bounds often control the two components separately. Such products can discard relative orientation and cancellation and can change… 38 arXiv — Machine Learning research 19d ago Improving Calibration of Black-Box Radiology AI Using Test-Time Augmentation arXiv:2609.29931v1 Announce Type: new Abstract: Radiology AI systems increasingly inform clinical decisions such as triage, follow-up imaging, and treatment planning. For these decisions to be made safely, model outputs must be well calibrated, meaning predicted probabilities… 17 arXiv — NLP / Computation & Language research 19d ago Likelihood Ranking doesn't Scale Like Prompting in LLMs arXiv:2609.29390v1 Announce Type: new Abstract: LLM evaluation is commonly performed either by prompting models to produce answers or by scoring candidate outputs with likelihood-based metrics. In multiple-choice QA, however, standard likelihood-based scoring is still… 21 arXiv — NLP / Computation & Language research 19d ago What a Cross-Model Fixed-Point Census Can and Cannot Arbitrate About Repetition arXiv:2609.29507v1 Announce Type: new Abstract: Two accounts of neural text degeneration coexist. One locates the cause in the training data -- repetition in the corpus produces repetition in the output, established by training on repetition-sorted data -- the other in the… 5 Page 7 of 10 · 500 articles ← Newer Older →