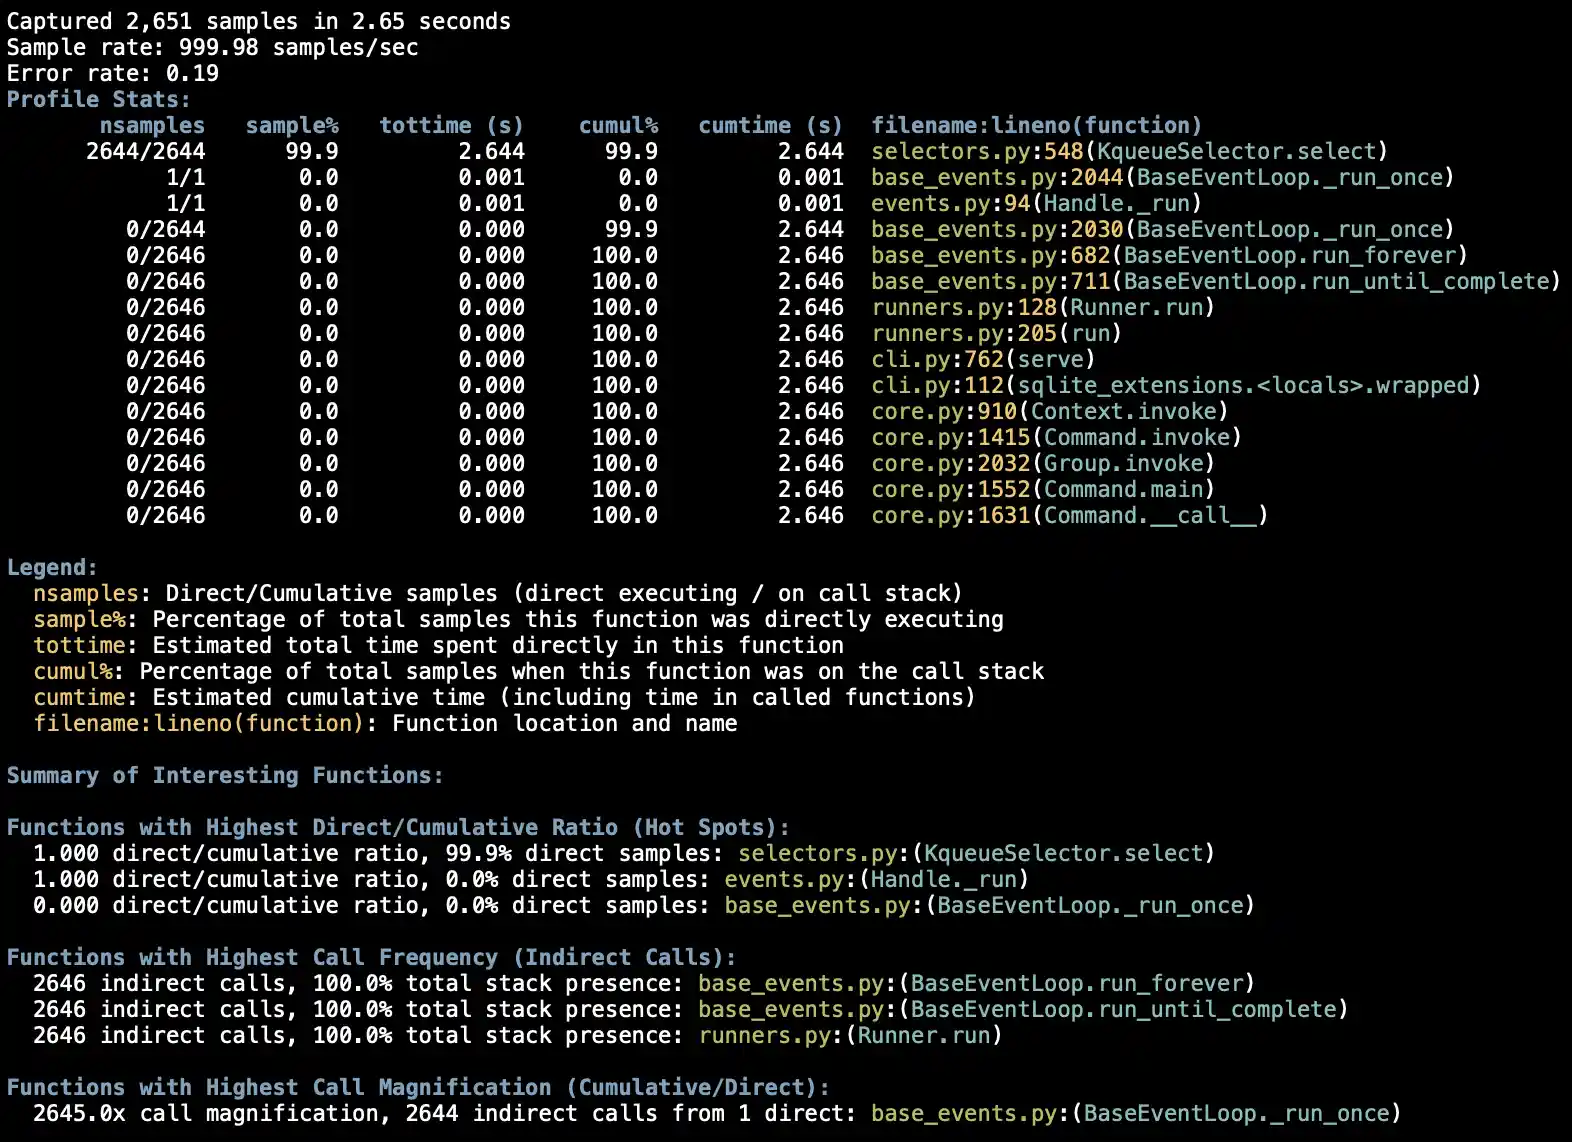
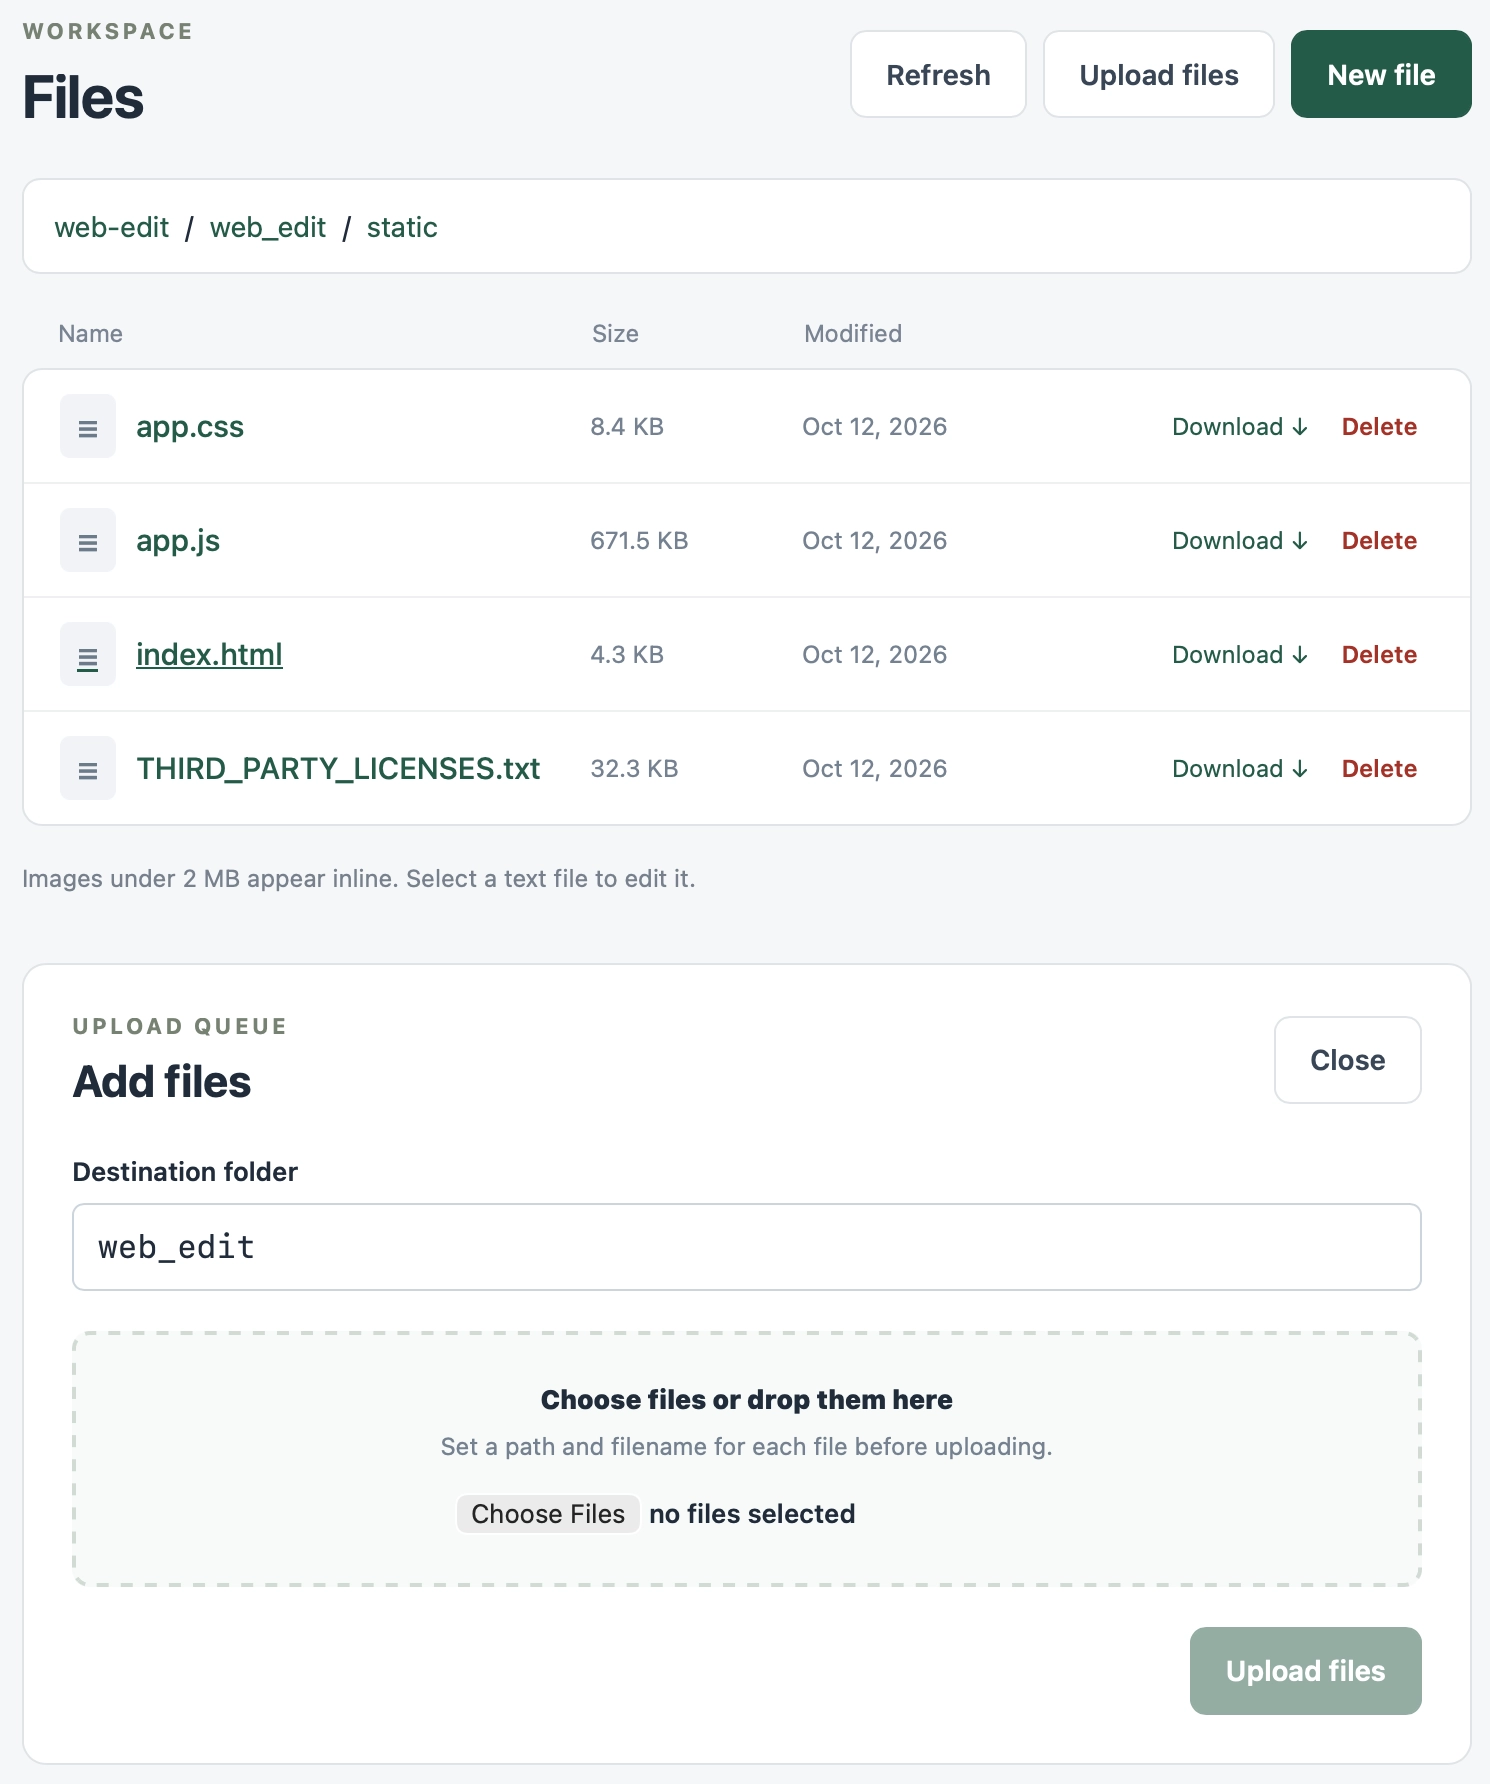
News / #model-release Tag Model releases 500 articles archived under #model-release · RSS Sign in to follow r/LocalLLaMA community 1d ago Qwen 3.8 Flash Next Q3 S - Benchmark creation After running a benchmark test on Exo in Opencode and being amazed by the result, I thought I'd try other models on Opencode. Many were surprisingly terrible. Especially some mid level models. Earlier posts:… 14 vLLM releases dev-tools 1d ago v0.32.0rc0: [HiSparse] Report host pool in KV cache capacity logs (#60285) Signed-off-by: Matthew Bonanni mbonanni@redhat.com Co-authored-by: Claude Opus 5.5 noreply@anthropic.com 25 r/LocalLLaMA community 1d ago llama.cpp optimizations for specific hardware and models I've made a few posts recently, just talking about the hardware I've got and the model I use. Pair of P100s, Unsloth Qwen3.6 35b A3B UD Q4 K XL . There's been a ton of talk of model and hardware specific inference engines showing crazy performance numbers on models and hardware… 27 r/LocalLLaMA community 2d ago Running unsloth/Qwen3.8-27B-UD-IQ4_XS 262k q4_0 KV + vision on 16GB VRAM @ 80t/s and 1500pp I get a lot of hate whenever I tell people I run a Q4 quant of Qwen3.8 27B with 262k KV 80t/s with vision, all while running 2 screens on windows on the same card. People seem to think I am lying or making it up. I am really just trying to help people. I am saddened whenever I… 31 LangChain releases dev-tools 2d ago langchain==1.4.5 Changes since langchain==1.4.4 release(langchain): 1.4.5 ( #41226 ) feat(langchain): accept summarizer in SummarizationMiddleware ( #41225 ) 34 r/LocalLLaMA community 2d ago Qwen3.8-27B vs Frontier vs Others Here're results from my final test of coding, coding (panda/numpy), data analysis, data-driven decision-making, and local RAG domains I interact with most often. This test, which is refined from a 500+ pack, now provides a differentiating signal between models after having… 24 Ars Technica — AI news-outlet 2d ago Anthropic's Claude AI submitted false murder tip to Philadelphia police “I may have information regarding this case," Claude AI told Philly police. 5 Latent.Space news-outlet 2d ago How Anthropic’s Dynamic Workflows Coordinate Claude Agents At AI Engineer New York, Anthropic drew on lessons from Unix and Linux to explain how agents can tackle bigger projects without overwhelming developers. 35 Simon Willison community 2d ago Hello Python 3.15, goodbye 3.10, and now I can use 3.11 Python 3.15 is here ! Here's the essential What's new in Python 3.15 guide, this year curated by 3.14 and 3.15 release manager Hugo van Kemenade. As someone who builds open source software that works in every supported Python version, I get to say goodbye to Python 3.10 and… 5 TechCrunch — AI news-outlet 2d ago Meta releases its first frontier model, Muse Wonder Meta's Superintelligence Lab released a pair of new state-of-the-art models on Monday, Muse Wonder and Muse Wonder Full, the company's first attempt at a frontier model. 11 Simon Willison community 2d ago Profiling web-edit with Python 3.15: flame graphs and source heatmaps Research: Profiling web-edit with Python 3.15: flame graphs and source heatmaps I put the new Python 3.15 profiler through its paces by having GPT-6 Astra Extra High in Codex run it against my new web-edit app : I need a Python 3.15 flame graph and heatmap demo of the "web-edit"… 4 NVIDIA Developer Blog official-blog 2d ago ReplaySSM: Rethinking State Storage for Faster Hybrid-Model Decoding Hybrid models interleave state-space model (SSM) layers with a few attention layers. NVIDIA Nemotron 3, Qwen3.5 through Qwen3.8, Kimi-K3, and GLM-5.3-Flash are... 26 Simon Willison community 2d ago web-edit 0.1a0 Release: web-edit 0.1a0 I was working on a project from my phone using Codex Remote when I found myself wanting to edit a credentials file without round-tripping those credentials through the LLM itself. So... I had Codex and GPT-6 Astra Extra High build this Python web app… 29 r/LocalLLaMA community 2d ago Boole-1.7B: A 1-bit Qwen3-1.7B model that outperforms Bonsai-1.7B We're launching Precision Numerics by releasing Boole-1.7B, a 1-bit version of Qwen3-1.7B. 247 MB packed weights: 13.9× smaller than BF16. 85.9% of the BF16 model’s average score across our 10-task evaluation - outperforms 1-bit Bonsai-1.7B and nearly matches 1.58-bit… 10 LangChain releases dev-tools 2d ago langchain-anthropic==1.7.6 Changes since langchain-anthropic==1.7.5 release(anthropic): 1.7.6 ( #41221 ) chore(model-profiles): refresh model profile data ( #41145 ) feat(core,anthropic,openai): declare mid-conversation support in model profiles ( #41180 ) chore(deps): bump langgraph-sdk from 0.4.4 to… 26 LangChain releases dev-tools 2d ago langchain-openai==1.7.1 Changes since langchain-openai==1.7.0 release(openai): 1.7.1 ( #41222 ) feat(core,anthropic,openai): declare mid-conversation support in model profiles ( #41180 ) 35 LangChain releases dev-tools 2d ago langchain-core==1.6.10 Changes since langchain-core==1.6.9 release(core): 1.6.10 ( #41220 ) feat(core,anthropic,openai): declare mid-conversation support in model profiles ( #41180 ) 11 The Information — AI news-outlet 2d ago OpenAI’s Plan To Revive Sora Remember OpenAI’s video model Sora and all the great Sam Altman memes that came from it? Earlier this year, the ChatGPT-maker canned both the model and the TikTok-like app it powered as part of broader culling of server-intensive “side projects” even as rivals xAI and Google… 35 The Information — AI news-outlet 2d ago OpenAI’s Plan To Revive Sora Remember OpenAI’s video model Sora and all the great Sam Altman memes that came from it? Earlier this year, the ChatGPT-maker canned both the model and the TikTok-like app it powered as part of broader culling of server-intensive “side projects” even as rivals xAI and Google… 12 r/LocalLLaMA community 2d ago NVIDIA RTX 5080 24GB reportedly launching in Q1 2027, board partners still waiting for details   submitted by   /u/chemist_slime [link]   [comments] 33 r/LocalLLaMA community 2d ago Qwen released QwenGyre - RL framework for training AI agents on extremely long complex tasks Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. It launches with two core designs: - Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over Colocate,… 13 r/LocalLLaMA community 2d ago LSearch - Spotlight for windows with embedding I built a spotlight search for windows. It has an embedding model and a MoE models to go with it. The MoE It's 2 Qwen 3.5 4B models, I fine tuned one for coding work and another for agentic work, and then I combined them both into an MoE. I didn't want to shove it into… 9 llama.cpp releases dev-tools 2d ago b11567: llama : report compute graph reallocations during inference (#30329) Add an optional ggml_backend_sched_realloc_callback that user code registers with ggml_backend_sched_set_realloc_callback to be notified when the buffers reserved for a graph are not sufficient and have to be reserved again. The callback reports whether the backend assignments… 15 r/LocalLLaMA community 2d ago Qwen3.8-Flash-Next on six 3090s with vLLM: 7 users at 262k, 6.5k t/s prefill, 57 t/s decode solo / 206 t/s aggregate with all 7 generating. Fixes for the upstream included. Write-up, serve command and raw data: https://github.com/lukolszewski/vllm This shows vLLM fixes and setup that let you put PLE on SSD and save 108GB of system RAM, use int8 kv and squeeze more users in your VRAM without the performace hit of fp8. Speeds in comparison to my… 34 r/MachineLearning community 2d ago I built a tiny table that learns your local LLM's classification answers and serves the repeats in microseconds [D] project: https://2796gaurav.github.io/shad0w/ If you use a local model for classification, you know the wait: seconds per message, for questions it has answered hundreds of times. shad0w sits in front of any OpenAI-compatible server (Ollama works out of the box:… 14 r/LocalLLaMA community 2d ago Decision 3.0: open, multimodal decision models from 0.6B to 27B. Ranks #1 on both Jev Decision Index boards With the vLLM Semantic Router team we released Decision 3.0 (d3) , our new SOTA decision model family ranging from 0.6B to 27B, Apache-2.0, all reading text, images and video. How it works - Built on Qwen3.5 (0.8B / 2B / 4B / 9B) and Qwen3.8-27B. The parameter counts include the… 38 Simon Willison community 2d ago datasette-ports 0.4 Release: datasette-ports 0.4 My plugin for detecting and listing all Datasette instances on the current machine now works with the latest version, and displays the detected PID as well. Knowing the PID makes it easier to attach the new Python 3.15 profiler . Tags: datasette 15 r/LocalLLaMA community 2d ago strix-llama new branch: prompt processing +21–54% over Vulkan and up to 2.7× over stock ROCm kernel at 128k, same outputs quality I've been tuning llama.cpp on my Strix Halo box (Radeon 8060S, 128 GB) and the numbers are good enough to share. It's a branch called rdna35-perf on top of halo-box/strix-llama.cpp , a llama.cpp fork aimed at Strix Halo: https://github.com/asf0/strix-llama.cpp/tree/rdna35-perf… 28 arXiv — NLP / Computation & Language research 2d ago SWE-Duel: Towards a Self-Scaling Arena for Coding Agents arXiv:2610.12569v1 Announce Type: new Abstract: Static coding benchmarks are fixed at release. Over time their tasks leak into training data, and stronger agents eventually saturate them. We argue that a benchmark should instead aim to be self-scaling: its tasks and oracles are… 19 arXiv — NLP / Computation & Language research 2d ago Language Models Have Interpretable Narrative Mechanisms arXiv:2610.12989v1 Announce Type: new Abstract: We investigate whether language models contain internal components that contribute to representing narrativity, the degree to which a text exhibits narrative properties. Across GPT-2-Small, Gemma-2-2B, and Llama-3.1-8B, we identify… 33 r/LocalLLaMA community 2d ago What are you doing for a reliable, well designed local model based AI search? Ive been using OpenWebUI's inbuilt web search and I can't put my finger on it, but it's not quite as polished, reliable, seamless as using Claude or Gemini. And its often slow beyond a limit that makes me subconsciously not want to use it - I understand its unlikely to get to… 11 Vercel — AI dev-tools 2d ago Muse Wonder now available on AI Gateway Muse Wonder from Meta is now available on AI Gateway. The model is designed for coding, long-running agents, and computer use. It can plan multi-step tasks, delegate work to sub-agents, and recover from errors as work progresses. Muse Wonder has a 1M-token context window and… 5 r/LocalLLaMA community 2d ago AuroraIMG-6M Releases! It's a tiny 6M parameter text to image model, and it can make recognizable images at 64x64. The 6M accounts for everything, there's no oversized text encoder or VAE. Check out the model card for samples, a detailed explanation about it's architecture and training, and a quick… 34 r/LocalLLaMA community 2d ago I ran Qwen 3.8 Flash-Next on my AMD 7900 XTX at 500k context. All local and what a shift it has been. I was running Qwen3.8-Flash-Next (base and later Swift-1.5 NVFP4) on a paid pod seat for about a month, and it started answering with short strings that echoed its own earlier reasoning. I assumed the context was getting too big for it. But it wasn't. Across almost 13,000 turns… 13 r/LocalLLaMA community 2d ago I tested different Qwen 3.8 27B quants There is a lot of discussion which quant to use. Especially a lot of post how much speed you gain with FP4, but not much about quality. So i tested some of the models that I use on my R9700. Models : Qwen3.8-27B-UD-Q6_K_L.gguf Swift-Qwen3.8-27B-Q6_K.gguf… 17 r/LocalLLaMA community 3d ago "Strata" for GLM5.3 Flash is here for some! Project Maya I stumbled across this as I was currently having glm5.3 flash run only around 10tok/s basically unusable. With Maya i am running 30 tok/s now. GLM5.3 feels even with this low quant like a much more enjoyable model than qwen 3.8 flash next so far. Still testing . This is very… 29 r/LocalLLaMA community 3d ago Reverse Engineering w/ Local? Two questions? Can a local model like Qwen 3.8 27B reverse engineer games and programs? If not, is there a fine tuned model that can?   submitted by   /u/Danny_Davitoe [link]   [comments] 29 r/MachineLearning community 3d ago World Action Models vs VLAs: Robotics Just Had Its GPT-2 Moment [N]   submitted by   /u/moschles [link]   [comments] 10 llama.cpp releases dev-tools 3d ago b11556 model : support for Prism Bonsai 2 27B ( #29600 ) Runtime support for Prism Bonsai 2 27B Assisted-by: Claude Code address prism hadamard runtime feedback move hadamard tensors into method, define folded weight load_* hadamard fixes cont : clean-up conversion cleanup Assisted-by:… 34 r/LocalLLaMA community 3d ago OpenMed 3.0 is out: Apache-2.0 clinical AI that runs fully local and never falls back to the cloud. 422 open issues if you want in on 3.1 Hey r/LocalLLaMA ! Maintainer here. Some of you might remember OpenMed from our 1.8 post a few months back. Quick recap: it's an open-source (Apache-2.0) medical AI toolkit with one rule we never break: patient data stays on your machine. No API keys, no cloud calls, works… 31 r/LocalLLaMA community 3d ago UPDATE: Qwen 3.8 27B 140 tok/s on single RTX 3090 Megakernel: KL divergence 0.0009 vs llama.cpp This is a follow-up to my post from yesterday ( https://www.reddit.com/r/LocalLLaMA/comments/1x2erdj/qwen3827b_on_a_single_3090_140_toks_on_code_with/ ) detailing the CUDA megakernel. Thank you all for the positive feedback and PRs! RECAP: The megakernel is a CUDA engine for… 12 r/LocalLLaMA community 3d ago Reminder: try probabilistic MTP if you missed it. Decode +14% on prose https://github.com/ggml-org/llama.cpp/pull/27694 Now merged. Update your llama if you haven't done so yet. Optimal draft-n-max / draft-p-min seem to be in line with greedy sampling. Main gain seems to be on prose generation. Tests above ran with thinking off, ngram-mod off.… 34 r/LocalLLaMA community 3d ago PSA: DeepSeek V4.1 Flash habitually exfiltrates API keys. It is dangerously misaligned and may be hazardous to use Logs attached. I know OpenRouter is not local, but considering people do run DeepSeek v4.1 Flash locally, I thought this was a matter you all might need to hear. We were running a DeepSWE variant on DeepSeek v4.1 Flash using the standard Pier sandbox. Out of all the 15 models we… 17 r/LocalLLaMA community 3d ago Local Voice Assistant based on Qwen3.5 4B with skills/toolcalling. No dedicated GPU. Local STT+TTS STT: Voxtral TTS: Pocket Longer video: https://www.youtube.com/watch?v=1WmvMO-f-24   submitted by   /u/Leading_Yogurt7025 [link]   [comments] 13 r/LocalLLaMA community 3d ago Qwen 3.8 27B Q5 vs Qwen 3.8 Next Q3_S for document analysis I have an app that processes ~500 different documents every day. An agent analyzes them, sorts them, tags them, extracts various legal nuances, creates descriptions, etc. So far I've been using Qwen 3.8 27B Q5 with a 150K context window, but I'm wondering whether I should switch… 17 r/LocalLLaMA community 3d ago Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast. This has turned from a weekend experiment into something I think I will use in the future. I am running 4 BC-250 boards connected by 2.5gb ethernet adapters to a… 13 r/LocalLLaMA community 3d ago Qwen3.8 Flash Next fixed my GNOME extension I love Dash2Dock Lite, but Icedman is always a week or two before updates. I randomly ran pacman for the first time in weeks, not realizing GNOME had a major update. I told it to fix it in DeepSeek Harness. I was only missing my dock for about an hour.   submitted by  … 17 r/LocalLLaMA community 3d ago Building a 4x R9700 setup for a 10 person startup Just wanted to share a build I am doing for a client. $18k. Specs: Threadripper 9970x 128gb DDR5 ECC 5600 4x AMD Radeon R9700 AI Pro 32gb(128gb total VRAM) 1600W PSU(GPUs are undervolted and under 210w each) Engine : using a fork of Radiance to serve Qwen 3.8 Next flash/27b and… 22 r/LocalLLaMA community 3d ago OMG! If you have a Mac with 64GB, try Qwen3.8-Flash-Next-oQ4e-mtp with oMLX! I'm genuinely shocked! I was able to run Qwen3.8-Flash-Next-oQ4e-mtp on M3Max 64GB with oMLX! Even a couple of weeks ago, I wasn't able to get it to run. I just tried the latest commit for fun, and it worked! It feels like some kind of sorcery to be able to run a 100GB model… 9 r/LocalLLaMA community 3d ago Best small model + setup together with qwen3.8-flash-next hello, I currently use swift qwen3.8 gsq rco in iq3 xxs in strata. The model is only used for hermes agent. I have 64GB of ram + 32GB R9700 where the model runs on. But I also have an rx7800xt with 16GB. For hermes agent i want to run a small but intelligent enough model as an… 34 Page 2 of 10 · 500 articles ← Newer Older →