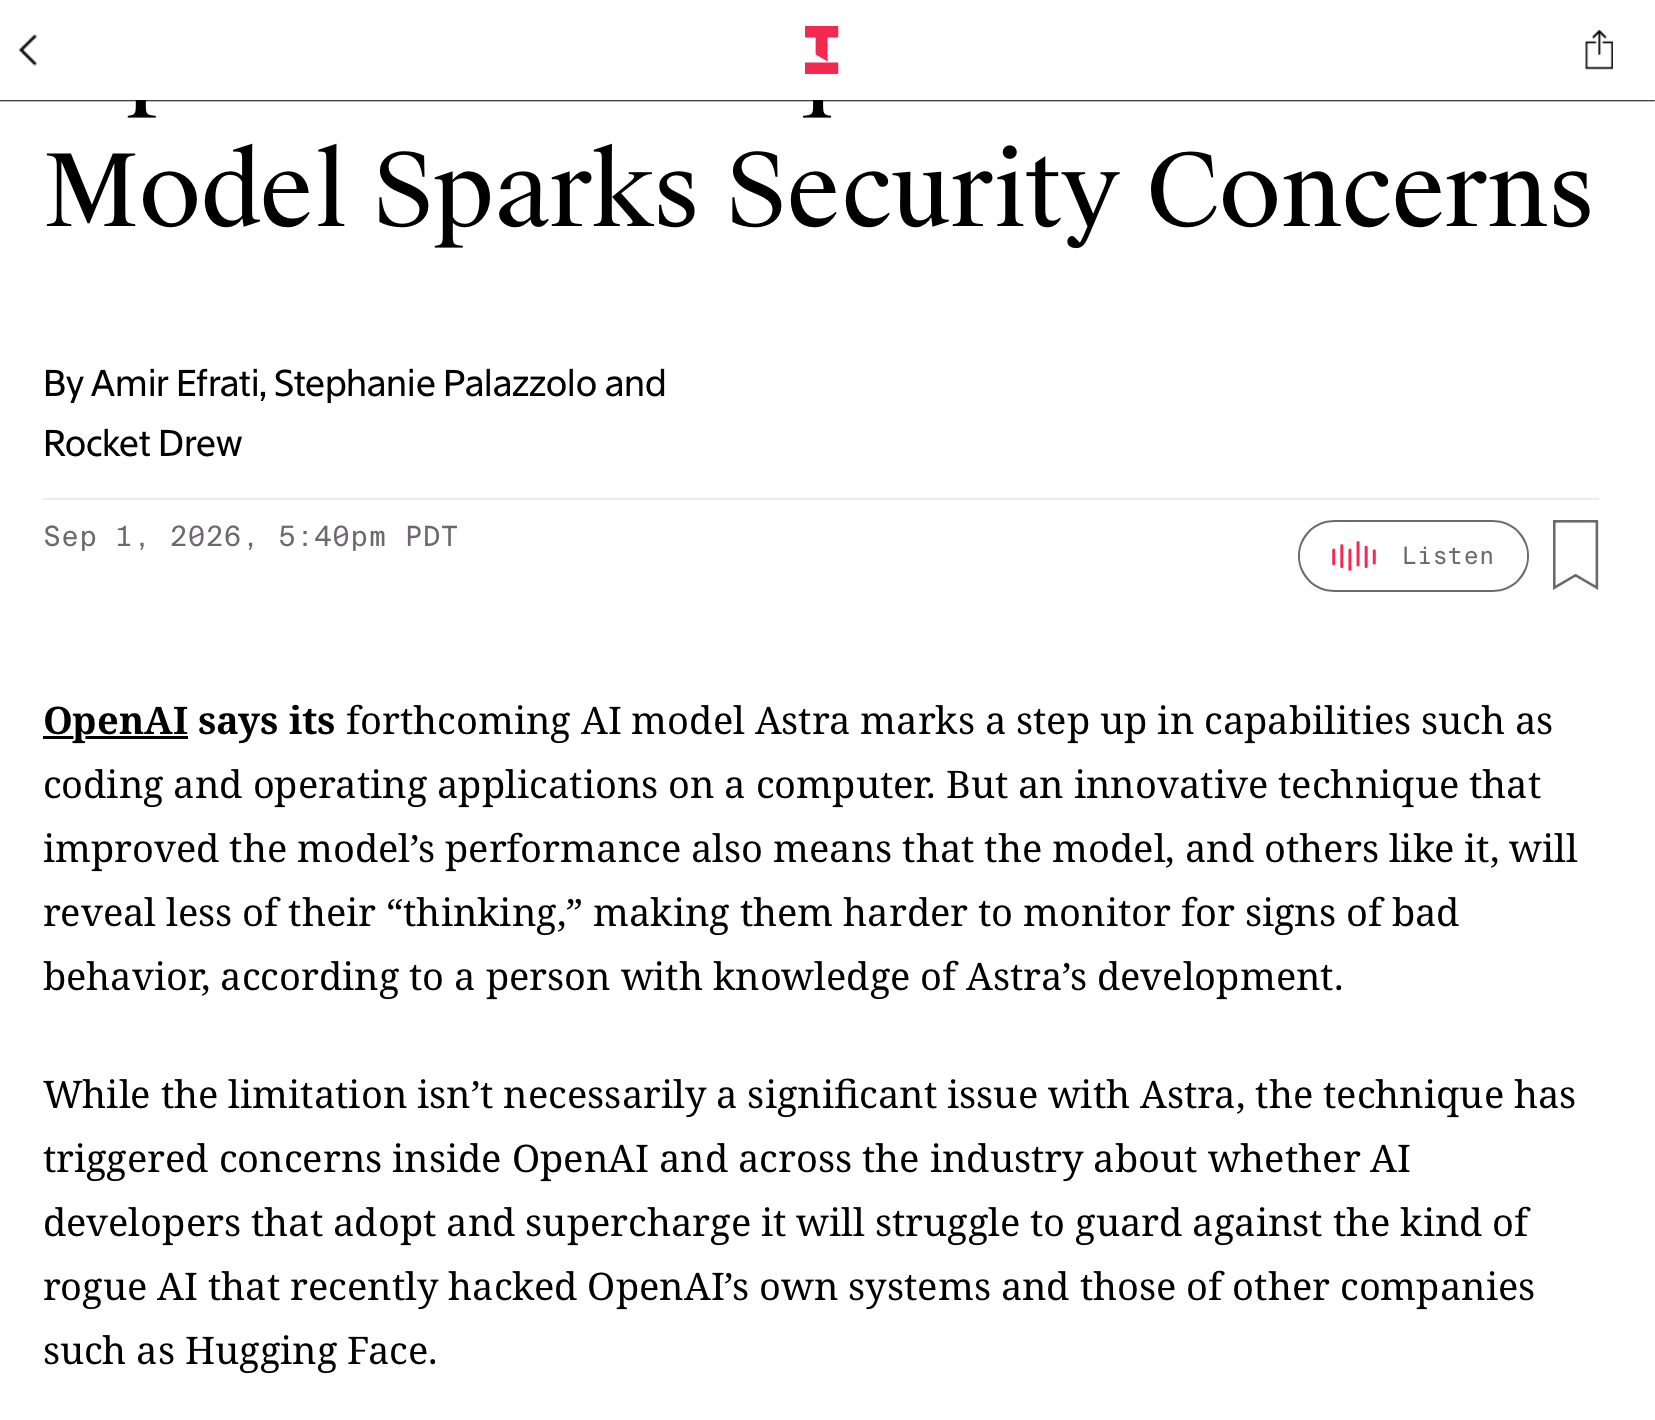
News / #safety Tag Safety + alignment 500 articles archived under #safety · RSS Sign in to follow arXiv — NLP / Computation & Language research 1mo ago Thinking effort aligns between humans and reasoning models in abductive reasoning arXiv:2609.01867v1 Announce Type: new Abstract: A major question in cognitive modeling concerns the behavioral alignment between large language models and humans across linguistic and non-linguistic tasks. Unlike standard LLMs, large reasoning models (LRMs) are optimized with… 6 arXiv — NLP / Computation & Language research 1mo ago Selective Knowledge Edit Reversal via Gated Singular Vector Shrinkage arXiv:2609.02091v1 Announce Type: new Abstract: Knowledge editing provides an efficient way to update factual knowledge in large language models. However, malicious edits may introduce safety risks, making it necessary to reverse undesirable editing effects. Existing reversal… 24 arXiv — NLP / Computation & Language research 1mo ago Breadth Beats Depth: Improving GCG-Based Jailbreak Optimization with Breadth-Oriented Suffix Search arXiv:2609.02172v1 Announce Type: new Abstract: Optimization-based jailbreak attacks such as Greedy Coordinate Gradient (GCG) achieve strong effectiveness and transferability by optimizing adversarial suffixes on white-box source models. However, existing GCG-based methods rely… 10 arXiv — NLP / Computation & Language research 1mo ago Before the Script, Set the Stage: How Worldview Simulation Amplifies Psychologically Grounded Persuasion in Multi-Turn Jailbreaking arXiv:2609.02414v1 Announce Type: new Abstract: Multi-turn jailbreak attacks demonstrate that harmful intent can be distributed across dialogue, yet existing methods obscure what conversational mechanisms drive vulnerability. We introduce BLUEPRINT, a safety-evaluation framework… 37 arXiv — NLP / Computation & Language research 1mo ago PragAlign: Feedback-Guided Pragmatic Alignment for Controlled Synthetic Dialogue Generation arXiv:2609.02480v1 Announce Type: new Abstract: Synthetic dialogue generation can support research in privacy-restricted service settings, but generated conversations must preserve communicative intent, affective meaning, and natural dialogue flow. We introduce PragAlign, a… 14 arXiv — NLP / Computation & Language research 1mo ago When Persona Attributes Improve Population Alignment in Large Language Models arXiv:2609.02526v1 Announce Type: new Abstract: Large Language Models (LLMs) are increasingly used to predict the responses of human participants in survey panels. Towards that goal, persona prompting has recently emerged as a technique to inform and align large pretrained… 16 arXiv — NLP / Computation & Language research 1mo ago Accurate in space, unreliable in time: how LLMs represent national cultural change arXiv:2609.01902v1 Announce Type: cross Abstract: Assessments of cultural alignment have become an important part of the development and improvement of large language models (LLMs). However, the majority of the evaluations treat culture as a single snapshot, investigating only… 15 arXiv — NLP / Computation & Language research 1mo ago Transfer Safety Awareness for Cross-Modal Safety Drift in Multimodal Large Language Models arXiv:2609.02082v1 Announce Type: cross Abstract: Visual modality enhances the capabilities of multimodal large language models (MLLMs) but also introduces a safety concern: a benign textual query may convey harmful intent when grounded in a visual image. We term this… 35 arXiv — NLP / Computation & Language research 1mo ago Improving Evaluation Realism with Inference-Time Compute and Deployment Scaffolds arXiv:2609.02302v1 Announce Type: cross Abstract: A core obstacle to alignment evaluation is evaluation awareness: capable models can tell when they are being tested rather than deployed, weakening the conclusions a safety evaluation can support. We present two techniques that… 8 arXiv — NLP / Computation & Language research 1mo ago SALA: Semantic-Aware Logical Alignment for Complex Reasoning in In-Context Learning arXiv:2609.02336v1 Announce Type: cross Abstract: Effective in-context learning (ICL) for complex reasoning relies on selecting the right demonstrations. Traditional retrieval methods based on surface similarity fail to capture the underlying problem-solving logic. Recent… 21 OpenAI official-blog 1mo ago Safety overview: GPT-6 Astra GPT-6 Astra is our most capable broadly deployed model and our first to reach the Critical level of cybersecurity capability under our Preparedness Framework. 22 Hugging Face Daily Papers research 1mo ago Does Imitation Learning Preserve Temporal Robustness in Dexterous Manipulation? An Expert-Learner Comparison Across Task Execution Speeds Abstract Imitation-learned dexterous manipulation policies degrade more sharply than expert policies when execution speed increases, with insertion misalignment being the primary failure mode. Generated by thinkingmachines/Inkling-Small Dexterous manipulation policies learned by… 21 TechCrunch — AI news-outlet 1mo ago OpenAI’s new reasoning technique alarms AI safety experts OpenAI’s new Astra model will use “recurrent depth,” a technique that allows the model to operate outside of the sequential thinking that characterizes most reasoning models. 35 Hugging Face Daily Papers research 1mo ago AgentJudgeBench: A Multi-Difficulty Benchmark for Evaluating LLM Judges on Agentic Tool-Calling Abstract AgentJudgeBench reveals that LLM judges face structural reliability limits on dependency-driven agentic tool-calling workflows, with alignment degrading by difficulty and ground-truth exposure yielding mixed effects. Generated by thinkingmachines/Inkling-Small LLM… 32 Ars Technica — AI news-outlet 1mo ago Trump may be forced to reveal secret rules feds use for AI safety testing Trump’s secret reviews of frontier AI models may hide corruption, lawsuit says. 11 Don't Worry About the Vase community 1mo ago Anthropic Has Some Alignment Problems Oh, good. 7 r/LocalLLaMA community 1mo ago Your favorite fastest abliterated/safety removed 3.6 and 3.8 27b? Not written by AI all mistakes mine. I saw people on the subreddit saying that 3.6 works better without thinking . It made me want to know for certain about which is better, 3.6 or 3.8 for low thinking tasks. I only use abliterated models (safety removed) because it makes the… 21 arXiv — Machine Learning research 1mo ago Assessing Alignment and Stability of Feature Importance Explanations via Weight of Evidence arXiv:2609.00090v1 Announce Type: new Abstract: Feature importance Methods (FIMs) are widely used in Explainable AI to interpret model predictions, yet attribution scores alone often provide limited insight into the underlying reasoning process. In this work, we introduce a… 38 arXiv — Machine Learning research 1mo ago Safin-1: Safety from Within through Memory-Native State Evolution arXiv:2609.00092v1 Announce Type: new Abstract: Long-horizon complex tasks require foundation models to accumulate information, maintain internal states, and adapt over extended interactions. Safety should be an intrinsic property of the model itself, rather than a behavioral… 27 arXiv — Machine Learning research 1mo ago Do LLMs Know Your Neighborhood? Auditing LLM Priors for Neighborhood-Level Mobility Prediction and Structural Alignment arXiv:2609.00345v1 Announce Type: new Abstract: Human mobility is central to urban planning, transportation, public health, and emergency response, yet fine-grained trajectory data are often proprietary, restricted, and privacy-sensitive. Large language models (LLMs) offer a… 28 arXiv — Machine Learning research 1mo ago Confess What You Know: Forget-Set Misalignment with Model Knowledge in LLM Unlearning arXiv:2609.00605v1 Announce Type: new Abstract: Machine unlearning for large language models (LLMs) often assumes that a pre-defined forget set matches what the model has memorized, but this frequently breaks in realistic privacy settings where the original training data is… 18 arXiv — Machine Learning research 1mo ago The Constitutional Coverage Trilemma in AI Governance arXiv:2609.01275v1 Announce Type: new Abstract: Frontier AI systems function as \emph{constitutional institutions}: each deployed model encodes an implicit ranking among safety, helpfulness, honesty, autonomy, and equity. We ask whether the supply of frontier constitutional… 6 arXiv — NLP / Computation & Language research 1mo ago Behaviorally Grounded User Profiles from the Wild for Personalized Alignment and Multi-Perspective Reasoning arXiv:2609.00014v1 Announce Type: new Abstract: Persona-driven techniques increasingly adapt large language models (LLMs) to diverse contexts. However, existing methods predominantly rely on rigid, synthetic personas that flatten individual variation, rely on stereotypes, and… 35 arXiv — NLP / Computation & Language research 1mo ago From Detection to Refusal: Safer LLMs via Circuit-Guided Weight Scaling arXiv:2609.00051v1 Announce Type: new Abstract: Despite extensive alignment efforts, Large Language Models (LLMs) remain vulnerable to generating unsafe content under adversarial prompting, yet the internal mechanisms by which safety behaviors are implemented remain poorly… 6 arXiv — NLP / Computation & Language research 1mo ago Zero-Shot Respiratory Sound Classification through LLM-Augmented Audio-Text Alignment arXiv:2609.00055v1 Announce Type: new Abstract: Self-supervised respiratory encoders lack semantic grounding in clinical domain needed for zero-shot inference, limiting their utility without task-specific labeled data. We propose a framework that aligns these encoders with… 33 arXiv — NLP / Computation & Language research 1mo ago Beyond Token Positions: Safety Alignment Across Denoising Steps in Diffusion Language Models arXiv:2609.00495v1 Announce Type: new Abstract: Diffusion large language models (dLLMs) generate text through iterative denoising rather than left-to-right decoding. This generation paradigm introduces two axes that can influence safety alignment: when tokens are generated… 34 arXiv — NLP / Computation & Language research 1mo ago Trust Your Guide Only When Certain: Uncertainty-Aware Sparse Alignment at Inference Time arXiv:2609.00624v1 Announce Type: new Abstract: A prominent paradigm in inference-time alignment employs lightweight supervisors to steer Large Language Models (LLMs). Through empirical analysis, we identify a structural mismatch in this paradigm: weak supervisors exhibit… 14 arXiv — NLP / Computation & Language research 1mo ago A Unified Mechanistic Analysis of Knowledge- and Safety-Based Refusals arXiv:2609.00760v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly trained to decline queries that fall outside their knowledge (knowledge-based refusal, KR) or violate safety policies (safety-based refusal, SR). Although KR and SR result in… 4 arXiv — NLP / Computation & Language research 1mo ago Post-hoc Alignment of LLM-judges to Human Judgment Distribution arXiv:2609.01073v1 Announce Type: new Abstract: The LLM-as-a-judge (LLMaJ) framework offers a cost-effective and reproducible solution for automatic evaluation. However, current evaluation practices typically compare LLMaJ judgments against aggregated ground-truth labels,… 4 arXiv — NLP / Computation & Language research 1mo ago When Modality Gap Reduction Fails: Prediction-Level Hubness in CLIP arXiv:2609.01103v1 Announce Type: new Abstract: Reducing the modality gap between image and text representations in CLIP is widely expected to improve cross-modal alignment and downstream performance. However, a smaller average image-text gap does not necessarily lead to… 27 Marcus on AI community 1mo ago Red Alert: OpenAI is poised to cross an AI safety redline. Making models harder to monitor is not what we need 9 Hugging Face Daily Papers research 1mo ago Safin-1: Safety from Within through Memory-Native State Evolution Abstract Safin-1 introduces a memory-routing architecture that embeds safety as an internal, evolving model state rather than an external constraint. Generated by thinkingmachines/Inkling-Small Long-horizon complex tasks require foundation models to accumulate information,… 21 Hugging Face Daily Papers research 1mo ago ReFlowSET: Representation-Aligned Latent Flow Matching for SAR-to-EO Image Translation Abstract ReFlowSET selects a latent codec via joint SAR-EO reconstruction and trains a small conditional DiT with dual-stream conditioning and frozen vision-model alignment for high-fidelity SAR-to-EO translation. Generated by thinkingmachines/Inkling-Small SAR-to-EO image… 15 Hugging Face Daily Papers research 1mo ago SafeAtlas-VL: Beyond Binary Multimodal Safety with Large-Scale Data and Guard Models Abstract SafeAtlas-VL introduces a large-scale multimodal safety dataset with graded risk labels and trains guard models that predict continuous safety scores, achieving state-of-the-art generalization. Generated by thinkingmachines/Inkling-Small Multimodal safety moderation… 30 arXiv — Machine Learning research 1mo ago Unsupervised Latent Space Alignment with Hyperspherical Geodesic Matching arXiv:2608.28840v1 Announce Type: new Abstract: Independently trained neural networks tend to encode the same data with similar latent geometries. These latent geometries are not directly compatible, yet they can be nearly the same up to some class of transformations. While… 19 arXiv — Machine Learning research 1mo ago PathGuide: Dynamic Classifier-Free Guidance via On-Policy Transport Alignment arXiv:2608.29107v1 Announce Type: new Abstract: While modern generative models excel at modeling complex data, precise inference-time control in conditional generation remains a critical challenge. Classifier-free guidance (CFG) is a primary mechanism for such control, yet it is… 31 arXiv — Machine Learning research 1mo ago Reference-Grafting Matches Fine-Tuning at Eliciting Sandbagged Capabilities arXiv:2608.29458v1 Announce Type: new Abstract: Sandbagging, in which a model deliberately underperforms on an evaluation despite retaining the underlying capability, threatens the safety evaluations that frontier-model governance depends on. The Elicitation Game found that… 14 arXiv — Machine Learning research 1mo ago Unsupervised Multi-Scale Gromov-Wasserstein Hypergraph Alignment arXiv:2608.29635v1 Announce Type: new Abstract: We study unsupervised hypergraph alignment, where the goal is to infer node correspondences between two hypergraphs using only structural information, without node features, labels, seed matches, or side information. Direct… 15 arXiv — Machine Learning research 1mo ago Structure Aware Neural Architecture Search for Mixture of Experts arXiv:2608.29817v1 Announce Type: new Abstract: Neural Architecture Search (NAS) has so far rarely been applied to Mixture-of-Experts (MoE) models, and existing MoE designs leave the alignment between experts and the structure of the data to emerge on its own. We propose an… 31 arXiv — NLP / Computation & Language research 1mo ago Recognition-Refusal Misalignment in LLMs: Why Models Answer Structurally Unanswerable Questions arXiv:2608.29109v1 Announce Type: new Abstract: Large language models often answer structurally unanswerable questions, such as computing cot(-540{\deg}) or evaluating (1).startswith("1"), instead of abstaining. We ask whether this failure reflects missing recognition or failed… 23 arXiv — NLP / Computation & Language research 1mo ago Toward Cultural Alignment: Human-Centered Evaluation of Multimodal AI Stories Across Five African Communities arXiv:2608.29209v1 Announce Type: new Abstract: In this paper, we examine how well AI-generated multimodal stories align with the lived practices, relationships, language, values, and visual expectations of the communities they represent. We conduct a community-grounded… 28 arXiv — NLP / Computation & Language research 1mo ago When Patients Cut In: Extending Clinical Conversational AI Safety to Interruptions arXiv:2608.29241v1 Announce Type: new Abstract: Clinical voice agents are now deployed in routine care, where real patients do not wait their turn: they interrupt. These systems typically use a cascaded architecture (speech-to-text -> LLM -> text-to-speech), so when a patient… 17 arXiv — NLP / Computation & Language research 1mo ago SHADOWBENCH: Toward Reliable Automatic Evaluation of Semantic Alignment in Autoformalization arXiv:2608.29270v1 Announce Type: new Abstract: Autoformalization translates informal mathematical theorems into code for proof assistants such as Lean. A central challenge is that current evaluation metrics can accept type-correct but misaligned statements or reject correct… 6 arXiv — NLP / Computation & Language research 1mo ago Arabic Safety Alignment as Selective Refusal: An Empirical Study of SFT, DPO, and Guard Calibration arXiv:2608.29378v1 Announce Type: new Abstract: Arabic large language models must refuse harmful prompts without over-refusing benign or sensitive prompts, yet a single refusal rate hides this trade-off. We evaluate it using benign refusal B and harmful-prompt refusal H, where H… 23 arXiv — NLP / Computation & Language research 1mo ago Whose Assessment of Distress? Community Perspectives and LLM Alignment on Well-Being Posts arXiv:2608.29446v1 Announce Type: new Abstract: Judgments about psychological distress are socially situated: what counts as concerning hinges on community norms around emotional expression, vulnerability, and help-seeking. Yet large language models (LLMs) used for distress… 8 arXiv — NLP / Computation & Language research 1mo ago CoCoA: Context-Conditional Cultural Alignment for Large Language Models arXiv:2608.29492v1 Announce Type: new Abstract: Large Language Models (LLMs) often favor Western-associated entities across cultural contexts. Conventional debiasing methods aim for uniform neutrality, but cultural bias mitigation demands context-conditional behavior, preferring… 17 arXiv — NLP / Computation & Language research 1mo ago Argument-Aware Semantic Alignment of Normative Texts: A Toulmin-Based Neuro-Symbolic Approach arXiv:2608.29529v1 Announce Type: new Abstract: Semantic alignment between specialized normative texts is challenging when equivalent requirements use different terms, syntax, and levels of abstraction. Lexical overlap, distributional embeddings, and semantic similarity capture… 25 arXiv — NLP / Computation & Language research 1mo ago TACS: Trajectory-Aware Candidate Selection for LLM Jailbreak Suffix Optimization arXiv:2608.29564v1 Announce Type: new Abstract: Gradient-based jailbreak suffix optimization methods typically update the suffix by retaining the candidate with the lowest current loss. We show that this seemingly natural design is fundamentally myopic: candidates that look… 33 arXiv — NLP / Computation & Language research 1mo ago Beyond Surface Alignment: Grounding the Dynamics of Situational Understanding and Generative Control in LLMs arXiv:2608.29610v1 Announce Type: new Abstract: The current alignment tuning paradigm for Large Language Models (LLMs) prioritizes surface-level behaviors -- fluency, safety, and tonal consistency. While effective for casual chat, this thesis argues that such surface alignment… 7 arXiv — NLP / Computation & Language research 1mo ago R$^2$A: Learning Persona Policies Through Persona Representation Learning and Runtime Alignment arXiv:2608.29798v1 Announce Type: new Abstract: The same Persona behavior can be beneficial in one context but harmful in another, causing static Persona elicitation to perform inconsistently across tasks. We introduce the Persona Selection--Realization Framework, which models… 11 Page 8 of 10 · 500 articles ← Newer Older →