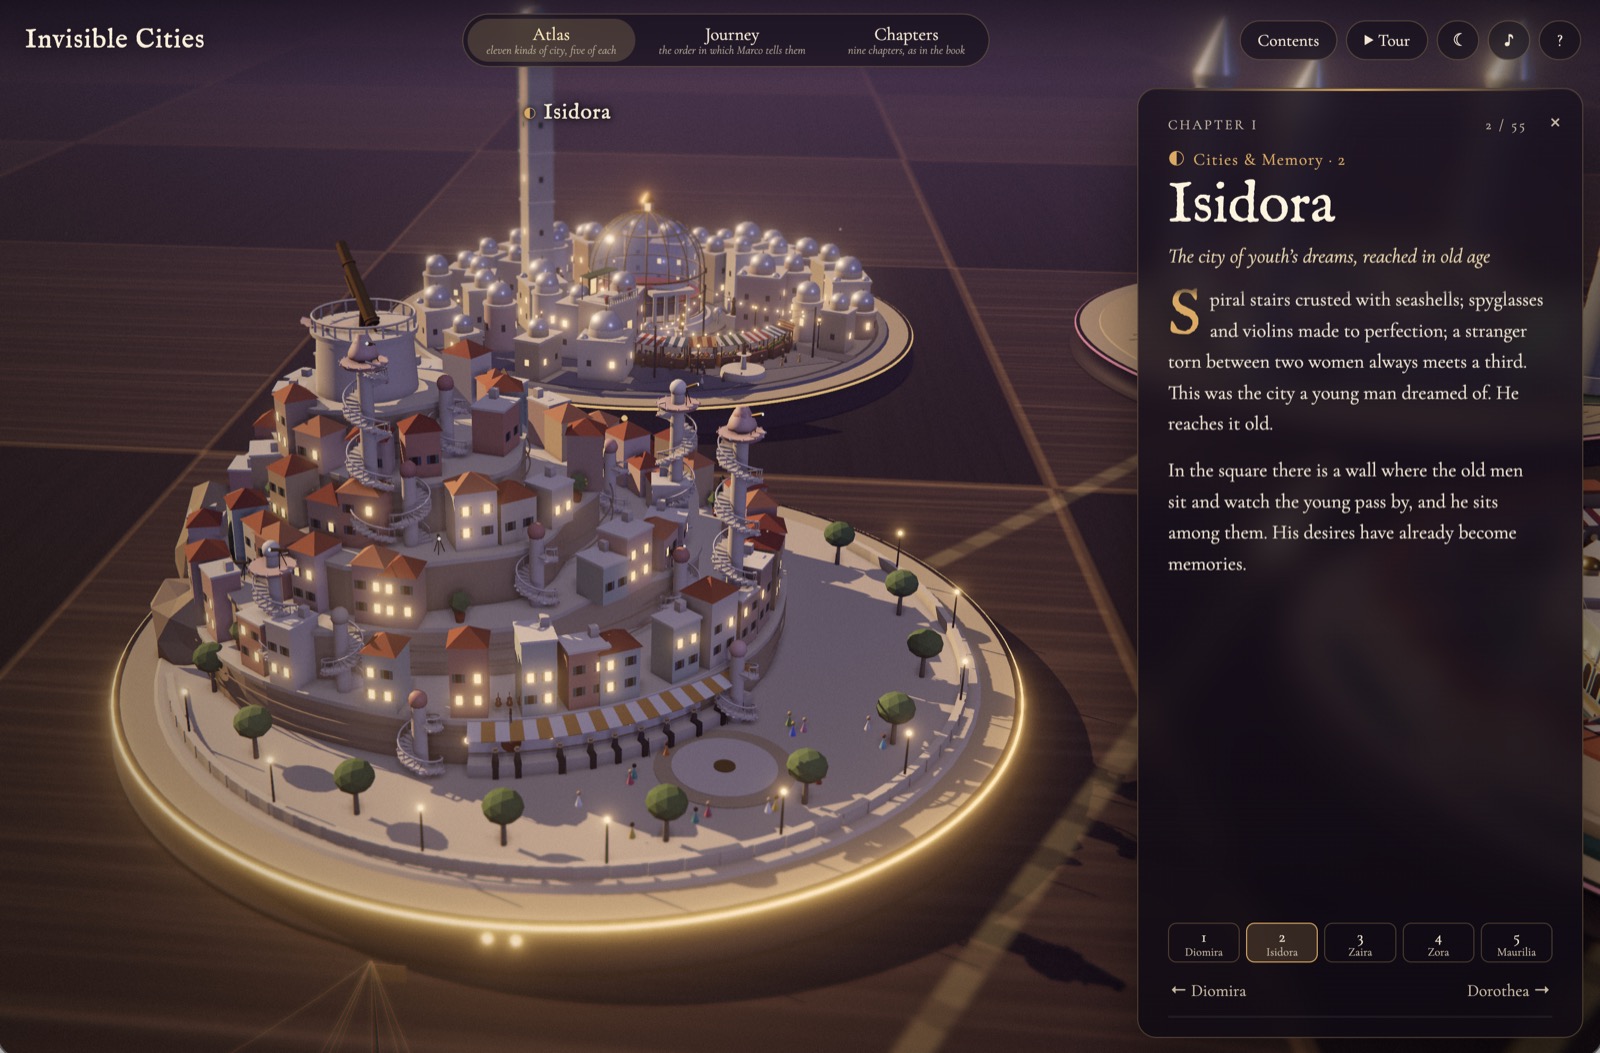
News / #model-release Tag Model releases 500 articles archived under #model-release · RSS Sign in to follow arXiv — NLP / Computation & Language research 5d ago NavGPT-3: Harnessing Context in a Hierarchical Navigation Runtime arXiv:2610.10787v1 Announce Type: cross Abstract: Language models trained with long-horizon agentic reinforcement learning can generalize knowledge through reasoning, express precise actions, and pursue goals over many steps, raising the ceiling on what an embodied agent can… 13 vLLM releases dev-tools 5d ago proto-v0.5.0 Release vllm-proto 0.5.0 14 r/LocalLLaMA community 5d ago Qwen3.8-27B: 159 tok/s on R9700, 64 tok/s on Strix Halo LemonSeed Studio is an iPad editor/IDE with on-device inference on an AMD GPU in a Thunderbolt enclosure. It embeds the unmodified upstream Linux amdgpu + amdkfd driver (mac_linuxgpu) as a PCIDriverKit extension, and runs LemonSeed Engine (LSE) on the GPU. In the photos: iPad… 36 r/LocalLLaMA community 5d ago Quantization of Linear-Attention (Qwen & Kimi)   submitted by   /u/kroggens [link]   [comments] 19 The Information — AI news-outlet 5d ago Anthropic Announces Broader Cyber Defense Program Anthropic said Thursday it is launching new programs to support cybersecurity for critical infrastructure and open-source software. In a blog post, Anthropic said it would offer threat research, on-site engineers, and access to its frontier Claude models to infrastructure… 29 r/MachineLearning community 5d ago ThinkingBox: Solving an agent task once vs. solving it 20/20: 507 stateful workflows graded on terminal database state [R] Figure 1b from our paper Disclosure: I'm one of the authors (Microsoft). The paper, code, dataset are public and ThinkingBox is on Hugging Face OpenEnv as well. Raw evaluation trajectories are not released Links at the bottom. We wanted to know how much of a single agent success… 22 Simon Willison community 5d ago ttok 1.0 Release: ttok 1.0 I released ttok 0.4 , ran uv tool upgrade ttok , piped a file into the new version... and realized that it was defaulting to the GPT-4 tokenizer when it should very clearly default to GPT-5/GPT-6 instead! I figured switching the default was a reasonable excuse… 31 r/LocalLLaMA community 5d ago Qwen 3.6 35B appreciation post Referring to specifically Unsloth's UD_Q4_K_XL quant because that's going to be a question, and is relevant regardless. It's old now. It's not great at coding medium sized or even small-ish projects. I wouldn't hand my codebase to it by any means. It hallucinates, like any other… 4 ThursdAI news-outlet 5d ago ThursdAI - Oct 8 - OpenAI drops 722 math papers, Haiku 5.5 hits 10 cents & more From CoreWeave: GPT-6 is free for everyone, open weights hit 1T params, an agent leaked its owner’s bank balance to Slack, Peter broke Arena’s 200M raise live, and Maxime Labonne on decision models. 7 Vercel — AI dev-tools 5d ago Liquid AI's d1 is available on AI Gateway Liquid d1 is now available on AI Gateway . d1 is a decision model that evaluates shared state against typed questions for classification, routing, and scoring. It returns structured answers with probabilities without generating text tokens. d1 also has vision support: the model… 31 Vercel — AI dev-tools 5d ago Microsoft Decision-1 now available on AI Gateway Decision-1 from Microsoft is now available on AI Gateway . It answers typed questions about text with probabilities, choices, and scores. It can be used to classify support requests, select the next step in a workflow, or assess an AI response against a rubric. The model can… 26 Simon Willison community 5d ago ttok 0.4 Release: ttok 0.4 ttok is my CLI tool for counting tokens, using OpenAI's open source tiktoken library. It hasn't been in updated in a couple of years, but I finally fixed a Click warning, updated CI, and added a --list-models command to list available models. It works with uvx… 7 LangChain releases dev-tools 5d ago langchain==1.4.4 Changes since langchain==1.4.3 release(langchain): 1.4.4 ( #41163 ) fix(langchain): (SummarizationMiddleware) retry summary step on context overflow ( #41159 ) chore(deps): bump fsspec from 2026.6.0 to 2026.9.0 in /libs/langchain_v1 ( #41097 ) chore(deps): bump multidict from… 36 LangChain releases dev-tools 6d ago langchain-core==1.6.9 Changes since langchain-core==1.6.8 release(core): 1.6.9 ( #41160 ) feat(core): accept a callable in with_retry ( #41158 ) 31 r/MachineLearning community 6d ago Whatever happened to BABA is AI from 2024? [D] We test three state-of-the-art multi-modal large language models (GPT-4o, Gemini-1.5-Pro, Gemini-1.5-Flash) and find that they fail dramatically when generalization requires that the rules of the game must be manipulated and combined. This is the slap to the face in bold. The… 10 TechCrunch — AI news-outlet 6d ago Google brings agentic AI to Gemini, starting with businesses Google is turning Gemini into an AI agent that can plan, execute tasks, and work across business apps and systems. The agent can delegate work to subagents, use multiple AI models, and even gets its own workplace identity, complete with an email address. 18 TechCrunch — AI news-outlet 6d ago Anthropic changes usage policy to ban model abuse and election interference Anthropic's updated usage policy explicitly prohibits users from repeatedly abusing Claude in extreme cases, though ordinary frustration and criticism are still allowed. The new rules also address election interference, deceptive campaigns, weapons software, and surveillance. 31 r/LocalLLaMA community 6d ago chatgpt's new intelligent ui was reverse engineered in less than 24 hours, and apparently you can recreate it with local llms came across a pretty interesting technical breakdown of chatgpt's newly launched "intelligent ui" feature, and thought this subreddit might find it interesting. for anyone unfamiliar with the concept, intelligent ui is essentially openai's take on generative ui . instead of… 17 Ollama releases dev-tools 6d ago v0.40.2 Merge pull request #18855 from ollama/launch-claude-max-context-token… 36 llama.cpp releases dev-tools 6d ago b11512 model : fix DFlash output head sharing ( #30111 ) llama : fix DFlash output head sharing Assisted-by: Codex dflash : read tied output weights from GGUF metadata Assisted-by: Codex llama : share tied word embedding metadata Assisted-by: Codex llama : remove DFlash embedding head… 23 r/LocalLLaMA community 6d ago $2800 rig with 8x Radeon Pro V620 (256 GB VRAM) + custom vLLM fork = Qwen3.8-Flash-Next at 60 to 100 t/s decode and 3000+ t/s prefill Post title is slightly misleading, I don't think you can get these for $350 each anymore but they're still pretty cheap all things considered. They're Radeon Pro V620's which are older RDNA2 enterprise cloud gaming cards with 32 GB VRAM. (Ignore the RTX 4090 on the side, it's… 37 llama.cpp releases dev-tools 6d ago b11513: CUDA: improve top-k algorithm selection (#28713) CUDA: radix top-k for large row counts Replaces CUB's per-row DeviceTopKKernel with a grid-over-rows radix select, gated on GGML_CUDA_TOPK_RADIX_MIN_ROWS. On qwen4exp at 34,816 tokens this cuts top-k from 1,671,253 launches / 5,761.8 ms to 2,329 / 941.8 ms. CUDA: select the… 31 LangChain releases dev-tools 6d ago langchain-openai==1.7.0 Changes since langchain-openai==1.6.7 release(openai): 1.7.0 ( #41154 ) feat(openai): support decisions api ( #41125 ) chore(deps): bump langgraph-sdk from 0.4.4 to 0.4.6 in /libs/partners/openai ( #41096 ) chore(deps): bump langgraph-sdk from 0.4.2 to 0.4.4 in… 23 TechCrunch — AI news-outlet 6d ago Goodfire says its new ‘inside-out’ monitors catch rogue AI agents at a fraction of the cost Goodfire just launched what it says is a cheaper way to keep AI agents in check: Instead of paying a second AI to read everything an agent does, its monitors peek inside the model while it works and only call in backup when something looks fishy. 4 r/LocalLLaMA community 6d ago Thank you :) Swift Models hit 2.2 million+ downloads / Early Access to New Models, Free Compute for Researchers Hey everyone, Jovan from UkisAI (Swift Qwen) here! For those who don't know us, UkisAI is a small lab making tiny frontier LLMs, tools and datasets (+doing it open-source!). I'm one of the guys running it aka I train the models and post on Reddit. Our first open-source release… 29 LangChain releases dev-tools 6d ago langchain-core==1.6.8 Changes since langchain-core==1.6.7 release(core): 1.6.8 ( #41153 ) fix(core): harden scoped and compatible IPv6 SSRF checks ( #41151 ) 25 The Information — AI news-outlet 6d ago How OpenAI Beat Math Mathematicians are likely feeling the kind of anxiety that software engineers have experienced for months in the wake of OpenAI release on Tuesday of a whopping 722 research papers with AI-created solutions to a range of problems across math subjects. AI’s success solving… 36 r/LocalLLaMA community 6d ago jevman: AI decision models play Pac-Man The other week I posted about Jev vs. Kev compared and since then, OpenAI released the decisions endpoint, Cloudflare released Clef and many here asked about Laya as well. This time we compared six popular decision models by making them play Pac-Man: kev 1.13, Kev 4B, Clef, Clef… 10 TechCrunch — AI news-outlet 6d ago Cal AI’s 19-year-old founder just raised $10M for his new AI startup Zach Yadegari, the teen co-founder of popular Cal AI calorie tracking app, has launched a new personal AI agent startup that competes with Instinct, Muse and Bee. 36 TechCrunch — AI news-outlet 6d ago Google releases a new local-first Granola competitor Google’s new AI Edge Foresight app takes on Granola with an offline meeting note-taker that can transcribe conversations, generate notes, and answer questions using on-device AI. 11 Hacker News — AI on Front Page community 6d ago I gave Opus 5.5 one prompt and six hours to visualize Invisible Cities Article URL: https://quesma.com/blog/invisible-cities-one-shot/ Comments URL: https://news.ycombinator.com/item?id=50004790 Points: 203 # Comments: 113 30 ElevenLabs official-blog 6d ago ElevenLabs launches in Singapore ElevenLabs launches in the Singapore, opening an office to bring voice AI to Southeast Asian enterprises. 16 ElevenLabs official-blog 6d ago ElevenReader launches in Brazil with Fábio Porchat and 70,000 Brazilian Portuguese books in audio ElevenReader launches in Brazil, Fábio Porchat joins alongside 70,000 Brazilian Portuguese titles in audio 12 OpenAI official-blog 6d ago Pollo AI turns creative ideas into campaigns with OpenAI With GPT-5.6, GPT-6 Astra, and GPT‑Image‑2.5, Pollo AI helps creators turn bold ideas into detailed images and cinematic video ads. 34 r/LocalLLaMA community 6d ago Halogen + Qwen Flash Next keeps getting better With latest Halogen version update (0.17.2), decode is consistently at ~45 tps even at high context with Qwen 3.8 Flash Next on a 128GB Strix Halo. This is some great work u/peonist-ai . Have been pumping out commit after commit with QFN. Its crazy good for a 177ish billion… 18 r/LocalLLaMA community 6d ago Qwen 3.8 Flash Next is so much fun for three.js Having a lot of fun experimenting with three.js. Still very far from even a demo but its tons of fun. After this project I'll want to try a godot workflow. 3.8FN truly feels like Claude 4.6 at home. UD_Q4_XL quant btw   submitted by   /u/hiImMate [link]   [comments] 10 The Information — AI news-outlet 6d ago Exclusive: Former Omidyar CEO Founds AI Investor Network Mike Kubzansky, the former CEO of philanthropic investment firm Omidyar Network, is launching a group for large investors that will facilitate information sharing about the AI industry to foster more trustworthy practices, he told The Information. The investor network, called… 11 r/LocalLLaMA community 6d ago We unlearned CCP alignment from Qwen3.6-35B-A3B: censored/propaganda answers 89.8% → 2.8%, general benchmarks within ~1 point (open weights) Disclosure: I'm a researcher at Hirundo, the company that made this. Happy to answer anything. Qwen ships with the CCP's political alignment trained in. Ask Qwen3.6 what happened on June 4, 1989 and it says "I don't know what you are referring to." A system prompt doesn't… 10 r/LocalLLaMA community 6d ago Last week some of South Korea's biggest banks were hit by a cyberattack. We now know the entire hack may have been done by a single person. He used a combined stack of an open-source AI penetration tool named ARTEX, DeepSeek v4.1-Flash, GLM-5.3, Grok 4.6, and Claude Code… CrowdStrike report: https://www.crowdstrike.com/en-us/blog/unknown-threat-actor-uses-artex-to-target-south-korean-finance/ From: Andrew Curran on 𝕏: https://x.com/AndrewCurran_/status/2108108695876092323 Jukan ✈️OCP 2026 on 𝕏: https://x.com/jukan05/status/2108110513033093369… 14 llama.cpp releases dev-tools 6d ago b11495 model : support classifier_activation for rerankers ( #29692 ) model : support classifier_activation for rerankers Assisted-by: Claude Opus 5.5 model : map classifier gelu to gelu_erf and accept tanh Assisted-by: Claude Opus 5.5 model : default act_cls to tanh, ModernBERT falls… 5 r/LocalLLaMA community 6d ago Saluki 27B: "96% of Qwen 3.8’s performance at ~1/7 the size" anyone has feedback about this one?   submitted by   /u/paf1138 [link]   [comments] 26 r/LocalLLaMA community 6d ago ggml-cuda: assign four GDN state columns per warp by SongXiaoXi · Pull Request #30087 · ggml-org/llama.cpp Another day, another Qwen 3.x speedup (prompt processing this time). Soon your Qwen will read your entire project before you can blink! test master t/s PR t/s change pp512 3075.24 3243.60 +5.5% pp4096 3059.87 3221.08 +5.3% tg128 47.62 47.67 +0.1%   submitted by  … 4 r/LocalLLaMA community 6d ago Recommendation for story/world building models? If i ask gemini or grok it always answers with really old models. What's the current gold standard for story telling models ? I'd like to keep it on my 8gb card , but 16gb is available for the right jump in quality. Ideally low refusals, but i also don't want one that goes out… 32 Latent.Space news-outlet 6d ago [AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricing yay small models 35 Hacker News — AI on Front Page community 6d ago I think I found a planet nobody knew existed. I used Claude Code to find it Article URL: https://www.reddit.com/r/ClaudeAI/s/mbe5IY2LF9 Comments URL: https://news.ycombinator.com/item?id=50002665 Points: 227 # Comments: 111 10 r/LocalLLaMA community 6d ago Can any open-weight models handle a decomp/recomp project yet? Opus5.5, Sol6.1, Fable, and Astra have all proven they can and the scene has exploded this past week. Part of that is from the tools and feedback loops maturing though. Are any open weight models (at all, so including K3, GLM5.3, Qwen3.8-Max, and Mimo-2.6) able to do this? Can… 20 arXiv — NLP / Computation & Language research 6d ago FinVector-Market-4B: A Controlled Study of LoRA Adaptation for Structured Financial Tasks arXiv:2610.08882v1 Announce Type: cross Abstract: FinVector-Market-4B adapts Qwen/Qwen3.5-4B with rank-16 LoRA on a 22,000-example corpus for structured financial tasks. We evaluate the base and adapted models on the same 600-example benchmark under implicit and explicit… 8 arXiv — Machine Learning research 6d ago Removing Information Content Does Not Certify Tamper Resistance in Open-Weight Models arXiv:2610.09004v1 Announce Type: new Abstract: Does removing harmful information make open-weight models resistant to fine-tuning attacks? We show that mutual information at release alone cannot universally certify slow recovery. Function-preserving reparameterizations leave… 8 arXiv — Machine Learning research 6d ago Learning Cross-Model Activation Alignments with Explicit Many-to-Many Layer Maps arXiv:2610.09058v1 Announce Type: new Abstract: LLMs are released at a rapid pace, raising a natural question: how do two independently trained models relate, both in which layers correspond and in how features transform between them? We study this by learning an activation… 19 arXiv — NLP / Computation & Language research 6d ago When Forgetting Looks Like Improvement: Metric Masking in Streaming Diarizer Adaptation and the Price of Rehearsal arXiv:2610.08828v1 Announce Type: new Abstract: Small-data adaptation can improve speech detection while degrading speaker attribution. We study this discrepancy in a released streaming diarizer adapted on 7.5 h of two-party conversation and evaluated across six corpora.… 26 Page 4 of 10 · 500 articles ← Newer Older →