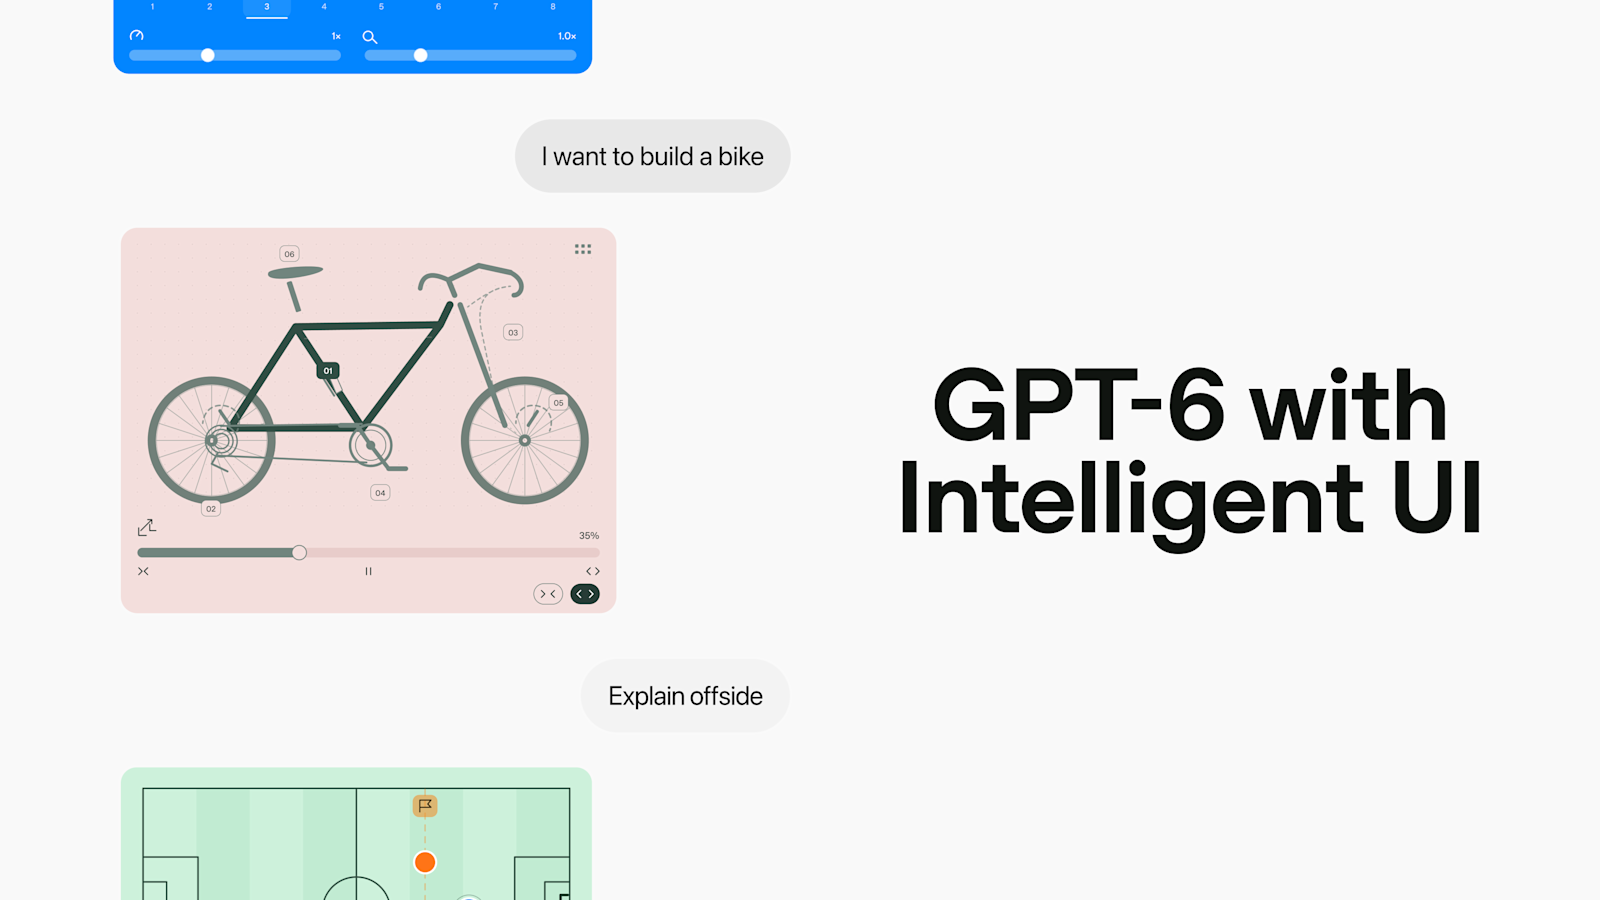
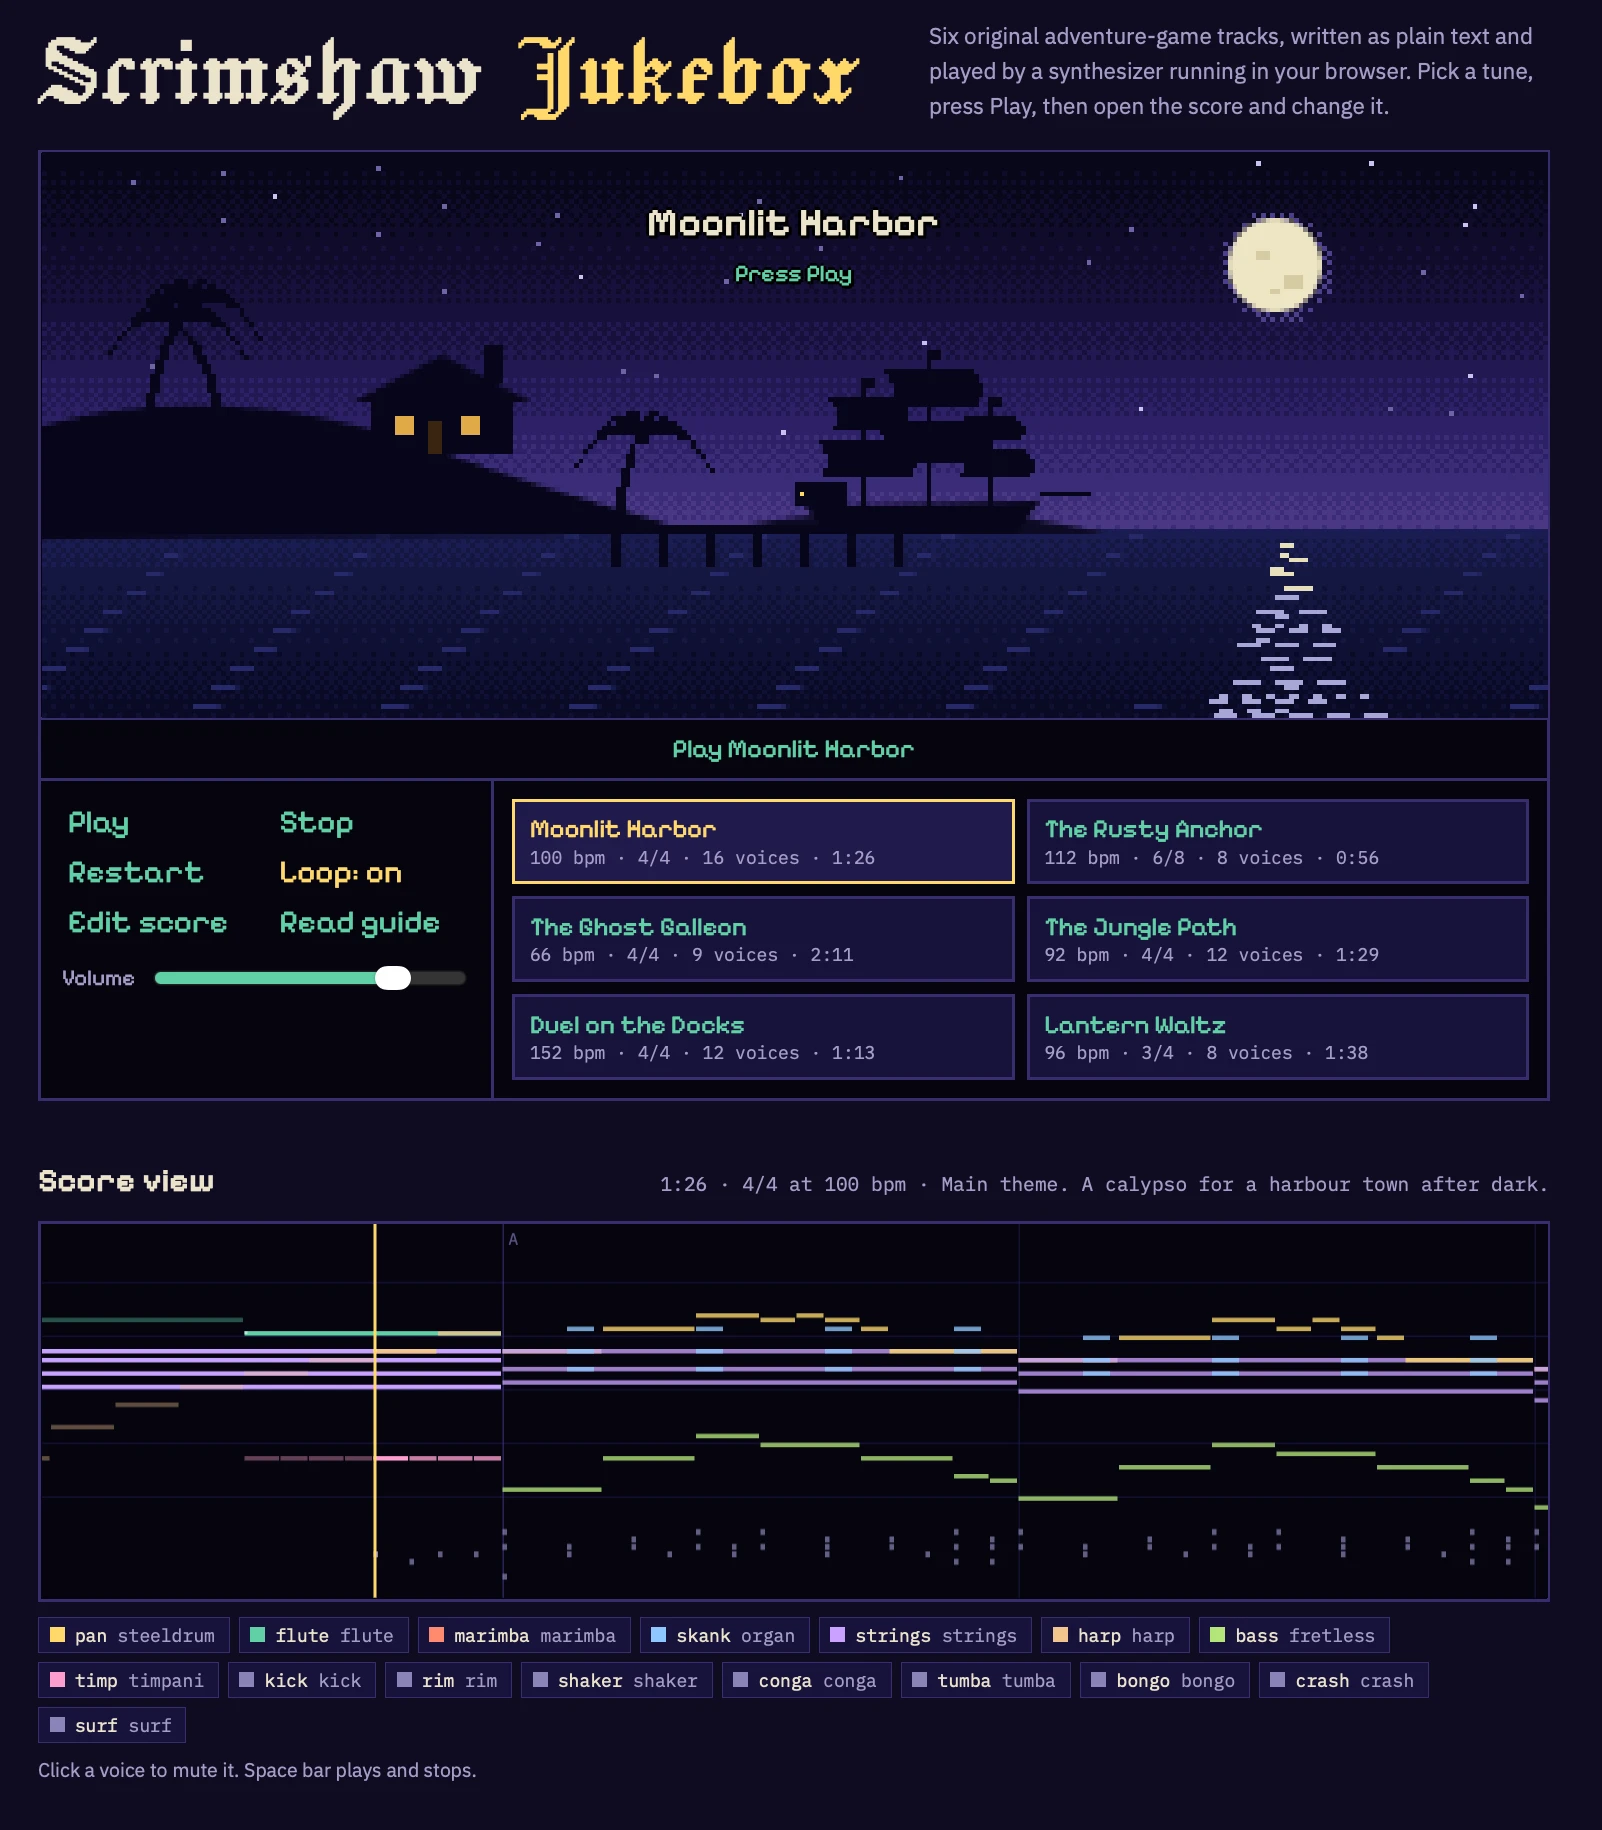
News / #model-release Tag Model releases 500 articles archived under #model-release · RSS Sign in to follow Vercel — AI dev-tools 7d ago Glyph Cluster is now available in stealth for free on AI Gateway Glyph Cluster is now available on AI Gateway as a stealth model for teams on Pro and Enterprise plans with purchased AI Gateway credits. It is free to use during the stealth period. Glyph Cluster is a reasoning model for coding and long-context analysis, and handles multi-step… 23 OpenAI official-blog 7d ago GPT-6 and Intelligent UI for everyone GPT‑6 is rolling out globally in ChatGPT with Intelligent UI, delivering faster responses with visuals and interactive experiences you can explore and use directly. 8 Vercel — AI dev-tools 7d ago OpenAI Decisions API now available on AI Gateway OpenAI's Decisions API is now available on AI Gateway through an OpenAI-compatible /v1/decisions endpoint. Use it with GPT-6 Luna Decisions or any other decision model on AI Gateway. Decision models answer typed questions about a shared input and return probabilities, choices,… 9 Vercel — AI dev-tools 7d ago Claude Haiku 5.5 now available on AI Gateway Claude Haiku 5.5 from Anthropic is now available on AI Gateway . It is built for high-volume, cost-sensitive tasks such as summaries, context compaction, database queries, and classification, and works as a subagent alongside larger Claude models on coding work. It is also the… 30 r/LocalLLaMA community 7d ago MiMo V2.6 Pro almost matched GPT-6 Astra at figuring out what a user actually wants Introducing InferBench: A benchmark testing how well frontier LLMs infer a user's priorities from their instructions. We tested 12 LLMs across 20 scenarios with 2.8k conversations to see which models understand the user's goals. Each conversation has a simulated user with a… 10 r/LocalLLaMA community 8d ago I have about $4000, what's the best setup to get? Ideally I'd like to be able to run Qwen 3.8-Flash-Next with decent performance. I was thinking of just buying 2x Radeon AI R9700 (64GB VRAM), or maybe a DGX Spark but that was before the price hike. My brother suggested just getting a Strix Halo box with 128GB unified. I did see… 19 r/LocalLLaMA community 8d ago Qwen3.8-27B with just 12GB VRAM + 8GB RAM - ~18 tok/sec I got Qwen3.8-27B running at ~18 tok/sec decode & ~500-600 tok/sec prefill (at 64k context) on just 12GB VRAM + 8GB RAM, using ISTA-DASLab Qwen3.8-27B-GSQ-RCO IQ3_S quant (~11GB). This recipe also works with 0bserverx’ Qwen3.8-27B-Heretic-GSQ-RCO IQ3_S quant, achieving similar… 29 Simon Willison community 8d ago llm-openai-decisions 0.1a0 Release: llm-openai-decisions 0.1a0 OpenAI released their new Jev-style Decisions API , as previously announced at last week's DevDay. Since I already have an llm-typesafe plugin for talking to Jev, I had GPT-6 Astra read the new OpenAI API documentation and build an… 8 r/LocalLLaMA community 8d ago Europe rejoins the fight with Chonky! Mistral Large 4 Released, Open weights end of month, who’s ready? 1 trillion parameters, 49B active, definitely chonky! If you don’t love the model you gotta at least love the humor in the name - Le Chonk   submitted by   /u/chemist_slime [link]   [comments] 13 TechCrunch — AI news-outlet 8d ago Ex-Ramp engineers raise $20M for platform Melius after scrapping their first product The startup crossed over $1 million in anualized revenue within two months of its post-pivot launch. 25 Simon Willison community 8d ago llm-mistral 0.16 Release: llm-mistral 0.16 Adds support for reasoning models, such as the newly released Mistral Large 4 . Tags: llm , mistral , llm-reasoning 14 llama.cpp releases dev-tools 8d ago b11457 cuda : add BF16 support for XIELU ( #29955 ) The XIELU CUDA kernel template is already generic over the element type; only the F32/F16 type assertion and the else-if dispatch were missing. Add the nv_bfloat16 branch to the launcher, and drop the temporary supports_op gate in… 10 TechCrunch — AI news-outlet 8d ago How AI decision models could change content moderation On Tuesday, Musubi announced a lightweight decision model made for real-time moderation called PolicyLM-1.7B, released with open weights. 13 Simon Willison community 8d ago Introducing Mistral Large 4: Le chonk Introducing Mistral Large 4: Le chonk Mistral are back in the game. Today they're releasing a preview of Mistral Large 4, a 1 trillion parameter, 49 billion active parameter model trained on their own cluster of 3,800 NVIDIA Grace Blackwell GPUs. The preview is available via… 13 r/LocalLLaMA community 8d ago GPT-6.1 Sol looped "leak" hints at nested models serving architecture Hello llamas. I am posting this because I believe that, despite it being closed source models, the discussion will bring value to the local AI community. As many of you probably heard, GPT-6 Astra is speculated to be a looped transformer architecture that outputs a token after… 31 r/MachineLearning community 8d ago AFP-GIC: Controllable Generative Image Compression [R] Hi ML Community, I am excited to share our latest framework, AFP-GIC, officially published in IEEE Access (2026). We have released the deployment codebase and hosted an interactive visual playground. GitHub Repository: https://github.com/yifeipet/AFP_GIC Hugging Face Interactive… 24 The Information — AI news-outlet 8d ago Anthropic Expands Cyberdefenders’ Access to Top Models Anthropic said it is expanding and restructuring its cybersecurity access programs to enable more cyberdefenders to use its most advanced Claude models to secure their systems against potential AI attacks. Under the changes, announced Tuesday, all members of Anthropic’s Cyber… 36 TechCrunch — AI news-outlet 8d ago Hark releases an AI personal assistant with a focus on privacy The AI lab's personal assistant is an operating system from the future designed to compete with Muse, Dots, and Instinct. 13 Simon Willison community 8d ago Mistral Large 4 My comment on Mistral Large 4 — Hacker News. wren6991 : The benchmark is saturated. Frontier models are tested with an armadillo in fishnet tights jaywalking on Mars. OK well I couldn't resist this one: llm -m claude-opus-5.5 'Generate an SVG of an armadillo in fishnet… 16 Hacker News — AI on Front Page community 8d ago Claude Code’s suggested message feature: I think the real customer is the model Article URL: https://www.zohaib.cc/blog/smartest-claude-code-feature Comments URL: https://news.ycombinator.com/item?id=49981905 Points: 222 # Comments: 125 8 r/LocalLLaMA community 8d ago Aplomb 1: open-weights 5.3B decision model, 1M context, text/image/video/audio in one request, #1 among 4B models on the Decision Index We released Aplomb 1 today, a 5.3B decision model with open weights. It reads up to 1M tokens of text, JSON, images, video and audio in a single request, and on our API it makes a decision on a 1M-token document in about 3 seconds, at $0.02 per 1M input tokens with free output… 36 r/LocalLLaMA community 8d ago I trained a model to be wrong 98% of the time and 96% sure about it. It took three tries. Meet Bev. She is a decision model (the Jev / Nimble kind: you give her a situation and a question, she gives a probability for each answer), fine-tuned on Qwen3.5-9B to pick the worst answer on purpose. Try her in your browser: https://huggingface.co/spaces/richardyoung/ask-bev… 11 Simon Willison community 8d ago datasette-atom 0.11a0 Release: datasette-atom 0.11a0 A minor fix for compatibility with the latest Datasette alphas. This meant we could upgrade the datasette.io site to Datasette 1.0a41. Tags: atom , datasette 4 The Information — AI news-outlet 8d ago Can Microsoft Help Customers Cut Back on Claude? There was good news and bad news for Anthropic in our story yesterday that showed how two of its mega-customers, Microsoft and Meta, were cutting their staffs’ Claude bills. Among the bad news was that Microsoft had reduced its spending on Claude by more than 33% from its peak… 25 r/LocalLLaMA community 8d ago Introducing EmbeddingGemma 2: A best-in-class open model for natively multimodal embeddings | Google https://huggingface.co/google/embeddinggemma-2 EmbeddingGemma 2 is an open multimodal embedding model built by Google DeepMind which maps text (incl. code), images, video, and audio inputs—and combinations thereof—into a single, unified 768-dimensional vector space. The model… 9 TechCrunch — AI news-outlet 8d ago Mirror Particle is building a ‘world model’ of human behavior Mirror Particle will launch at TechCrunch Disrupt's Startup Battlefield 200 with a world model built from scratch to predict human behavior, arguing that LLM role-play falls short for market research and brand strategy. 17 NVIDIA Developer Blog official-blog 8d ago AICR v1.0: Open, stable, and verifiable GPU cluster configuration GPU-accelerated Kubernetes clusters depend on compatible versions across dozens of components, each on its own release cycle: host kernels, GPU drivers,... 17 TechCrunch — AI news-outlet 8d ago Anthropic is giving startups a free year of Claude Team and $1,000 in credits "We created this program because we believe the benefits of AI will reach most people through the companies that build on top of models, rather than through the models alone." 23 Ollama releases dev-tools 8d ago v0.40.0 What's Changed Models run on MLX on Apple Silicon by default In this release, on Apple Silicon devices, model architectures supported by the MLX runtime will automatically run on MLX. ollama pull qwen3.8 ollama run qwen3.8 Additional models include gemma4 , qwen3.6 and qwen3.5… 9 LangChain releases dev-tools 8d ago langchain-core==1.6.7 Changes since langchain-core==1.6.6 release(core): 1.6.7 ( #41087 ) fix(core): include openai redacted_content in v1 output for bedrock converse ( #41086 ) fix(core): python 3.14 hardening around inspect.signature ( #41059 ) chore(deps): bump notebook from 7.5.7 to 7.6.3 in… 6 r/LocalLLaMA community 8d ago Woman used claude as her diary - and got reported to the police for contents of her diary   submitted by   /u/Timely_Impression_92 [link]   [comments] 4 Simon Willison community 8d ago Scrimshaw Jukebox Tool: Scrimshaw Jukebox I wanted to see if Claude Opus 5.5 could compose music, so I tried this : I want you to write some computer game music for me. First design simple text based format for the music and build an artifact that can play it out loud - include some example… 18 r/LocalLLaMA community 8d ago Qwen3.8-Flash-Next on Strata Hey! 👋 I have released an official support for Strix Halo machines on Strata for Qwen3.8-Flash-Next. Currently numbers are the best on long context decode and ppts using typical Unsloth’s Q4 and GSQ-RCO model weights. Can go up to 1M context length without big speed loss.… 32 TechCrunch — AI news-outlet 8d ago Mistral’s new 1T model aims to leapfrog closed and open rivals French AI lab Mistral AI has released Mistral Large 4, a new large multimodal model aiming to leapfrog both American and Chinese rivals. 6 r/LocalLLaMA community 8d ago Q (@qtnx_) on X - Mistral Large 4 is still doing RL runs, keep seeing improvements (vs preview version). Release at the end of the month   submitted by   /u/DerpSenpai [link]   [comments] 18 r/LocalLLaMA community 8d ago Mistral releasing new open weights model "Le Chonk" LeChonk-1T-A49B Weights to be released by the end of the month. This probably means the fat kitten is dead. Also: gotta love the release movie.   submitted by   /u/wapswaps [link]   [comments] 32 r/LocalLLaMA community 8d ago Introducing Mistral Large 4 (Preview)   submitted by   /u/Few_Painter_5588 [link]   [comments] 38 llama.cpp releases dev-tools 8d ago b11445: vulkan : check for null vkEnumerateInstanceVersion (#29872) A 1.0 loader (e.g. Android 8.1) has no vkEnumerateInstanceVersion, so backend init called a null pointer. Treat it like any loader under 1.2. Fixes #29871 . Assisted-by: Claude Opus 5.5 12 Hacker News — AI on Front Page community 8d ago Mistral Large 4: "Le Chonk" Article URL: https://mistral.ai/news/mistral-large-4/ Comments URL: https://news.ycombinator.com/item?id=49978116 Points: 255 # Comments: 29 13 Hacker News — AI on Front Page community 8d ago Mistral Large 4 Article URL: https://docs.mistral.ai/models/mistral-large-4-0 Comments URL: https://news.ycombinator.com/item?id=49977979 Points: 279 # Comments: 109 23 Hacker News — AI on Front Page community 8d ago Mistral Large 4 https://docs.mistral.ai/models/mistral-large-4-0 Comments URL: https://news.ycombinator.com/item?id=49977979 Points: 991 # Comments: 662 19 r/LocalLLaMA community 8d ago Mistral Large 4 benchmarks Just dropped.   submitted by   /u/Informal-Trouble2183 [link]   [comments] 24 r/LocalLLaMA community 8d ago Meet Mistral Large 4, aka Le Chonk.   submitted by   /u/cpldcpu [link]   [comments] 20 r/LocalLLaMA community 8d ago Qwen 4 apparently coming out at the end of October Hey All, I spoke to a 0-day partner of Alibaba today and he casually mentioned (didnt know if he was allowed to) that Qwen 4 is apparently planned for the end of October. To me, this is way faster than expected as there was quite a gap between 3.6 and 3.8. I tried to get more… 22 ElevenLabs official-blog 8d ago Introducing ElevenAgents Architect Find the improvements your team would otherwise miss. Bring a goal, get back proposals already drafted and validated in simulated conversations. 16 Hacker News — AI on Front Page community 8d ago Release of Polars 2.0 Article URL: https://pola.rs/posts/release-polars-2/ Comments URL: https://news.ycombinator.com/item?id=49977177 Points: 293 # Comments: 52 19 r/LocalLLaMA community 8d ago Microsoft confirms OpenAI has been using Looped Transformers in the GPT-6 series Microsoft confirms on publicly accessible web page that OpenAI has been using Looped Transformers in the GPT-6 series, proving The Information's reporting was correct all along. GPT-6.1 Sol uses 2 inference passes, with a passing mention of "instead of three". For those confused… 35 r/LocalLLaMA community 8d ago Story time: Qwen3.8-Flash-Next on my Strix Halo laptop vs Claude Opus 5.5 on the same feature For the last few weeks most of my coding has been done locally with Qwen3.8-Flash-Next, so I gave it and Opus 5.5 the same high complexity feature to build on LlamaStash (a complex and large Rust project) and compared the results. Setup : ASUS ROG Flow Z13 (Strix Halo, 128GB),… 21 r/LocalLLaMA community 8d ago Tencent releases Octop, a self-hosted AI assistant Octop is an open-source, self-hosted AI assistant. Through its multi-agent architecture, it builds an intelligent environment that is both independent and collaborative for teams, families, and individuals. Best of all, it runs entirely on your machine, the fully self-hosted… 5 r/LocalLLaMA community 8d ago NInfer6000 - Qwen 3.8 Flash Next @ 400 tg/s & 13K pp/s I've tinkered some more with my fork of NInfer for the Qwen 3.8 Flash Next model on RTX6000, and I've just hit 400tg/s under ideal conditions with it, so I thought it was worth a share. This is NVFP4 MoE's and the rest is either 16-bit or 8-bit, so it uses full 96GB VRAM and… 24 Page 6 of 10 · 500 articles ← Newer Older →