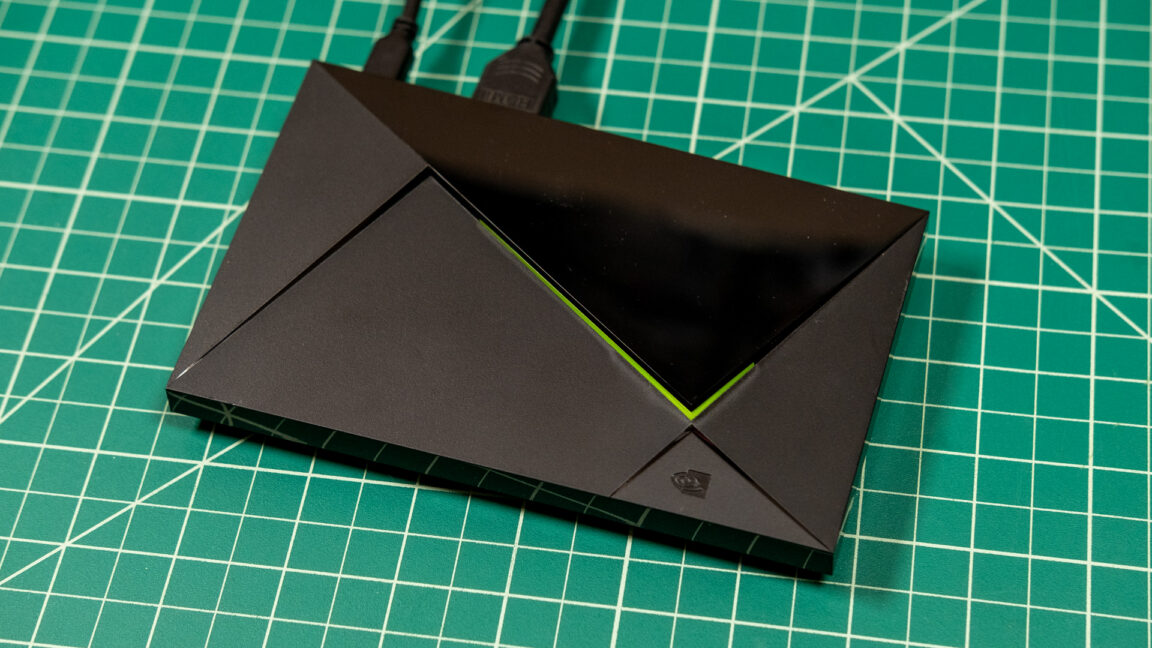
News / #model-release Tag Model releases 500 articles archived under #model-release · RSS Sign in to follow r/LocalLLaMA community 12d ago Strata on a power limited 5090 and 96GB of DDR5-6400 is cranking out 150-200 tok/s decode and 5-6k prefill! Qwen3.8-Flash-Next at IQ3_S, CTX at 128k tokens (8-bit).   submitted by   /u/z0_o6 [link]   [comments] 10 Ars Technica — AI news-outlet 12d ago The 7-year-old Nvidia Shield TV is now $100 more expensive thanks to AI Initially launched in 2019, the Nvidia Shield TV Pro now retails for $299.99. 18 Latent.Space news-outlet 12d ago Inside-Out AI: Rebuilding Airbnb Behind the Scenes and Across the Guest Experience After leading Meta’s Llama models, Ahmad Al-Dahle is now transforming Airbnb with AI — from how its teams develop products to how it serves guests. 17 llama.cpp releases dev-tools 12d ago b11346 qwen4exp: fix tests ( #29819 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/52169567 macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI enabled) DISABLED macOS Intel (x64) iOS XCFramework Linux: Ubuntu x64… 32 r/LocalLLaMA community 12d ago Tuned/abliterated Qwen3.8-27b into a 24gb card 262k guff using the newest unreleased version of LexiPanel. It's fast with reliable draft acceptance. Made for 7900xtx but should work on whatever 24gb card with this setup and headless. Doesn't get dumber while coding like most of… https://huggingface.co/Wa1k3r/Qwen3.8-27b-CODER-4q_xs-24GB-262k-Optimalcardfit Qwen3.8-27B CODER — IQ4_XS imatrix · 24 GB card fit · ~262k context · MTP draft Quantized, Abliterated, and fitted by LexiPanel. Its Fit planner chose the tensor mix to fill one 24 GB GPU at about… 30 r/LocalLLaMA community 12d ago Two 96 GB Ascend cards crun Qwen3.8-flash-next hardware notes, vLLM work, benchmarks, and what is next I have been building a somewhat unusual local inference machine around two Huawei Atlas 300I Duo cards. They are relatively inexpensive, passive, dual-accelerator PCIe cards with 96 GB of device memory apiece. They are also absolutely not drop-in CUDA replacements. When I first… 36 r/LocalLLaMA community 12d ago Inference Engineering for Dummies Hi all! I am a former SWE who has recently transitioned into inference engineering. I launched a side hustle a few months back and I've just taken it full time due to excessive demand. Its been such an opportunity because the people optimizing runtime are far fewer than the… 20 r/LocalLLaMA community 12d ago I made my own cybersecurity benchmark and ran Qwen3.8 27B, here's how a local model actually does at hacking Hey local AI community, I've been working on this for a while and finally feel ok sharing it. It's a cyber benchmark where the model gets a shell in an isolated docker box and has to find the exact flag. Pwn, web, crypto, rev, forensics, a few real CVEs and some multi-stage… 4 r/LocalLLaMA community 12d ago Qwen3.8-Flash-Next (5.05bpw + ngram at bf16) exl3 on one r9700: 863 t/s prefill and 35 t/s decode at 230k context (256k max), is that ok or am i missing something? Hi, i got QFN running on my single r9700 but im not sure if i did everything right to get the best quality and speed out of this setup. Dont want to annoy anybody, maybe someone with the same card can tell me if this looks normal. What i run: - model: Qwen3.8-Flash-Next from… 31 The Information — AI news-outlet 12d ago Microsoft Debuts Voice AI to Compete with ElevenLabs Microsoft on Thursday launched speech-generating AI that the company says is both cheaper and more accurate than competing models from the likes of ElevenLabs, SpaceXAI and Google. Microsoft aims to produce voice models to power features such as transcribing conference calls in… 11 r/LocalLLaMA community 12d ago Does anyone know if any new releases from Mistral are planned? It’s been a long time since the last models came out. I notice they are selling GLM on the site, and I wonder if they are developing something, given the long silence.   submitted by   /u/LegacyRemaster [link]   [comments] 4 r/LocalLLaMA community 12d ago best <40B alternatives to Qwen/Deepseek for (1) Coding (2) Long document QA test Due to some reasons, Qwen/Deepseek Chinese models are NOT allowed in the my workplace. So, what local models, do you think, is the best alternatives to Qwen/Deepseek for (1) Coding (2) Long document QA test (like giving a long medical history of 120k tokens and ask a question… 23 r/LocalLLaMA community 12d ago Detecting hallucinations in local models without eating VRAM: What we learned testing 1.5B to 120B models Hey everyone, If you run local models via Ollama in production or personal projects, you've probably run into the hallucination problem: how do you know when a model is hallucinating without burning extra VRAM or waiting 5 seconds for a heavy judge model? The standard academic… 8 llama.cpp releases dev-tools 12d ago b11339 llama : clamp kpool re-pool bound to existing pools ( #29805 ) tests : simplify function signature llama : clamp kpool re-pool bound to existing pools The n_tokens/kpool + n_seqs_unq bound on n_new_g overshoots when a batch fills the whole cache: n_ctx tokens complete exactly… 22 arXiv — Machine Learning research 12d ago Grokking through the Lens of Minimum-Norm Interpolation arXiv:2609.38453v1 Announce Type: new Abstract: Grokking shows that fitting the training data and learning the underlying signal can occur at very different stages. However, existing theories offer limited quantitative insight into how this delayed generalization depends on… 14 Hacker News — AI on Front Page community 12d ago DeepSeek Harness Desktop for macOS and Windows Article URL: https://www.deepseek.com/en/harness/ Comments URL: https://news.ycombinator.com/item?id=49929489 Points: 214 # Comments: 106 20 llama.cpp releases dev-tools 12d ago b11335 cuda : route sm70 to the Turing MMVQ nwarps table ( #29753 ) cuda : route sm70 to the Turing MMVQ nwarps table Volta (sm_70) has no MMVQ parameter table of its own and falls through to GENERIC, which launches K-quant batch-1 decode (ncols_dst == 1) at nwarps=4. sm_70 shares… 5 ThursdAI news-outlet 12d ago ThursdAI - Oct 1 - OpenAI joins the assistant race, CoreWeave drops serverless GPUs & more Listen now (117 mins) | From CoreWeave: GPT-6.1 Sol is near-Astra for a fifth of the price, Sonnet 5.5 beats Opus on Terminal-Bench, Gemini 4 Argon tops the charts, and we went LIVE from Fully Connected. 38 r/LocalLLaMA community 12d ago Update on the “Monstrosity”. 6 BC-250 board cluster This is 6 bc-250 ex mining boards with 5 in the asrock 4u12g case they came in. After a lot of testing my current preferred setup is 4 boards running Qwen Next Flash IQ2_XS at 100k context with around 28 tok/s for short generation and 24 tok/s at 50k with around 115 ppt. The… 15 llama.cpp releases dev-tools 12d ago b11334 metal : release temporary private transfer buffers ( #29777 ) metal : release temporary private transfer buffers Assisted-by: OpenAI Codex metal : fix order and formatting Co-authored-by: Niklas Wenzel dev@nikwen.de Website: https://llama.app Attestations:… 19 r/LocalLLaMA community 12d ago Introducing ModelHarbor, a self-hosted model library   submitted by   /u/toks-love [link]   [comments] 5 llama.cpp releases dev-tools 13d ago b11332 llama : fix invalid assert in recurrent memory ( #29799 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/52014664 macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI enabled) DISABLED macOS Intel (x64) iOS… 22 r/LocalLLaMA community 13d ago Perplexity Decider 27B: Open weights decision model fine tune of Qwen3.8 27B   submitted by   /u/rm-rf-rm [link]   [comments] 37 Hacker News — AI on Front Page community 13d ago Show HN: Giving Opus 5.5 a simulated paint canvas Article URL: https://stillwet.art/ Comments URL: https://news.ycombinator.com/item?id=49928566 Points: 203 # Comments: 64 28 llama.cpp releases dev-tools 13d ago b11330 Qwen4Exp: add MTP ( #29761 ) Qwen4Exp: add MTP remove has_state member, check via ctx_bufs being non-empty consistent naming + less verbose comments cont : clean-up recurrent memory cont : clean-up comments Co-authored-by: Georgi Gerganov ggerganov@gmail.com Website:… 28 r/LocalLLaMA community 13d ago Pi 1.0 released - MCP support now included by default   submitted by   /u/psychohistorian8 [link]   [comments] 14 OpenAI official-blog 13d ago Chatham scales its capital markets expertise with OpenAI Chatham Financial uses Codex and GPT-5.6 to build technology and redesign workflows, cutting trade validation from 30 minutes to under 4. 28 r/LocalLLaMA community 13d ago Gufo performance .... 70tps Qwen 3.8 27b but you need to read the fine print. So everyone has been yelling about how I should be using Gufo instead of halogen because it's open source and it's "just as good or better". Checking in on their GitHub (GitHub.com/gufo-org/gufo) got me immediately .. "Qwen 27B Q4: 70.56 tok/s single user, 123 tok/s with 8… 19 TechCrunch — AI news-outlet 13d ago Musk’s AI chatbot Grok reportedly encouraged Trump to capture Venezuela’s president President Trump reportedly asked for Grok's opinion before invading Venezuela and capturing Nicolás Maduro. 36 r/LocalLLaMA community 13d ago What local AI model is good for game decomps/recomps? Hello guys. Recently, there has been a boom in game decomps and recomps thanks to AI. If you look at the r/decomps and r/recomps subreddits, you can see it. They mostly seem to be using Claude or Codex.I wonder if it would be possible to do something similar with a local AI… 28 r/LocalLLaMA community 13d ago Running 95.5 GiB Qwen3.8-Flash-Next at 41–52 tok/s on a 64GB Mac (1.76x faster than llama.cpp): Slipstream release, 130k context scaling, + Swift variant I've been working on getting the 95.5 GiB Qwen3.8-Flash-Next model to run fast on a single 64GB Mac. In my earlier posts, I shared a custom expert-streaming fork of llama.cpp . It worked, but decode capped out around ~23–27 tok/s and slowed down as context grew. Today I'm… 5 r/LocalLLaMA community 13d ago AMA about K2 Horizon, Meet our team from IFM Hi r/LocalLLaMA! We’re researchers at the Institute of Foundation Models (IFM), an AI research lab dedicated to open and independent development of frontier-class foundation models. We recently released K2 Horizon a connected fleet of six fully open models with size ranging from… 6 llama.cpp releases dev-tools 13d ago b11324 llama-mmap : avoid a second full-size copy of each tensor with direct-io ( #29749 ) Assisted-by: Claude Co-authored-by: Pranesh Gonegandla pgonegandla@nvidia.com Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/51929570 macOS/iOS: macOS… 5 TechCrunch — AI news-outlet 13d ago Google thinks SpaceX’s Starship has to launch 1,600 times before space data centers get off the ground Google launched its first advanced chip into orbit to pave the way for space data centers. 30 r/LocalLLaMA community 13d ago Now which lab is behind fledge alpha? New free/trial model dropped on OC. Details are yet to be provided. Could this be deepseek v4.1 pro?   submitted by   /u/Gohab2001 [link]   [comments] 16 r/LocalLLaMA community 13d ago What's the best setup for Qwen3.8 27b for a 16 gig VRAM? Hello guys! I have been experimenting with qwen 3.8 for a long time and I hadn't been able to get reasonable speed. I am on a 5060Ti 16 GB, and although this gpu can game, I am aware that AI demands more than 16 GB. I am on a Fedora 44, AMD Ryzen 9600x and 16 GB system ram (16… 36 TechCrunch — AI news-outlet 13d ago Opus 5.5 loves to tell you ‘this matters’ (and other AI writing tells) Opus 5.5’s biggest tell is the word “dependable,” which pops up 23 times more often than in human samples. 13 Simon Willison community 13d ago pwasm 0.2a0 Release: pwasm 0.2a0 pwasm is one of my folly projects - an entirely vibe-coded pure Python WebAssembly engine that I built in January during my first bout of AI mania . I hadn't touched it since January, so I decided to let Claude Opus 5.5 loose on it and see if it could make… 26 TechCrunch — AI news-outlet 13d ago Amazon releases its own Jev clone as decision models flood the web Amazon Web Services' Strand Labs has released the latest Jevalike decision model, Strands Decider 2B. 31 Hugging Face official-blog 13d ago Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs Back to Articles a]:hidden"> Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs Enterprise Article Published October 1, 2026 Upvote 3 Kyle Wiggers Ai2Comms allenai :last-child]:mb-0"> 📄 Tech Report | 💻 Code | 🧩 Interactive demo Today we’re… 7 Don't Worry About the Vase community 13d ago AI #188: Gemini Dot Argon Is Google back? 17 r/LocalLLaMA community 13d ago Unsloth, Swift1.5, Peculiar-Ragdoll, ThinkingCap - Qwen3.8-27B In a previous post I shared comparison between Swift1.5 and peculiar-ragdoll's checkpoints. Added the original unsloth Q4_K_XL and ThinkingCap Q4_K_M (they don't offer L or XL) to the comparison. Here are the results over a 69 set of eval questions. All tests are now run at same… 13 r/LocalLLaMA community 13d ago Pi extension: Skip reasoning with local Qwen 27B and proceed to answer right now pi-llama-skip-reasoning is an extension for the Pi.dev harness that forces a local llama.cpp model to stop reasoning and answer / act immediately. When you are deep into the ctx session and ask 27B a simple question about a fact or need a direct action, the model may still feel… 32 r/LocalLLaMA community 13d ago Jeff-Qwen3.5-0.8B v1.2 + 9 LoRA adapters: put it in front of Qwen3.8-27B for 38× faster decisions and +8.7 points accuracy, for under 2 GB extra memory A few days ago I released Jeff-Qwen3.5-0.8B, a small "System 1" model that picks between options you define and returns a calibrated probability for each, in one forward pass. Speed was great on my M4 Max and RTX PRO 6000, but as a general zero-shot classifier it trailed the big… 36 r/LocalLLaMA community 13d ago $5400 eBay 8x V100 server cranks on flash-next Had opus 5.5 do the bring up.. super solid results. Using only 4 GPU results in KV of like 120k with image on. 27B TP=4 results in >200 tok/s with dflash, prefill around 2.5-3.5k. Both these are running the nvfp4 Nvidia checkpoints. Found a magic repo that unpacks into fp16 on… 22 TechCrunch — AI news-outlet 13d ago Hearing tech startup Legato launches its AI hearing glasses The glasses stem from the startup’s goal of making hearing care more accessible by addressing the cost, comfort, and stigma associated with traditional hearing aids. 26 r/LocalLLaMA community 13d ago Why am I like this? (Full Chat and Image generation on a 286 Tandy 1000 TL/3) 40 year tech gap? No problem! The Tandy runs DeskMind, a native DOS program. It talks over WiFi (a PicoMEM 2 card with mTCP) to a small Python server on my PC. That server drives Qwen3.8-27B (NInfer on a 5090) and Krea 2 (ComfyUI on a 4090). The 286 never sees JSON, base64 or a… 28 ElevenLabs official-blog 13d ago ElevenLabs launches in the Netherlands ElevenLabs launches in the Netherlands, opening an Amsterdam office and tripling its local team to bring voice AI to Dutch enterprises. 21 llama.cpp releases dev-tools 13d ago b11320 common : add LLM-jp-4.1 Harmony dialect handler ( #29681 ) LLM-jp-4.1 uses the GPT-OSS format, but its tokenizer decodes a space after every special token and parallel tool calls are separated by <|end|>. The GPT-OSS handler rejects this output, so add a dedicated handler,… 21 r/LocalLLaMA community 13d ago Qwen4Exp: add MTP by am17an · Pull Request #29761 · ggml-org/llama.cpp now you can use MTP with Qwen Flash Next, time to switch from Qwen 3.8 27B? (merged after 17h of development) quants: https://huggingface.co/ggml-org/Qwen3.8-Flash-Next-GGUF link to the previous discussion (I deleted the old post to avoid duplicates):… 14 Page 9 of 10 · 500 articles ← Newer Older →