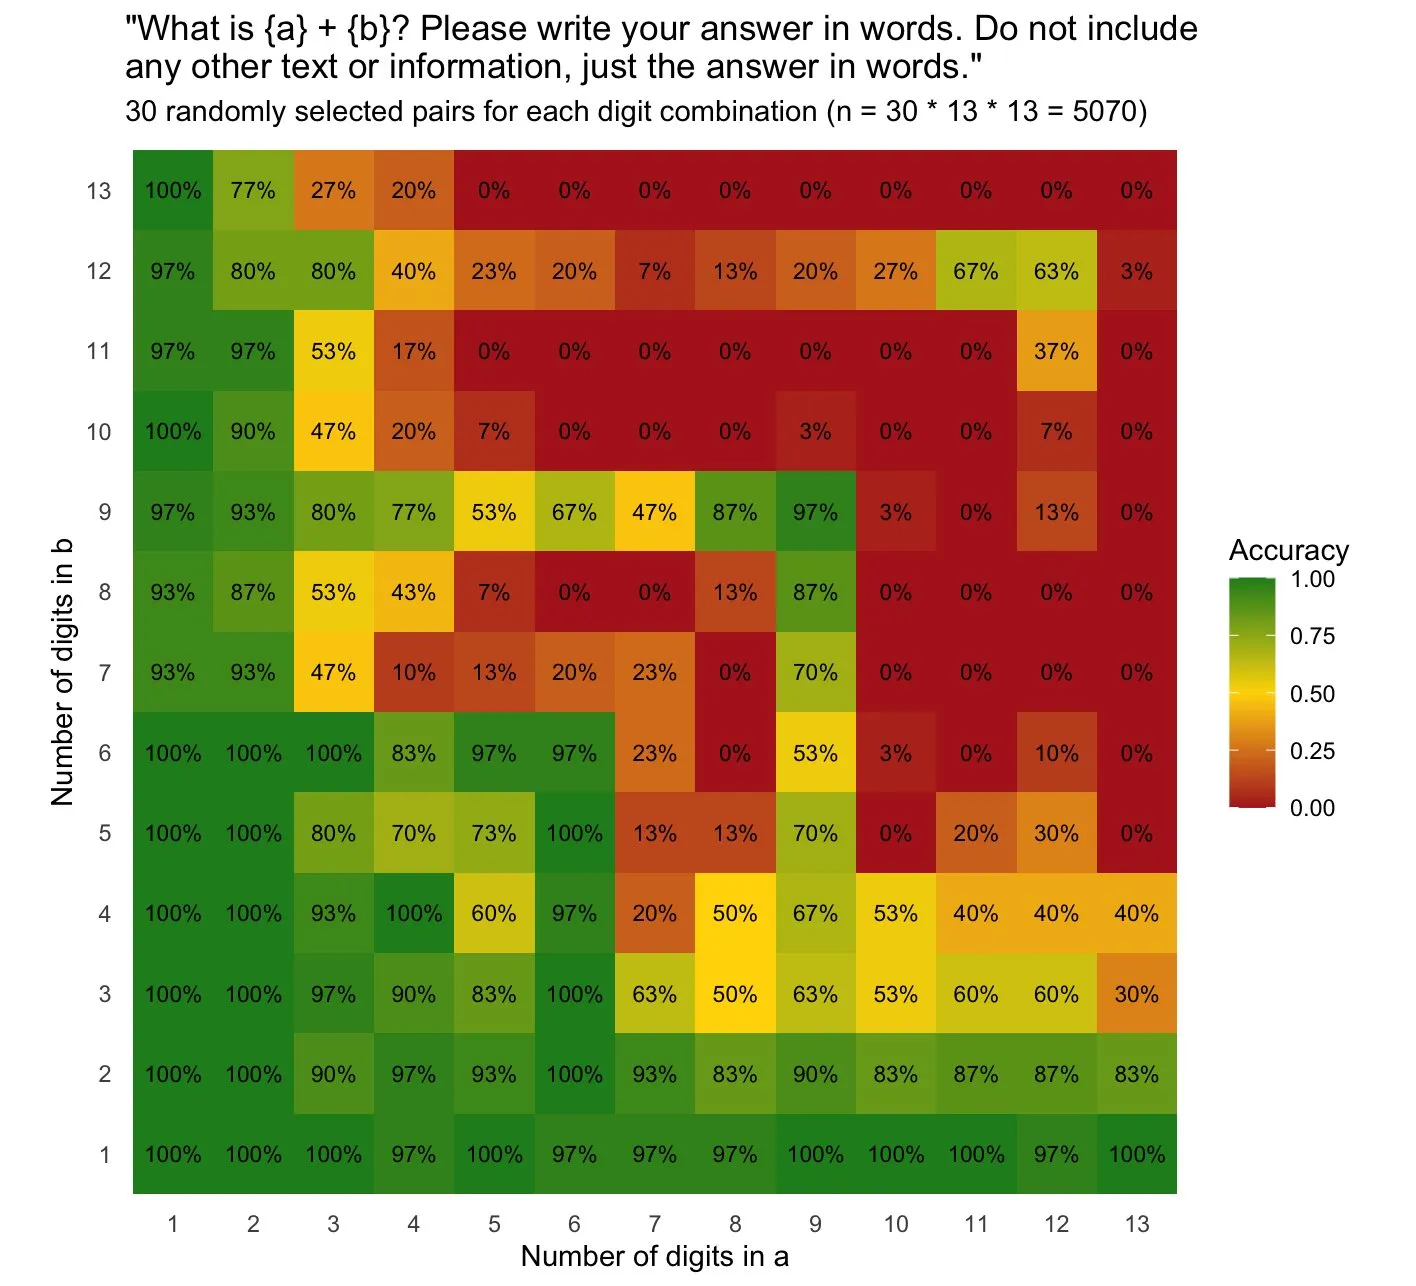
News / #model-release Tag Model releases 500 articles archived under #model-release · RSS Sign in to follow Simon Willison community 10d ago Qwen3.8 27B addition in words Research: Qwen3.8 27B addition in words Colin Frasier posted on Bluesky about an experiment he ran over two years ago using GPT-4o to see how well it could "compute the sum but return the answer in words" across increasingly large numbers. Here's the chart he shared of those… 35 r/LocalLLaMA community 10d ago For dual DGX spark users; GLM 5.3 flash got a 50%+ performance boost For the last few months, I ran DeepSeek v4.0 flash (NVFP4). First 0731 , then visionexp because it was a free improvement. I got around 65 tps decode and almost 2k prefill, and ran 4-5 agents in parallel, totalling around 200 tps cumulative decode. Because of this, I did not… 34 r/LocalLLaMA community 10d ago Fully local little parkour sim I vibed this up this weekend, fully local, with GLM 5.3 Flash running on 2x DGX Sparks. vllm TP2 recipe: https://github.com/tonyd2wild/GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark Prefill: ~1500t/s Decode: ~40t/s @ 100k Using Claude Code as the scaffold with 260k context size. I'm… 31 r/LocalLLaMA community 10d ago Update #4: Post training yandex/AliceAI-80B-A3B [instruct!] from scratch Last update for those following: https://www.reddit.com/r/LocalLLaMA/comments/1wvyc3e/update_3_post_training_yandexaliceai80ba3b/ Project in a sentence: An instruct finetune of ALiceAI-80B-A3B-Base capable of agentic work and conversation. I'm creating a shallow distill of qwen… 7 r/LocalLLaMA community 10d ago poorman inference engine for 16GB GPU and 35B moe Qwen 3.6for coding I forked llama.cpp's server into AgrillaMoE, a dedicated build for Qwen3.6-35B-A3B (~A4B) with Unsloth quants. On a (vant.ai) rented V100 16GB with the 2-bit UD-Q2_K_XL quant it generates at ~57-60 tok/s while running the full MoE-expansion profile — and it speaks both the… 7 r/LocalLLaMA community 10d ago Built a quick, sub-15ms Rust CLI/TUI to pack repos into prompts without burning 40k tokens on lockfiles and junk Whenever I feed codebases into local models (Qwen, DeepSeek R1) or API models, the biggest annoyance is prompt pollution: - Lockfiles (`Cargo.lock`, `package-lock.json`) burning 30,000+ tokens for zero reason. - SVGs, binary files, or build artifacts slipping into the context. -… 32 r/LocalLLaMA community 10d ago Qwen3.5 arch implementation in FPGA fabric for 9B/27B INT4 models on relatively cheap eBay mining hardware I've been wanting to test out LLM inference on FPGAs for a while now, but didn't have a big reason too since there were no frontier class models at 9B-27B scale (3.6 27B was great still but it didn't motivate me enough). When 3.8 was released I was pretty impressed by what it… 34 llama.cpp releases dev-tools 10d ago b11395: ci : add windows arm64 vulkan release (#29954) add windows vulkan arm64 release add link 14 r/LocalLLaMA community 10d ago A Strata fork for IBM AC922 running Qwen3.8-FN UD-Q4_K_XL is doing up to 7,357 tk/s prefill and 113 tk/s decode I forked Strata and worked with Claude code with some heavy changes to it to make it work on an IBM AC922 I have access to. The IBM AC922 is a 2018 era beast with two POWER9 20 core SMT4 CPUs that are connected by NVLink to 4 or 6 NVIDIA Tesla V100 SXM2 GPUs, the CPU-GPU BW… 37 Ollama releases dev-tools 10d ago v0.40.0-rc2 Merge remote-tracking branch 'upstream/main' into release_v0.40.0 25 r/LocalLLaMA community 10d ago How long before we have a local model capable of modeling? I'm using Qwen 3.8 and qwen flash on a 5090. It's miles behind the latest Opus 5.5. Even if it was remotely capable it would be a huge help to me, but for now, with regards to 3D modeling, local models are not close at all.   submitted by   /u/Hot_Masterpiece_3668 [link]… 35 r/LocalLLaMA community 10d ago From 1x3090 to 20 DGX Sparks: my house fuses were the first bottleneck ​ From the first LLaMA 33B I knew I wanted that magic-like intelligence locally, mine, so nobody could take it away when I needed it. I bought a 3090 for my home PC. Then LLaMA 65B appeared and I was dazzled, it looked like it had all the knowledge in the world. I made… 9 r/LocalLLaMA community 10d ago Is there any way to improve creative writing for Local Models (Qwen)? I wanted to know if theres anything that can improve creative writing for our Local Models? I specificly am asking for qwen models as they are way better when it comes to researching and writing html files compared to gemma / muse (which I know are better at creative writing).… 35 Hacker News — AI on Front Page community 10d ago Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s Article URL: https://github.com/Niko1221/Strata Comments URL: https://news.ycombinator.com/item?id=49953495 Points: 277 # Comments: 140 16 r/LocalLLaMA community 10d ago Local text to speech with Breeze is truly incredible Been playing around with local TTS with Breeze combined with STT, and the results are amazing. Using Opus 5.5, I can hear the first sound after 500ms if there is no thinking involved, and with thinking on low mode, can be 1-1.5s. I'm using a BLE remote (the kind that are used… 7 r/LocalLLaMA community 10d ago Can someone explain how JEV is different from a simple embeddings model? How is JEV any different from using an embeddings model? I really will appreciate if someone can explain this to me - because I have yet to see the difference. I'll even give you my JEV server for free! It uses ollama, you install `ollama pull nomic-embed-text:latest`. % python3… 33 r/LocalLLaMA community 10d ago bilibili released Index-Translate,a A Multilingual Translation Model Family based on Qwen3.5 https://github.com/bilibili/Index-Translate Index-Translate is a family of multilingual translation models built on Qwen3.5. The text models cover 150 languages and follow translation instructions such as terminology, formatting, and content-preservation requirements. The family… 30 r/LocalLLaMA community 10d ago Is all the work that's being put into Qwen3.8 Flash Next going to set us up for a very quick uplift to Qwen4? Given the commentary on the Q3.8FN release page here https://qwen.ai/blog?id=qwen3.8-flash-next I assume/hope that all the work that's going on to optimise the hell out of running it will be useful when Qwen4 drops?   submitted by   /u/demomanca [link]   [comments] 27 r/LocalLLaMA community 11d ago Optimal settings for 2 GPUs in LM Studio Hello everybody. I've got a 5070ti and a 5060ti both 16GB in my system which is a 5900X and 64GB DDR4 RAM. I'm trying to run some 16-18GB models like Qwen, Cydonia, Skyfall. I'm having problems utilising the VRAM I have to get the best usage out of it. LM Studio sees the 32GB… 8 r/LocalLLaMA community 11d ago Running Qwen3.8 Flash Next 176B on a 16GB RTX 3080 Laptop + 32GB RAM + SSD I wanted to see how far I could push a fairly ordinary laptop with a huge MoE model. Turns out, Qwen3.8 Flash Next 176B can run on: RTX 3080 Laptop — 16GB VRAM 32GB system RAM SSD No 128GB/256GB RAM workstation and no multi-GPU setup. I’m running it with TensorSharp , my… 36 r/LocalLLaMA community 11d ago I built Ninfer 4080 for 16GB class GPUs Hi everyone, TL/DR I created NInfer 4080 to run ISTA-DASLab-Qwen-3.8-27B-GSQ at 100k context on an RTX 4080 16GB GPU using way more of the hardware capabilities ( max overall: 2720 tok/s prefill, 262 tok/s generation ) and sharing it with the community now so others can also… 6 r/LocalLLaMA community 11d ago I built a code knowledge graph tool that's actually MIT licensed (fully local, no cloud) So this is maybe a niche problem, but at my job I work on a huge Python codebase and every time I change some shared function I'm basically playing roulette. grep tells who mentions it in the code base, not who actually calls it. And more essentially, Claude Code (my major… 15 r/LocalLLaMA community 11d ago Two local Qwen ( 3.8 27b unsloth Q6 and Qwen flash next strata coder ) models vs Claude Opus 4.6 on the same 3 coding tasks. One of them tied it. Not here to start a fight, just sharing numbers Innanzitutto, due cose per evitare fraintendimenti. Non sto cercando di sostenere che un modello o un'azienda siano migliori. Non ho alcun interesse personale in nessuno di essi. Volevo solo verificare personalmente come si comportano nello stesso contesto lavorativo. E il… 19 llama.cpp releases dev-tools 11d ago b11379 server : fix laya abort by limiting n_batch to n_ubatch ( #29903 ) server : fix laya abort by limiting n_batch to n_ubatch Fixes #29902 Assisted-by: Claude fix(review) : rm tests, embeddings cond Website: https://llama.app Attestations:… 30 r/LocalLLaMA community 11d ago POV 8GB VRAM + 16GB RAM folks checking locallama everyday: One can only hope for Qwen4 35B A3B or similar (maybe with extra ngrams for 35B -> 70B+... until then, Gemma 26B QAT my beloved (solid 26 Tg/s)...   submitted by   /u/RobustLokiX [link]   [comments] 32 r/LocalLLaMA community 11d ago Two ~300B MoE models, each on ONE 128 GB mini PC (AMD Strix Halo): GLM-5.3-Flash at ~580 tok/s prefill, MiMo-V2.6-Flash up to 44 tok/s decode. EXL3 weights + open ROCm engine We built an engine, Kyojin, on top of ExLlamaV3 for Strix Halo (gfx1151, ROCm), and packed two 300B-class MoE models so each fits one 128 GB machine. First release, all measured on Ryzen AI Max+ 395. Model GLM-5.3-Flash MiMo-V2.6-Flash-MOPD Size 99.7 GB 105 GB Prefill 580 tok/s… 19 r/LocalLLaMA community 11d ago Qwen Flash next on 64GB RAM unified iGPU anyone ? (non-mac) I've seen people reporting running it with 12GB VRAM + 64 GB RAM. Also with 64 GB RAM unified in Macs, but I was wondering if it's possible with any inference backend to run it for example on a 64 GB RAM minipc+ iGPU (780m in my case). I'm currently running 125B Ling 3.0 flash… 13 llama.cpp releases dev-tools 11d ago b11374 ggml-openvino: update to 2026.4.1, optimize performance, expand ops, improve device listing. ( #29852 ) ggml-openvino : Qwen3.5 MoE perf ( #312 ) Squash of ravi9#312 : ggml-openvino: add detailed inference profiling (Yu, Zijun) ggml-openvino: use remote output tensors by default… 16 llama.cpp releases dev-tools 11d ago b11372 qwen4exp : halve the indexer score memory ( #29825 ) qwen4exp : halve the indexer score memory The indexer scored all heads in one product and rectified a copy of it, so two [n_pool, n_idx_h, n_tokens] f32 tensors were live at once, the largest buffers of the graph at long… 25 r/LocalLLaMA community 11d ago gufo_windows pre-package for Strix Halo users In the latest release of the completely unofficial gufo port to windows I've added a pre-packaged library that you can use to try out gufo for yourself. No need to build anything just grab the .zip and unpack it. I've also added start.cmd for easily starting the server, it will… 4 r/LocalLLaMA community 11d ago I tried building a small RAG search node for Qwen3.8 27B using a fake AliExpress Mini PC... and Intel sent me back to 2018. I love Qwen3.8 27B so much that I decided to show my gratitude to the Alibaba ecosystem by building a dedicated RAG/search node using a cheap Mini PC from AliExpress. Turns out, my ecosystem loyalty got rewarded with an absolute masterpiece of fraud: Promised: Intel N150 +… 15 r/LocalLLaMA community 11d ago Qwen3.8-Flash-Next 177B running at 11–15 tok/s on a single RTX 5070 12GB + 32GB RAM DDR4 Benchmarking an LLM here with a NVIDIA RTX 5070 12 GB VRAM here I had been working on a llama.cpp based expert streaming setup for Qwen3.8-Flash-Next 177B (UD-IQ3_XXS) on Windows. Benchmark is about 11.5 tok/s, up from roughly 7 tok/s on the inherited setup. In normal… 35 r/LocalLLaMA community 11d ago qwen4exp : halve the indexer score memory by ServeurpersoCom · Pull Request #29825 · ggml-org/llama.cpp Qwen Flash Next now uses less VRAM   submitted by   /u/jacek2023 [link]   [comments] 25 r/LocalLLaMA community 11d ago gufo-Qwen3.6-35B-A3B-Q6dense - 3095tok/s prefill; 190 tok/s decode on Strix Halo   submitted by   /u/nubela [link]   [comments] 6 arXiv — Machine Learning research 11d ago When Do Attention-Head Ablations Support Causal Claims? Projection-Level Confounds, Floor Effects, and Matched Controls arXiv:2610.00373v1 Announce Type: new Abstract: Attention-head ablation, zeroing a head and measuring the resulting change in task performance, is a common method for inferring which components of a language model are causally responsible for a behavior. We show using GPT-2… 27 arXiv — Machine Learning research 11d ago Misalignment of Low-Loss Regions Causes Grokking arXiv:2610.00620v1 Announce Type: new Abstract: Grokking refers to the delayed emergence of validation-set generalization after a model has already overfit the training set. Although first observed in small algorithmic tasks trained with transformers, its underlying mechanism… 18 r/LocalLLaMA community 11d ago Anyone sitting on a lot of slow system memory and a modest GPU.. try Strata + Qwen3.8 Next. IQ3_XXS weights are just under 80GB and my slowww DDR4+7900XTX is stabilizing around 45-70/s (sometimes higher while coding depending on mtp). Looking online I'm seeing similar results for users with 12GB and 16GB cards, and significantly faster numbers for owners of DDR5. (In… 22 r/LocalLLaMA community 12d ago Unitree just dropped UnifoLM-WLA-1.0 — a single 6B model that does 64 whole-body + tabletop tasks on a real humanoid https://unigen-x.github.io/unifolm-wla.github.io/ Unitree Robotics released UnifoLM-WLA-1.0, their new general-purpose humanoid foundation model. Key points: • 6B parameters • Trained on ~2,500 hours of real robot data • One model handles 64 tasks (10 whole-body + 54 tabletop) •… 6 llama.cpp releases dev-tools 12d ago b11355 vulkan: disable large matmul tile on Samsung GPUs with 32KB shared memory ( #28531 ) Assisted-by: Claude Opus Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/52313922 macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64,… 13 llama.cpp releases dev-tools 12d ago b11352 qwen4exp : optimize mask constructions ( #29824 ) qwen4exp : optimize mask constructions cont : apply the same change for GLM5-next Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/52303821 macOS/iOS: macOS Apple Silicon (arm64) macOS… 31 r/LocalLLaMA community 12d ago I spent 3 weeks testing local Qwen3.8 on the new low-latency SGLang/vLLM recipes: DFlash2 2.8x. Builds: RadixArk + Inferact 27B NVFP4, 27B BF16, orcarouter 27B Uncensored, Flash-Next NVFP4 Hey guys, Last time I tested Qwen3.8-Flash-Next on its own. This time I put three Qwen3.8 checkpoints through the same 10 tests on the same RTX PRO 6000: RadixArk/Qwen3.8-27B-NVFP4 (dense) orcarouter/Qwen3.8-27B-Uncensored-NVFP4 (dense, uncensored fine-tune)… 20 Hacker News — AI on Front Page community 12d ago Zig v0.17.0 Article URL: https://ziglang.org/download/0.17.0/release-notes.html Comments URL: https://news.ycombinator.com/item?id=49938521 Points: 203 # Comments: 120 22 r/LocalLLaMA community 12d ago microsoft/FrogNano-4B-2609 · Hugging Face An agentic model from Microsoft for the GPU poor https://huggingface.co/bartowski/FrogNano-4B-2609-GGUF FrogNano is derived from Qwen/Qwen3.5-4B, a general-purpose post-trained model designed for language, reasoning, coding, agentic, and multimodal tasks. FrogNano inherits… 22 r/LocalLLaMA community 12d ago CUDA: fuse shared experts into MMVQ by am17an · Pull Request #29184 · ggml-org/llama.cpp MoE speedup, but only for some MoE architectures (like Qwen 35B A3B)   submitted by   /u/jacek2023 [link]   [comments] 22 r/LocalLLaMA community 12d ago Heavily quantized Qwen3.8-Flash vs Q8 Qwen3.8-27B - thoughts? I'm currently choosing between IQ3_XXS Qwen-3.8-Flash and Q8_0 27B. This month I don't have anything complex enough to justify either's potential so I've got a fairly bad read on how these two stack up in terms of intelligence. Have any of you compared the two enough to speak to… 33 r/LocalLLaMA community 12d ago I made my iPhone a second GPU for my 24 GB MacBook: Qwen 3.8 27B prefills 29–44% faster & my holds part of the CTX window. **DISCLAIMER** THE PREFILLING TPS SHOWN ON THE PHONE IS COMPUTED ONLY FOR THE LAYERS IT HOLDS. ALREADY FIXING IT TO SHOW END-TO-END PREFILL RATE. NUMBERS BELOW ARE ACCURATE FOR E2E PREFILL RATE. Every file or tool result my agent reads on a 24 GB M4 Pro MacBook is a wait, and… 33 r/LocalLLaMA community 12d ago RTX Spark laptops and mini desktops rumored to launch Oct 7th (24GB to 128GB variants possibly) Basically a DGX Spark minus the ConnectX-7 ports. I’ve seen expected initial pricing from like $1800 to $2900. Not sure what configurations are actually at those price points. It’s all Internet hearsay until we actually see these things ship, but it’s nice to know that it’s… 30 OpenAI official-blog 12d ago A model guide for the GPT-6 family Learn how startups can choose GPT-6 models, tune reasoning effort, improve prompts and skills, coordinate tools, and prepare workflows for production. 7 r/LocalLLaMA community 12d ago Qwen3.8-27B-Humanlike-Chat 2.0: texts like a human, now with tool calls and better instruction following Last month I posted a Qwen3.8-27B LoRA that makes it talk like a person instead of an assistant. It got a lot more attention than I expected: 700+ upvotes, 248 comments and 44k downloads since. I read every comment. People really don't like assistant speak, so its tone of voice… 22 LangChain releases dev-tools 12d ago langchain-text-splitters==1.1.3 Changes since langchain-text-splitters==1.1.2 release(text-splitters): 1.1.3 ( #41001 ) chore(deps): bump the minor-and-patch group across 3 directories with 4 updates ( #40969 ) chore(deps): bump tornado from 6.5.9 to 6.5.10 in /libs/text-splitters ( #40971 ) chore(deps): bump… 4 Page 8 of 10 · 500 articles ← Newer Older →