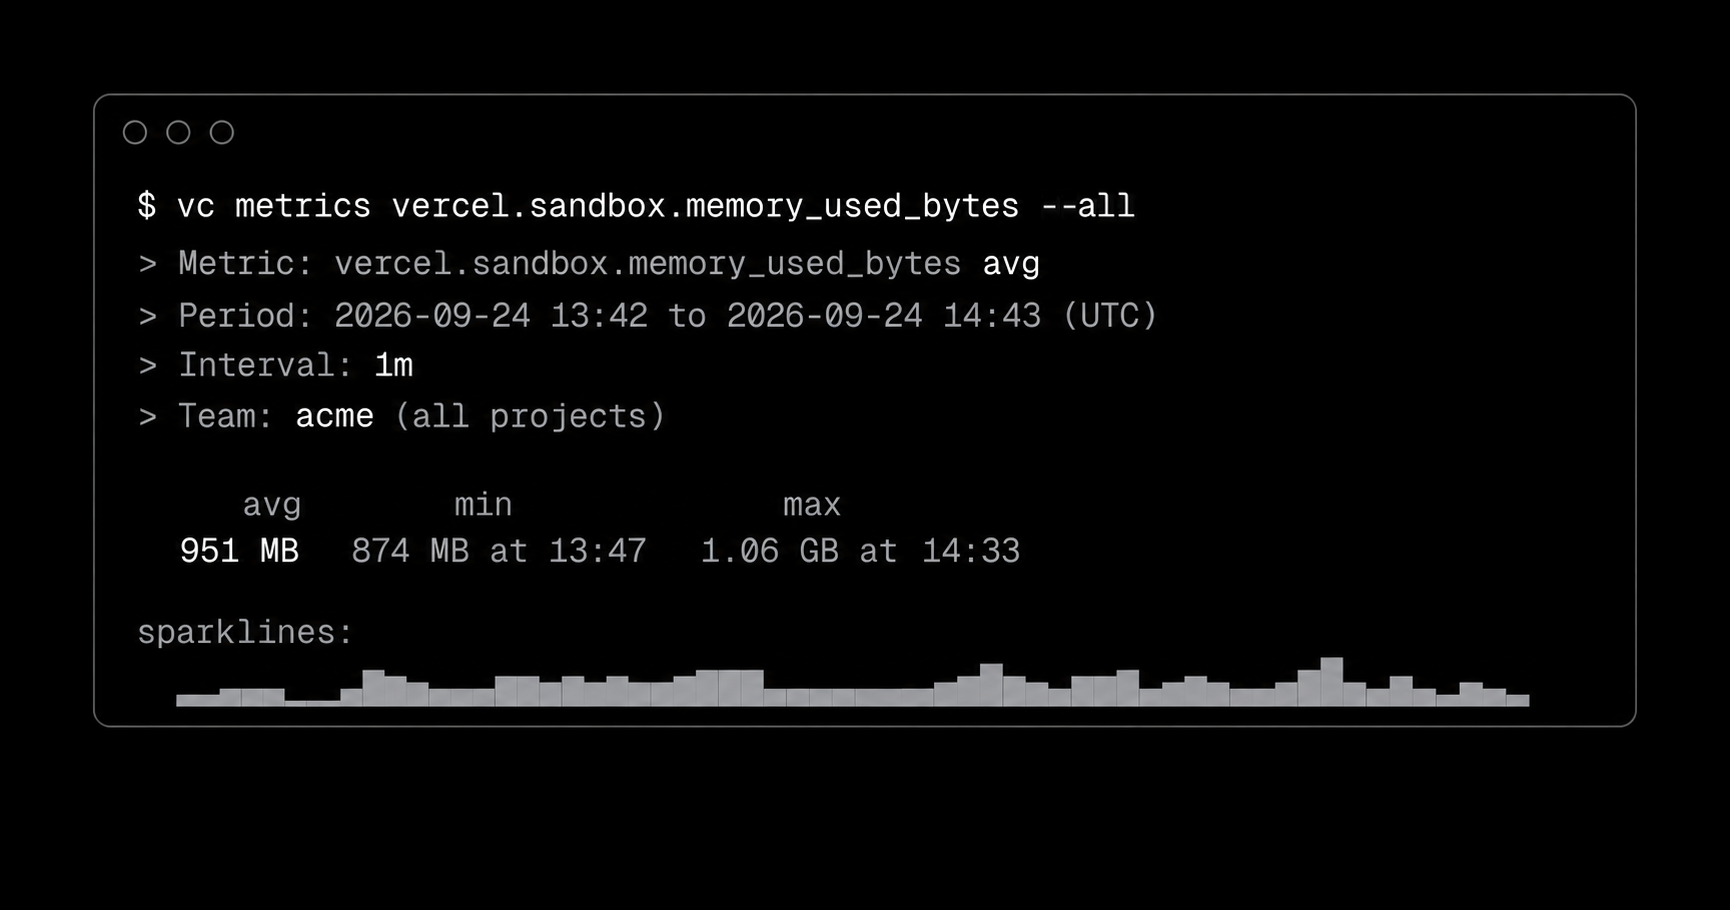
News / #rag Tag Rag 500 articles archived under #rag · RSS Sign in to follow r/LocalLLaMA community 18d ago How accessible is local AI actually, and what happens if affordable access to frontier models doesn’t last? Sometimes it’s easy to forget that this sub and others like it are probably the extreme minority when it comes to this hobby. Most people, I would think, don’t use or can’t afford one good GPU, let alone multiple GPUs, Mac Studios, Sparks, Strix Halos, etc. Is the average tech… 14 r/MachineLearning community 18d ago My frozen-encoder decision heads were reading 3 tokens per label: fixing the option budget took banking77 from 67.5% to 76.0% [P] I distil the closed decisions an app asks an LLM for (pick a label, yes/no, a score) into small heads on a frozen 400M ModernBERT encoder, the open Laya checkpoint. Per decision I train the head Laya ships (type embedding, two transformer layers, a scorer over option markers),… 16 arXiv — Machine Learning research 19d ago Federated Learning of AnDE Classifiers arXiv:2609.28695v1 Announce Type: new Abstract: This work presents a federated framework for training Averaged $n$-Dependence Estimators (AnDE) in distributed environments. The proposed method focuses on the discriminative setting, where model weights are learned locally and… 16 arXiv — Machine Learning research 19d ago Vector Bellman Theory for Multichain Robust Average-Reward Markov Decision Processes arXiv:2609.28792v1 Announce Type: new Abstract: Robust average-reward Markov decision processes provide a fundamental framework for long-term performance optimization under uncertainty, and can have optimal long-run rewards that depend on the initial state. This state dependence… 9 arXiv — Machine Learning research 19d ago The Impossible Trinity of Time-Series Validation: A Conservation Law among Training Sufficiency, Test Coverage, and Temporal Causality arXiv:2609.29530v1 Announce Type: new Abstract: Validating a model on a time series asks for three things at once: each training run should use most of the sample (sufficiency), the test sets should together cover most of the sample (coverage), and training data should come… 5 arXiv — Machine Learning research 19d ago Classifier-Dependent Benefits of Pseudo-Labeling for Semi-Supervised Android Malware Attribution arXiv:2609.29564v1 Announce Type: new Abstract: Detecting and classifying Android malware families remains challenging due to high feature dimensionality, class imbalance, and the high cost of expert-labeled data. Semi-supervised learning (SSL) offers a way to leverage unlabeled… 21 arXiv — Machine Learning research 19d ago Active Client Selection in Federated Trajectory Prediction with Uncertainty-Awareness and Heterogeneous Complexity arXiv:2609.29600v1 Announce Type: new Abstract: Training sequence models such as transformers is now standard for autonomous vehicle trajectory prediction, yet assembling high-quality centralized datasets remains challenging because real-world trajectories are fragmented across… 38 arXiv — Machine Learning research 19d ago A Manifold-Aware Topic Modeling Approach via Rank-Based Prototypes arXiv:2609.29630v1 Announce Type: new Abstract: Recent topic models leverage pretrained embeddings, but neural architectures produce latent representations without grounding in specific texts, and clustering-based pipelines assign representative documents only post hoc, relying… 14 arXiv — Machine Learning research 19d ago TopU-LBVS: A Realistic Multi Target Benchmark for Ligand Based Virtual Screening arXiv:2609.29740v1 Announce Type: new Abstract: Ligand-based virtual screening (LBVS) is a practical first-pass tool in early-stage drug discovery, but existing benchmarks can overestimate performance through random negatives, easy decoys, limited target coverage, and… 25 arXiv — Machine Learning research 19d ago Spatio-temporally complementary feature propagation on graphs for longitudinal AADT estimation arXiv:2609.29906v1 Announce Type: new Abstract: The estimation of Annual Average Daily Traffic (AADT) is vital for transportation planning and infrastructure maintenance, yet obtaining accurate values for an entire urban network across multiple years remains challenging due to… 17 arXiv — NLP / Computation & Language research 19d ago Polite but Misaligned: Evaluating LLM Politeness Judgments Against Human Pragmatic Norms arXiv:2609.29001v1 Announce Type: new Abstract: Despite strong performance on standard benchmarks, it remains unclear whether large language models (LLMs) evaluate social pragmatics in ways that align with human judgments. We evaluate LLM politeness judgments using two… 8 arXiv — NLP / Computation & Language research 19d ago Predicting Emerging Topics from Outliers: A Prospective Study of Weak Signals in Embedding Space arXiv:2609.29183v1 Announce Type: new Abstract: Some documents that embedding-based topic models initially classify as noise later become founding members of emerging topics. At publication time, however, they appear as scattered points in embedding space and are difficult to… 37 arXiv — NLP / Computation & Language research 19d ago Clinical Intent Extraction: A FHIR-Aligned Representation and the CIRCA Benchmark arXiv:2609.29479v1 Announce Type: new Abstract: Prospective clinical actions, the follow-ups, orders, referrals, and instructions that deter-mine what happens to a patient next, are annotated today in thin fragments across incom-patible corpora: each records a text span and one… 11 arXiv — NLP / Computation & Language research 19d ago How To Do Things With Prompts arXiv:2609.29657v1 Announce Type: new Abstract: When users address large language models, they produce directive speech acts whose pragmatic features differ from those of both everyday conversation and traditional human-computer interaction, and these features change as users… 24 arXiv — NLP / Computation & Language research 19d ago Named Entity Recognition using Sliding Window Approach arXiv:2609.29682v1 Announce Type: new Abstract: Named Entity Recognition (NER) is a core NLP task, but transformer-based sentence-level models struggle with long documents because of fixed input-length limits: truncation drops content, and non-overlapping chunking fragments… 8 arXiv — NLP / Computation & Language research 19d ago Automated Regulatory Compliance Question Answering in Financial Services with Domain-Adapted Retrieval-Augmented Generation arXiv:2609.30009v1 Announce Type: new Abstract: Financial institutions operate under dense, frequently amended rulebooks, and answering a compliance question correctly requires not only fluency but verifiable grounding in the authoritative text. Large language models are… 29 arXiv — NLP / Computation & Language research 19d ago Artificial Societies Benchmark: A Validation Framework for Synthetic Research arXiv:2609.30030v1 Announce Type: new Abstract: A synthetic survey can reproduce the average answer while misrepresenting how people differ, how their answers relate to one another, or how they respond to changes in conditions. We introduce the Artificial Societies Benchmark to… 20 arXiv — NLP / Computation & Language research 19d ago How Reproducible Are Evaluation Conclusions? A Self-Audit of LLM-Inferred Prompt Structure arXiv:2609.30074v1 Announce Type: new Abstract: Evaluations of LLM systems routinely average over small prompt sets and report models as a ranked table. We ask how much confidence such a table deserves, using LLM-based prompt-structure inference as the case study: eight open… 14 arXiv — NLP / Computation & Language research 19d ago Return or Revise? Learning When Revision Helps Retrieval-Augmented QA arXiv:2609.30087v1 Announce Type: new Abstract: We consider the decision of whether to return an existing draft answer or revise it using retrieved evidence, as in answer-revision systems. Draft confidence estimates whether the current answer is correct, but the decision… 10 arXiv — NLP / Computation & Language research 19d ago ARGUS: Role-Aware Event Knowledge Graphs for U.S. Employment-Discrimination Complaints arXiv:2609.30184v1 Announce Type: new Abstract: U.S. employment-discrimination complaints describe complex event sequences that are not explicitly captured by lexical or embedding-based representations alone. We present ARGUS, a source-grounded pipeline that combines a… 20 arXiv — NLP / Computation & Language research 19d ago The Fellowship of the Query: Learning Retrieval Actions arXiv:2609.28653v1 Announce Type: cross Abstract: Retrieval-augmented question answering requires control decisions about when to decompose a question, search, reformulate, extract evidence, synthesize facts, verify progress, and stop. We study whether trajectory fine-tuning can… 16 arXiv — NLP / Computation & Language research 19d ago CRISS: A Retrieval-Augmented AI Chatbot for Assisting Cancer Registrars arXiv:2609.29075v1 Announce Type: cross Abstract: Cancer registrars, including Oncology Data Specialists (ODSs), must interpret complex and frequently updated coding and staging standards. We developed CRISS (Cancer Registry Intelligent Support System), a retrieval-augmented… 19 Ollama releases dev-tools 19d ago v0.40.0-rc0: llama-server: prepare to remove compatibility patch Add manifest-list storage so runner-specific manifests can coexist under one tag while preserving existing v1 tags as best-effort downgrade anchors. Show/list/copy/remove/pull/push now understand runner and digest selection and transfer referenced child manifests and layers. Add… 38 Vercel — AI dev-tools 20d ago Vercel Sandbox now supports memory observability Vercel Sandbox observability now includes memory usage data. You can access sandbox memory usage data in the dashboard and through the CLI via the vercel metrics command. Sandbox observability memory in the dashboard The Memory Usage card reports average, P75, and P95 memory… 17 arXiv — Machine Learning research 20d ago COPE: Continual Personalization of LLMs under Sparse User Feedback via User Embeddings and Self-Evaluation arXiv:2609.26853v1 Announce Type: new Abstract: While Large Language Models (LLMs) have achieved remarkable results across various benchmarks, their alignment with normative values often results in homogenized responses that fail to address diverse user preferences. Existing… 5 arXiv — Machine Learning research 20d ago On Preference Coverage Collapse from Hindsight Relabeling in Multi-Objective Reinforcement Learning arXiv:2609.26918v1 Announce Type: new Abstract: Hindsight relabeling which retroactively replacing a transition's goal with the outcome the agent actually achieved is an effective tool for improving sample-efficiency in Reinforcement Learning (RL). A natural extension to… 23 arXiv — Machine Learning research 20d ago ZO-COSMO: Index-Free One-Hop Mixing for Decentralized Zeroth-Order Optimization arXiv:2609.27199v1 Announce Type: new Abstract: Sparse communication in decentralized zeroth-order learning requires compatible peer-state coordinates. We characterize this one-hop condition and develop \textsf{ZO-COSMO}, coupling two-query estimation with average-preserving… 11 arXiv — Machine Learning research 20d ago Tail-Aware Geometry Learning for Conformal Ellipsoids arXiv:2609.27221v1 Announce Type: new Abstract: This paper studies multivariate conformal prediction (CP), a distribution-free uncertainty quantification framework with finite-sample coverage guarantees. The efficiency of multivariate prediction sets hinges critically on the… 37 arXiv — Machine Learning research 20d ago Pheno-GS: Phenoscape-scale Geodesic Sinkhorn arXiv:2609.27633v1 Announce Type: new Abstract: High-throughput single-cell data is now collected across large patient cohorts. Understanding patient-level heterogeneity from cellular-level data motivates phenoscaping: embedding each single-cell distribution as a "datapoint,"… 24 arXiv — Machine Learning research 20d ago Learning to Detect Symbolic Failure: Machine Learning and the Limits of Black-Scholes arXiv:2609.27764v1 Announce Type: new Abstract: We treat options pricing as a representation problem: can machine learning detect systematic deviations from Black-Scholes using 2.6M real option contracts? We compare three regimes: learned abstract embeddings (Kernel PCA),… 12 arXiv — Machine Learning research 20d ago When Adaptation Hurts: Split Sensitivity and Person-Level Negative Transfer in Federated Wearable Onboarding arXiv:2609.27819v1 Announce Type: new Abstract: Federated wearable models eventually serve people absent from source training, but favorable average accuracy does not establish that unlabeled onboarding helps each person. We evaluate six core onboarding strategies on five… 20 arXiv — Machine Learning research 20d ago Quality over Quantity: Semi-Supervised Detection of Illicit Bitcoin Flows via Feature Engineering arXiv:2609.27936v1 Announce Type: new Abstract: Detecting illicit cryptocurrency transactions is hampered by extreme class imbalance, adversarial obfuscation, and a scarcity of reliable labels. While semi-supervised learning (SSL) offers a promising solution by leveraging… 8 arXiv — Machine Learning research 20d ago Shared Global KV with Layer-Specific Local History arXiv:2609.28006v1 Announce Type: new Abstract: Decoder-only Transformer language models cache keys and values (KV) to reuse past computation during generation. Sharing KV across layers saves storage but reduces the diversity of representations available across depth. We study… 20 arXiv — NLP / Computation & Language research 20d ago LEGO: Synergizing Expert GraphRAG and Expert Chain-of-Thought for Legal Reasoning arXiv:2609.27009v1 Announce Type: new Abstract: Large language models are increasingly applied to high-risk domains such as law, yet complex legal reasoning remains limited by two structural challenges. First, existing RAG and GraphRAG methods emphasize lexical or semantic… 10 arXiv — NLP / Computation & Language research 20d ago LexLattice: Multilingual Extractive Summarization via Neural Cellular Automata on Document Hierarchies arXiv:2609.27032v1 Announce Type: new Abstract: Faithfulness is a central concern in legal text summarization, which motivates extractive approaches that select verbatim content traceable to its source. Such methods typically rank paragraphs or other structural units in… 12 arXiv — NLP / Computation & Language research 20d ago Meet, Compare, or Abstain: LatWeave for Deterministic Multi-Hop Question Answering on Knowledge Lattices arXiv:2609.27225v1 Announce Type: new Abstract: Probabilistic question-answering systems -- whether large language models (LLMs) themselves, retrieval-augmented generation (RAG), or trained multi-hop retrievers -- conflate "what is known" and "how to reason" into a single… 15 arXiv — NLP / Computation & Language research 20d ago Automated Extraction of Records of Processing Activities (RoPA) Using Hybrid RAG and Locally Deployed Large Language Models arXiv:2609.27359v1 Announce Type: new Abstract: Vietnam's Personal Data Protection Law (Law No. 91/2025/QH15) and Decree No. 356/2025/ND-CP, effective January 1, 2026, require organizations to establish and maintain Records of Processing Activities (RoPA). Manual RoPA… 10 arXiv — NLP / Computation & Language research 20d ago AraGenre 2026: A Hierarchical Definition-Guided Arabic Genre Classification Shared Task arXiv:2609.27387v1 Announce Type: new Abstract: AraGenre is a shared task on hierarchical, definition-guided Arabic genre classification, motivated by the limited availability of annotated data in Arabic and other low-resource languages. Systems assign each Arabic text segment… 38 arXiv — NLP / Computation & Language research 20d ago LabourCrew: A Multi-Agent RAG Framework for Trustworthy Adversarial Deliberation and Statutory Reasoning over Labour Law arXiv:2609.27814v1 Announce Type: new Abstract: In statutory question answering, every claim must be traceable to evidence, not merely relevant, since unverifiable labour-rights answers carry serious legal consequences. Current systems fall short: single-pass RAG cannot detect… 30 arXiv — NLP / Computation & Language research 20d ago Risk-Controlled KV-Cache Eviction: From Memory Budgets to Risk Targets arXiv:2609.27981v1 Announce Type: new Abstract: KV-cache eviction is typically evaluated through average quality-memory trade-offs, yet a small average loss can hide requests whose utility degrades materially. We reformulate eviction as a deployment risk-control problem: a… 26 arXiv — NLP / Computation & Language research 20d ago TEMPS: Temporal Sentence Embeddings for Temporal Information Retrieval arXiv:2609.28048v1 Announce Type: new Abstract: Modern information retrieval (IR) systems rarely represent time, yet many information needs depend on it: in clinical, journalistic, and legal search, when an event occurred can decide whether a document is relevant. Dense… 22 arXiv — NLP / Computation & Language research 20d ago Computation Over Geometry: Meaning Identity Is Computed, Not Shipped in the Embeddings arXiv:2609.28290v1 Announce Type: new Abstract: Meaning identity (whether two sentences say the same thing after wording changes) is treated in retrieval and RAG as a geometric fact about independently encoded sentence vectors. We show that, for frozen off-the-shelf encoders and… 4 arXiv — NLP / Computation & Language research 20d ago Agentic Governance and Adversarial Verification for Policy-Constrained LLM Healthcare Appeal Generation arXiv:2609.27844v1 Announce Type: cross Abstract: Claim denial management costs U.S. healthcare approximately $260 billion annually in administrative overhead. Large Language Models (LLMs) and Retrieval-Augmented Generation (RAG) can produce fluent clinical text, but… 11 Hacker News — AI on Front Page community 21d ago Linux support is coming to Snapdragon X2 Series Article URL: https://www.qualcomm.com/news/onq/2026/09/snapdragon-summit-agentic-ai-pcs-linux Comments URL: https://news.ycombinator.com/item?id=49823582 Points: 322 # Comments: 138 12 llama.cpp releases dev-tools 21d ago v0.5.0 Overview This release focuses on backend performance and correctness, broader model coverage, and more robust server/router operation. It adds HRM-Text (DFM Mimir 1B) support, MiMo-V2.6 and HunyuanOCR conversion support, ggml 0.25.0 backend improvements, multi-address HTTP… 26 NVIDIA Developer Blog official-blog 21d ago Manage Kubernetes Node Fleets with NodeWright Kubernetes manages what runs on your nodes. Managing the nodes themselves is the challenge: kernel settings, system packages, storage layouts, security agents,... 18 arXiv — Machine Learning research 21d ago Terminal Shrinkage Averaging Reveals a Schedule-Estimator Interaction in LLM Pretraining arXiv:2609.25482v1 Announce Type: new Abstract: Large language model (LLM) pretraining conventionally returns the raw final iterate. This couples two design choices: the learning-rate schedule that generates the parameter trajectory and the estimator that constructs the deployed… 14 arXiv — Machine Learning research 21d ago From Risk Scoring to Risk Allocation: A Density-Driven Framework for Diverse Monitoring in Multi-Agent Systems arXiv:2609.26146v1 Announce Type: new Abstract: Risk monitoring in multi-agent systems is commonly built on a per-state primitive that scores each state independently and selects the top K. Under crowding, where many agents share the same fragility, this approach picks redundant… 13 arXiv — NLP / Computation & Language research 21d ago A Computational Approach to Measuring Semantic Change in Sanskrit Literature arXiv:2609.25012v1 Announce Type: new Abstract: Diachronic word embeddings have become the modern standard for tracking semantic change, yet they have been largely validated on modern, high-resource, and well-segmented languages. This paper tests whether the paradigm transfers… 7 arXiv — NLP / Computation & Language research 21d ago From Tone to Trajectory: Continuous Sentiment and the Shape of Monetary Policy Communication arXiv:2609.25034v1 Announce Type: new Abstract: Central bank press conferences are not merely information releases --- they are structured narratives. We study whether the shape of sentiment within a statement, not just its average tone, carries policy-relevant signals.… 13 Page 5 of 10 · 500 articles ← Newer Older →