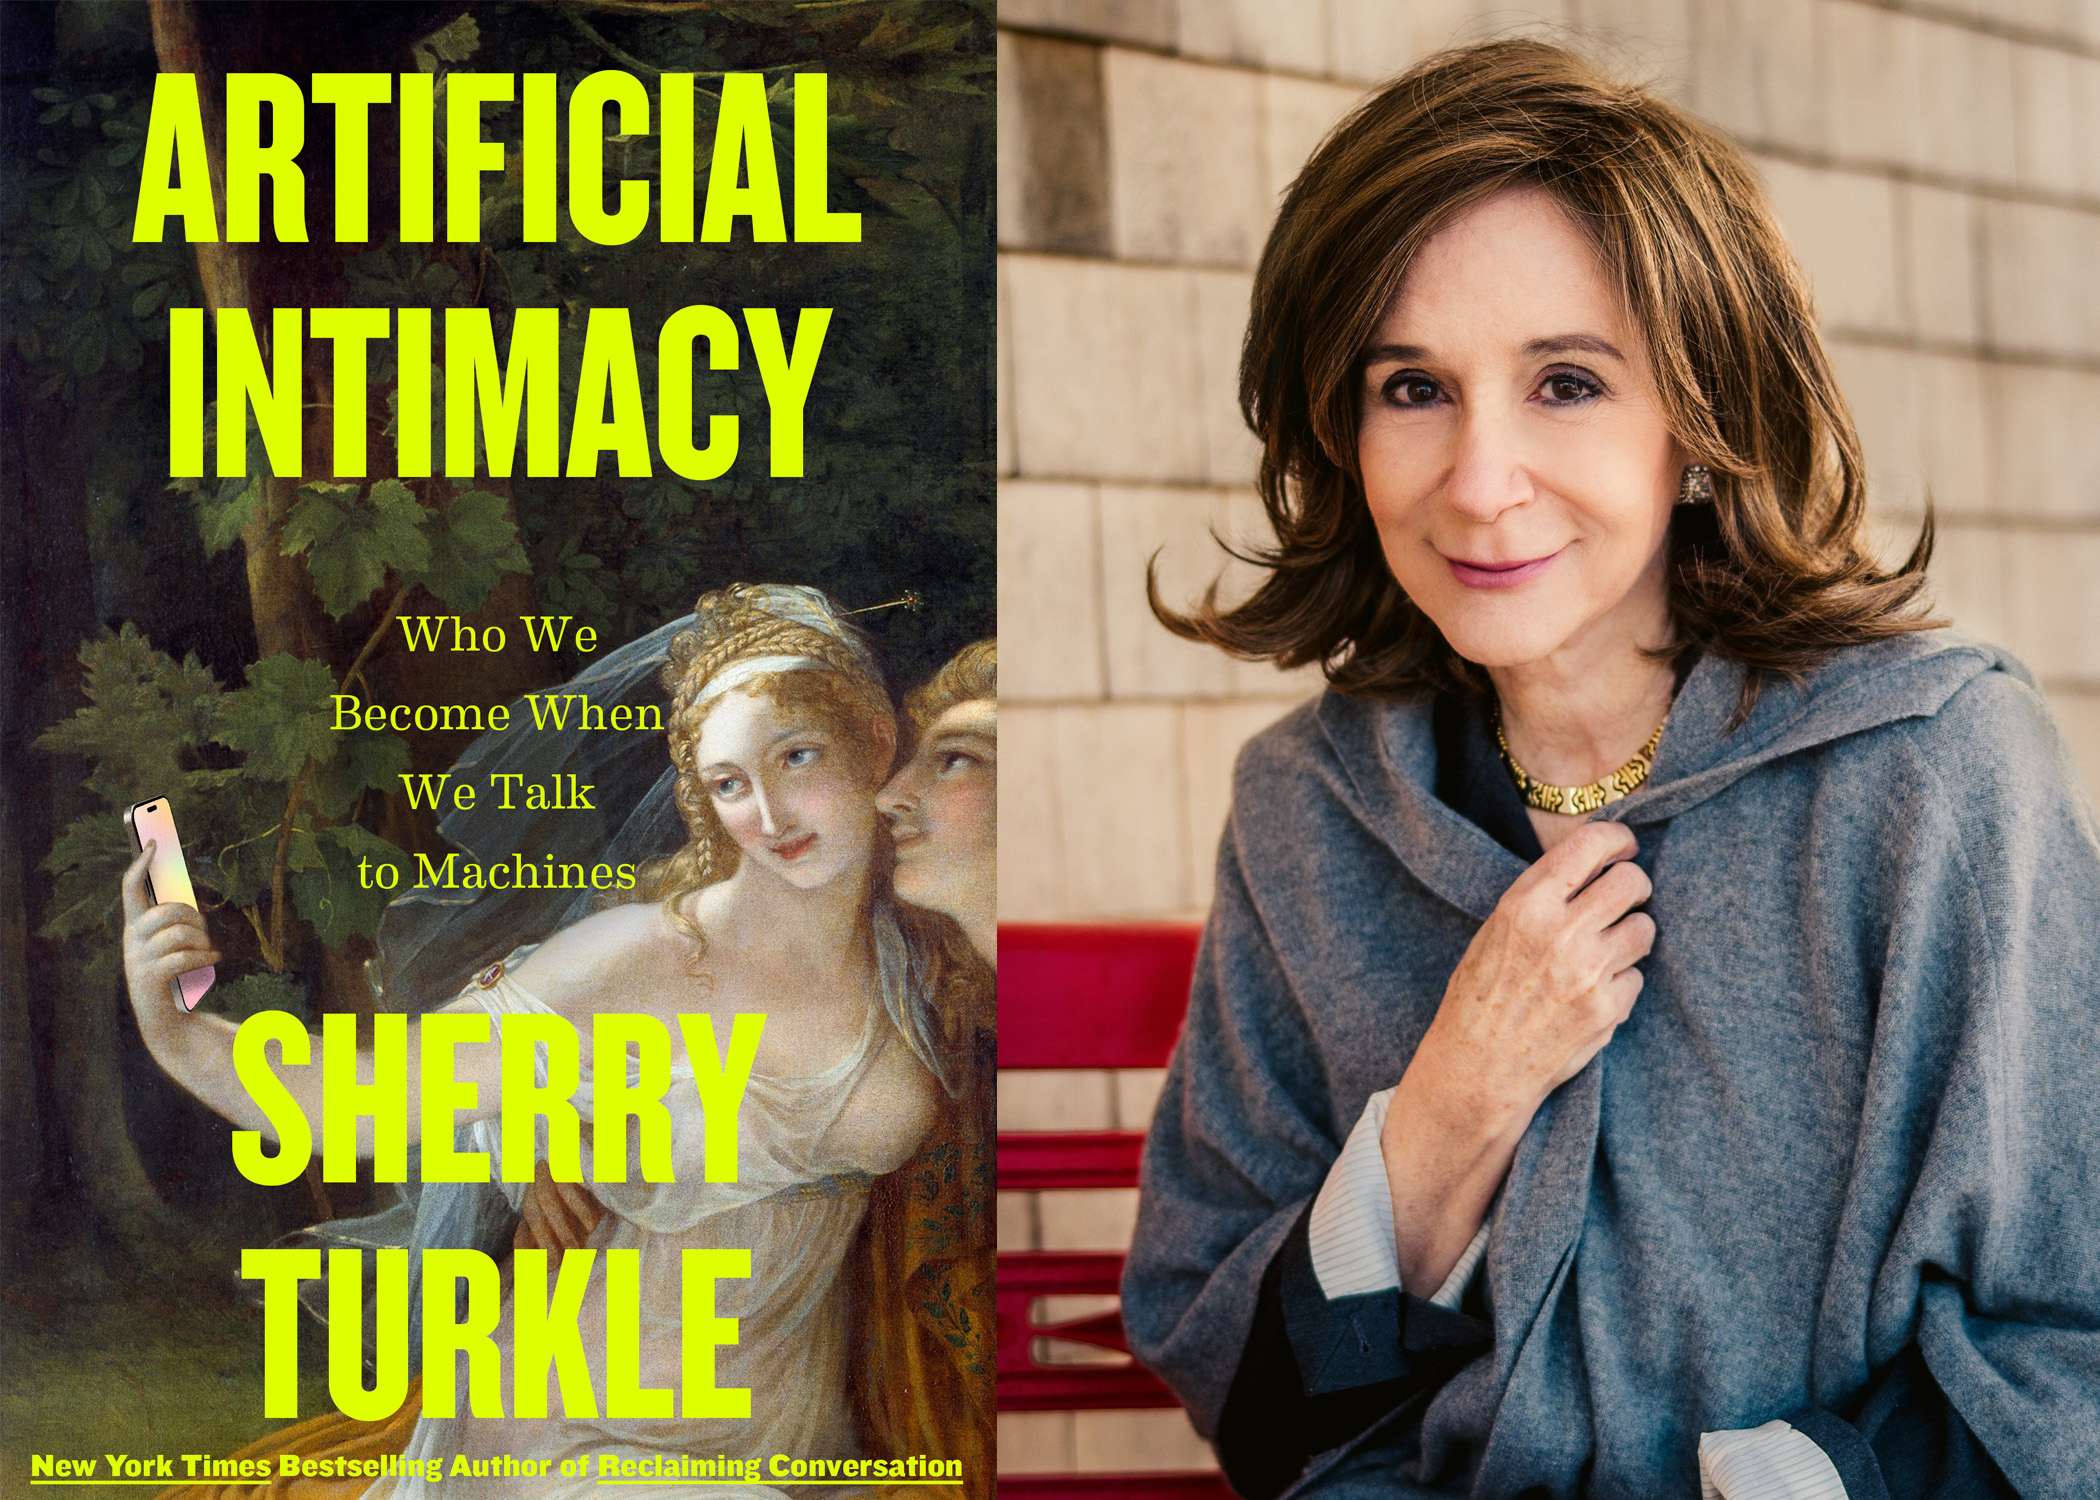
News / #rag Tag Rag 500 articles archived under #rag · RSS Sign in to follow r/LocalLLaMA community 13d ago Unsloth, Swift1.5, Peculiar-Ragdoll, ThinkingCap - Qwen3.8-27B In a previous post I shared comparison between Swift1.5 and peculiar-ragdoll's checkpoints. Added the original unsloth Q4_K_XL and ThinkingCap Q4_K_M (they don't offer L or XL) to the comparison. Here are the results over a 69 set of eval questions. All tests are now run at same… 13 r/LocalLLaMA community 13d ago We benchmarked 18 RAG pipelines against an agent loop on Google's FRAMES. The best pipeline hit 78.9%. The agent loop hit 92.7%. Hybrid search, reranking, query decomposition, and query expansion are often treated as must-haves for good RAG. We wanted to see how much each actually helped, so we tested them. Same model, same embeddings, same documents, across all 824 multi-hop questions in FRAMES. We built… 32 arXiv — NLP / Computation & Language research 13d ago Conformal Factuality Control for Multi-Hop Retrieval-Augmented Generation arXiv:2609.38222v1 Announce Type: new Abstract: Retrieval-augmented generation (RAG) can ground large language models in external evidence, but retrieved context does not guarantee that generated claims are factually supported. This problem is especially relevant in multi-hop… 32 arXiv — NLP / Computation & Language research 13d ago Evaluating Whether LLMs Can Reliably Connect the DOTs? arXiv:2609.38406v1 Announce Type: new Abstract: Access to real-world information is often noisy and fragmented. Constructing a coherent narrative from such fragments requires models to reconstruct missing spans within a broader storyline, commonly referred to as text infilling,… 14 arXiv — NLP / Computation & Language research 13d ago ViLegalExpert: A Large-Scale Benchmark for Vietnamese Legal Retrieval and Question Answering from Real-World Consultations arXiv:2609.39189v1 Announce Type: new Abstract: Trustworthy Legal AI requires systems that can answer legal questions while grounding their responses in authoritative sources. However, existing Vietnamese legal benchmarks provide limited coverage of real-world legal… 13 arXiv — NLP / Computation & Language research 13d ago Explore-on-Graph: Hybrid Embedding-LLM Reasoning for Knowledge Graph Question Answering under Incompleteness arXiv:2609.39786v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly combined with knowledge graphs (KGs) to ground reasoning in structured evidence. However, most LLM-based KGQA methods rely on traversing existing graph edges and become unreliable when… 6 arXiv — NLP / Computation & Language research 13d ago OPTS-TTPO: Enhancing Finite-Sample Policy-Gradient Learning with Tree Search arXiv:2609.40035v1 Announce Type: new Abstract: The policy-gradient theorem gives the exact gradient under the current policy, but finite on-policy samples may miss rare high-return trajectories. We study whether tree search improves their coverage within a fixed budget while… 38 Latent.Space news-outlet 14d ago Why Dwarkesh is Wrong about Computer Use + How OpenAI shipped its Jev competitor in 1 Week Our DevDay coverage - the first pod on the DevDay lineup - dives in with the leaders of OpenAI’s CUA team and API platform. 10 r/LocalLLaMA community 14d ago peculiar-ragdoll's Dirk-Qwen 3.8-27B vs. UkisAI Swift-1.5 Qwen3.8-27B I have a long list of my own domain specific eval questions that I run to validate which models I can rely on: coding, coding (numpy/pandas), data analytics decision making, local RAG, and voice assistant. It's made up of the types of things I'm likely to deal with on the daily.… 6 NVIDIA Developer Blog official-blog 14d ago Expanding AI Storage Access with NVIDIA cuObject and the NVIDIA SCADA Server SDK AI infrastructure engineers, storage developers, and cloud service providers need fast and secure access to high-capacity file and object storage to support AI... 10 r/LocalLLaMA community 14d ago Update: Yandex/AliceAI 80B-A3B fine tune progress loss curve (taken from the last micro of every step, to explain the variation) some help from gemini 3.8 flash high About 40% of the way done with the initial fine tune. The loss is so spiky because I accidentally used the last loss of each micro, rather than the average of each… 24 arXiv — Machine Learning research 14d ago Serverless gossip training of LSTM failure detectors: A matched-protocol comparison with federated, local and centralized learning on NASA C-MAPSS arXiv:2609.35792v1 Announce Type: new Abstract: Industrial predictive maintenance increasingly depends on learning from equipment spread across sites whose sensor data cannot easily be pooled. Federated averaging (FedAvg) solves this with a central aggregation server; gossip… 27 arXiv — Machine Learning research 14d ago HeadGuard: Selective Head Protection for Low-Bit VLM KV-Cache Quantization arXiv:2609.35800v1 Announce Type: new Abstract: Low-bit key-value (KV) cache quantization saves storage but can sharply degrade vision-language model (VLM) accuracy. We introduce HeadGuard, a composable head-protection method that augments a base KV-cache quantizer with a fixed… 29 arXiv — Machine Learning research 14d ago Beyond Keywords: Leveraging Generative LLMs and Label Aggregation to Classify Economic Policy Uncertainty in News Articles arXiv:2609.35856v1 Announce Type: new Abstract: This research describes the adaptation of Large Language Models (LLMs) for economic monitoring in the public sector to automatically determine whether an article discusses Economic Policy Uncertanity (EPU) and to identify its… 24 arXiv — Machine Learning research 14d ago Graph neural networks for sampling-invariant embeddings of organized signal sets arXiv:2609.35934v1 Announce Type: new Abstract: Sensor networks and radars can deliver signals as organized sets, e.g. ordered signals, signals describing range cells within a grid or signals perceived as graph nodes. Within such sets, individual signals may be characterized by… 25 arXiv — Machine Learning research 14d ago GNA: Granular Neighbor Assembly for Retrieval-Augmented Multivariate Time-Series Forecasting arXiv:2609.36281v1 Announce Type: new Abstract: Deep forecasters predict from a fixed-length lookback window, and lengthening it gives diminishing returns at a growing cost. Retrieval augmentation instead shows the model how similar past situations continued. Retrieving a whole… 5 arXiv — Machine Learning research 14d ago The Universal Classifier for Graph Learning arXiv:2609.36302v1 Announce Type: new Abstract: While foundation models have revolutionized natural language processing and computer vision by leveraging universal vocabularies, Graph Machine Learning (GML) remains fractured due to the absence of a unified feature and structural… 37 arXiv — Machine Learning research 14d ago Cheap and Powerful Tests for Supervised Subspaces: Per-Component Inference for PLS arXiv:2609.36307v1 Announce Type: new Abstract: Partial Least Squares (PLS) regression extracts a few outcome-aligned directions in a high-dimensional X and is widely used across applied science, but inference on the resulting fit is either expensive, biased and discouraged, or… 36 arXiv — NLP / Computation & Language research 14d ago Sieve and Sage: Efficient Distraction Filtering for Reliable RALM Abstention arXiv:2609.35794v1 Announce Type: new Abstract: Just as Socrates recognized the limits of his own knowledge, Retrieval-Augmented Language Models (RALMs) should learn to abstain when the retrieved evidence cannot support a reliable response. Existing approaches largely rely on… 12 arXiv — NLP / Computation & Language research 14d ago From Lexical Baselines to Agentic Retrieval-Augmented Generation: Structured Skill and Responsibility-Level Extraction with the SFIA Framework arXiv:2609.35806v1 Announce Type: new Abstract: Automated skill extraction underpins workforce planning, yet most systems represent skills as flat labels with no notion of the responsibility level at which a skill is practiced. The Skills Framework for the Information Age (SFIA)… 30 arXiv — NLP / Computation & Language research 14d ago Beyond the Context Window: An Adaptive Entropy-Based Routing Framework for Hybrid Retrieval and Long-Context Language Models arXiv:2609.35831v1 Announce Type: new Abstract: Modern large language models now support context windows of more than one million tokens, which has raised the question of whether retrieval-augmented generation (RAG) is still necessary. Pure long-context (LC) processing is… 9 arXiv — NLP / Computation & Language research 14d ago Eternal Sunshine of the Spotless Mind: Systematically Erasing LLM's Memories arXiv:2609.36414v1 Announce Type: new Abstract: We consider persistent LLMs that accumulate memories of their interactions with a user over time. Such LLMs maintain memories using external storage, which they can query to overcome the limitations of a fixed context window. Such… 20 arXiv — NLP / Computation & Language research 14d ago Grounded Revision vs. Prior Injection: Probing Retrieval-Augmented Patent Claim Amendment arXiv:2609.36550v1 Announce Type: new Abstract: Retrieval-augmented generation is widely used in professional writing, yet whether retrieval grounds revision or merely injects templates is rarely tested where "correct" has a definable meaning. Patent claim amendment supplies… 7 arXiv — NLP / Computation & Language research 14d ago Lost in Conversation or Lost in Translation? Diagnosing Multi-Turn Degradation in RAG arXiv:2609.36700v1 Announce Type: new Abstract: When conversing with large language models (LLMs), users often begin with a simple question and build towards a multi-hop question through follow-up turns. Retrieval-augmented generation (RAG) and its graph-based variant (GraphRAG)… 20 arXiv — NLP / Computation & Language research 14d ago Momentum-Coupled Rubric Adaptation for Detailed Image Captioning arXiv:2609.36893v1 Announce Type: new Abstract: Detailed image captioning requires accurate and comprehensive descriptions of fine-grained visual content, yet caption quality spans factual accuracy, information coverage, and clarity. Compared with conventional methods that rely… 34 arXiv — NLP / Computation & Language research 14d ago ER-JEPA: Experience Replay Improves Joint-Embedding Predictive Learning in Language Models arXiv:2609.36952v1 Announce Type: new Abstract: Large language models (LLMs) excel at token-level generation but may learn undesirable abstract semantics and lack comprehensive perception. LLM-JEPA mitigates this by aligning different views of the same underlying knowledge via a… 6 arXiv — NLP / Computation & Language research 14d ago AMU:Admission and Memory Update for Personalized Conversations---Structured Memory with SLM Guided Control arXiv:2609.36976v1 Announce Type: new Abstract: Large language models (LLMs) have become the foundation of personalized assistants, but maintaining persistent user memory across long-term interactions remains challenging. Existing memory systems often focus on storage,… 20 arXiv — NLP / Computation & Language research 14d ago Bridging Semantic Gaps in RAG through Generated Context Knowledge Fusion arXiv:2609.37171v1 Announce Type: new Abstract: Retrieval-Augmented Generation has established itself as a fundamental framework in natural language processing, seamlessly integrating information retrieval with the generative capabilities of large language models. However, this… 22 r/MachineLearning community 15d ago CoWindow and MassAlloc Attention: collective causal coverage and distribution-adaptive compute [R] I'm one of the authors of two recent papers exploring different sources of redundant computation in attention. I'd like to share the ideas and hear feedback from people working on long-context models and attention kernels. CoWindow Attention (CoWA) distributes distant context… 26 arXiv — Machine Learning research 15d ago Parameters vs. Context: TRACE Fine-Tuning for Robust Retrieval-Augmented Generation arXiv:2609.30337v1 Announce Type: new Abstract: Retrieval-Augmented Generation (RAG) mitigates knowledge obsolescence and factual hallucination in large language models by introducing external context. However, when retrieved knowledge conflicts with the model's internal… 11 arXiv — Machine Learning research 15d ago DanLing NestedTensor: Composable Multi-Ragged Tensors for Deep Learning arXiv:2609.30379v1 Announce Type: new Abstract: Variable-size inputs are common in deep learning, but dense batching allocates a shared envelope and spends computation on padding. The cost multiplies across varying axes: an explicit pair state allocates $BN_{\max}^2$ positions… 12 arXiv — Machine Learning research 15d ago Improving Molecular-Morphology Contrastive Pretraining using Deep-Learning-based Morphology Profiles arXiv:2609.30433v1 Announce Type: new Abstract: Recent advancements in image-based profiling techniques have enabled the collection of high-volume cell morphology data, allowing new molecular embedding models to learn from the experimental phenotypic perturbations of a molecule… 31 arXiv — Machine Learning research 15d ago AutoResearch at Production Scale: Failure Modes and a Multi-Agent Framework arXiv:2609.30541v1 Announce Type: new Abstract: Optimizing embedding systems for production recommendation pipelines demands systematic exploration that consumes disproportionate engineering effort at scale. We apply Andrej Karpathy's AutoResearch paradigm -- a large language… 28 arXiv — Machine Learning research 15d ago GyroNovo: Error-Guided Fragment Imputation with Mass-Aware Attention for \textit{De Novo} Peptide Sequencing arXiv:2609.30542v1 Announce Type: new Abstract: De novo peptide sequencing from tandem mass spectra is essential for identifying peptides without relying on reference databases. Despite advances in deep learning, accurate sequencing remains challenging because experimental… 36 arXiv — Machine Learning research 15d ago Missingness-Aware Conformal Prediction Under Cross-Hospital Distribution Shift arXiv:2609.30781v1 Announce Type: new Abstract: Clinical measurements are recorded for some patients but not others, at rates that differ across hospitals, and marginal conformal coverage does not ensure coverage within groups defined by missingness. We propose a… 18 arXiv — Machine Learning research 15d ago Interpretable-by-Design Descriptor Portfolios Match a 2048-Dimensional Foundation Embedding on Low-Data Molecular Assays arXiv:2609.30789v1 Announce Type: new Abstract: In low-data structure-activity prediction, the choice of molecular representation can matter more than the choice of predictor, and tabular foundation models sharpen that effect. We ask whether a portfolio of compact, semantically… 16 arXiv — Machine Learning research 15d ago Counterfactual Online Conformal Prediction Under Adaptive Logging arXiv:2609.30811v1 Announce Type: new Abstract: Online conformal prediction can fail when predictions shape actions and actions determine which outcomes enter calibration. Standard adaptive methods may retain marginal coverage while systematically miscovering the counterfactual… 9 arXiv — Machine Learning research 15d ago I Act Therefore I Am: When Is JEPA's Action-Conditioning Enough to Learn Causal Mechanisms? arXiv:2609.31161v1 Announce Type: new Abstract: Recent empirical and theoretical advances suggest that joint-embedding predictive architectures (JEPAs) may learn meaningful representations for action-conditioned prediction of future outcomes, thus becoming one of the… 19 MIT News — AI research 15d ago Who we become when we talk to machines Professor Sherry Turkle’s new book, “Artificial Intimacy,” offers a withering critique of chatbots and the antisocial dynamics she believes they encourage. 10 llama.cpp releases dev-tools 16d ago b11240 server : support typed content (vision/audio/video) input for /v1/embeddings endpoint ( #29556 ) server : support multimodal input for /v1/embeddings (Qwen3-VL-Embedding) Accept the OpenAI-style wrapped content array format for multimodal embedding requests. Each {"content":… 10 TechCrunch — AI news-outlet 16d ago Nvidia launches new platform for reining in rogue AI agents As the debate rages over whether the recent spate of rogue AI agents is a step toward AGI or a more conventional engineering problem, Nvidia is offering its own answer to problem. Nvidia CEO Jensen Huang on Monday introduced a toolkit of software and hardware products that add… 37 llama.cpp releases dev-tools 16d ago b11225 tests : fix ggml init ( #29554 ) tests : init ggml for test-recurrent-state-rollback cont : same for test-save-load-state cont : add to test-state-restore-fragmented + add TODOs Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/50700507… 14 arXiv — NLP / Computation & Language research 16d ago SEA-CLIP-Tiny: Efficient Multilingual Text-Vision Embedding for Southeast Asian Languages arXiv:2609.30739v1 Announce Type: new Abstract: Multilingual text-vision embedding models are essential for cross-lingual image-text retrieval, but Southeast Asian languages remain poorly supported due to the region's linguistic diversity and limited data and computing… 10 arXiv — NLP / Computation & Language research 16d ago CG-Probes: Recovering Guardrail Directions from Patient Query Embeddings arXiv:2609.31062v1 Announce Type: new Abstract: Patient-facing AI assistants promise valuable support to patients, but incoming queries can pose medical risks. To create guardrails, we work with oncologists to define three ordinal risk axes: Medical Urgency, Psychological… 32 arXiv — NLP / Computation & Language research 16d ago Stale-Document Poisoning: When Outdated Retrieval Overrides Correct Model Answers arXiv:2609.31342v1 Announce Type: new Abstract: Retrieval-augmented generation (RAG) is often used to address outdated knowledge by providing external evidence. But retrieval helps only when that evidence is still valid. We identify a temporal alignment failure, stale-document… 36 arXiv — NLP / Computation & Language research 16d ago Sorry Robot, Happy Human: Vision-Language Models Read Only One of Two Legible Typographic Layers arXiv:2609.31403v1 Announce Type: new Abstract: Vision-language models (VLMs), despite their success in optical character recognition (OCR) tasks, are vulnerable to typographic attacks and have a fragile structure for images with multiple text layers. In this study, the… 24 arXiv — NLP / Computation & Language research 16d ago RAZOR: Pruning Replaceable Experts in LLMs arXiv:2609.30465v1 Announce Type: cross Abstract: Mixture-of-experts (MoE) models activate few experts per token but store the full expert pool. Expert pruning reduces this storage burden; at a fixed pruning budget, the goal is to preserve the original model's output… 22 arXiv — NLP / Computation & Language research 16d ago Don't CLAP: Are Music-Text Models Bag-of-Words? arXiv:2609.30540v1 Announce Type: cross Abstract: Text-to-music systems are assessed on audio quality and on how faithfully the music follows its prompt, and the CLAP score, the cosine similarity between a music-text model's audio and text embeddings, is the standard objective… 7 Vercel — AI dev-tools 16d ago Search domains without authentication You can now discover domain names and check availability and pricing without signing in to Vercel or providing an access token. This works through the Vercel CLI and Domains Registrar API. With the Vercel CLI , search by keyword or domain fragment: With the Domains Registrar API… 27 r/MachineLearning community 17d ago Two-stage shelf audit: YOLO finds the products, embeddings can't tell sibling SKUS apart. What should Stage 2 be? [P] Help: Project l'm building a shelf audit tool. A photo goes through YOLO, which crops each product, and then I embed the crop and search a small gallery of reference photos to get the SKU. New products should be addable by just dropping in photos, no detector retrain. Detection… 33 Page 4 of 10 · 500 articles ← Newer Older →