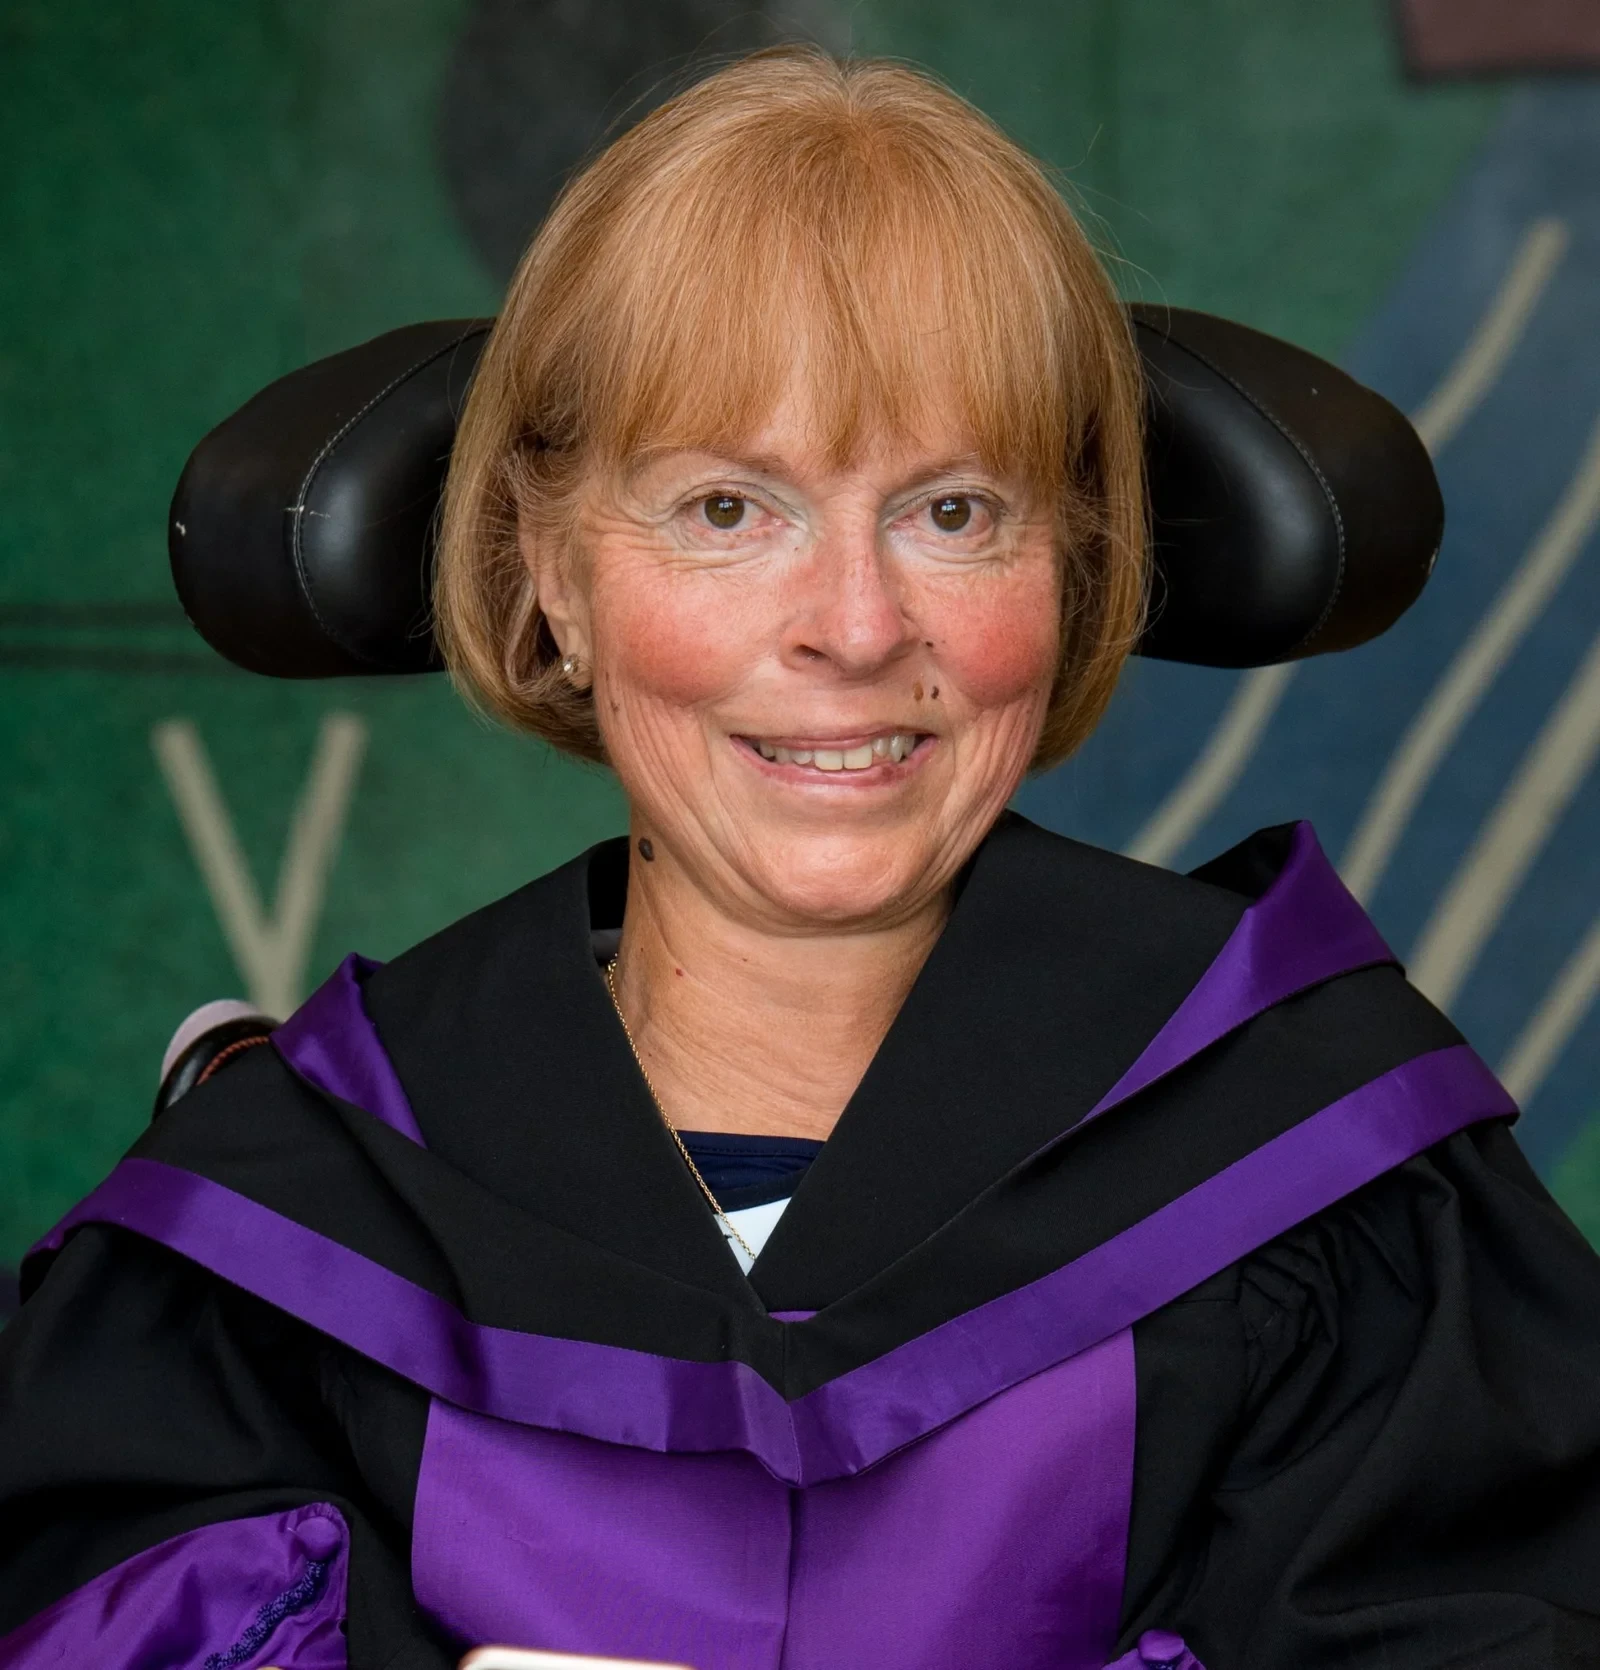
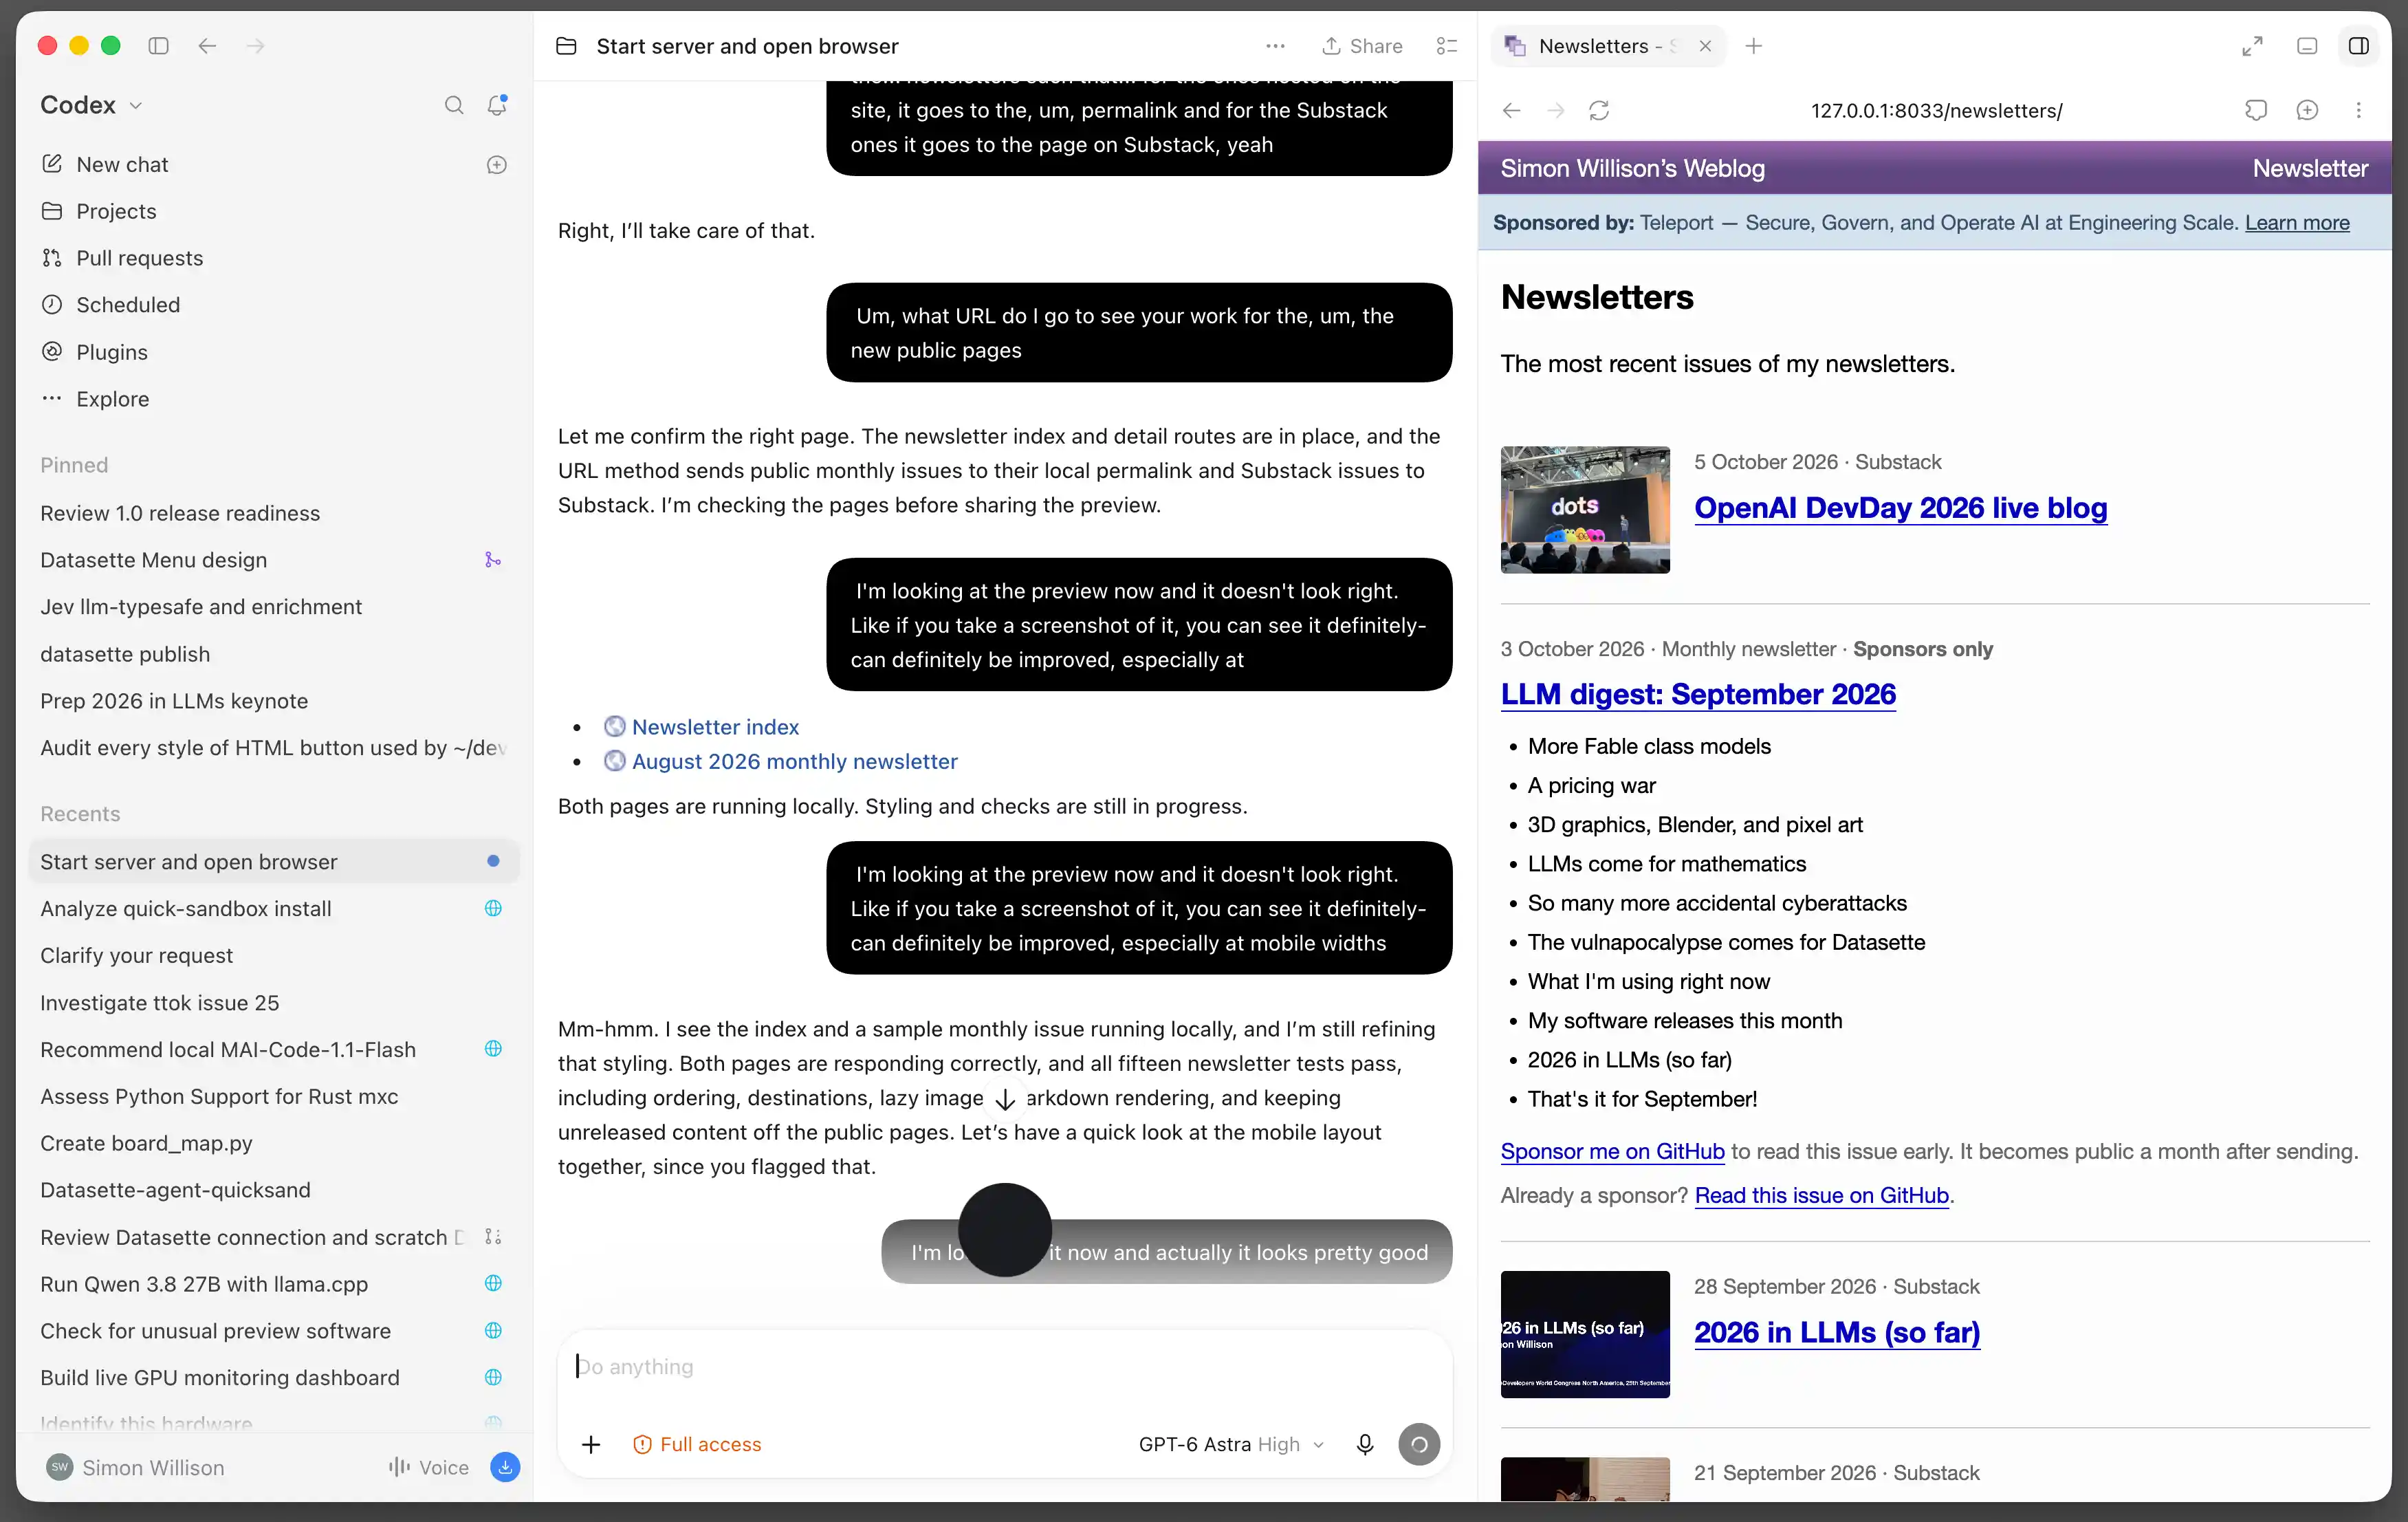
News / #voice Tag Voice 500 articles archived under #voice · RSS Sign in to follow r/LocalLLaMA community 1d ago 4x 6000 Pro for the company Here is how i serve 40 people (10 of them developers) with local AI services. n8n for automatisation whisper and Vexa AI, a bot joins Teams and makes transcripts, n8n later extracts decisions and todos OpenWebUI, ChatGPT-like webinterface for everyone, most agentic features are… 31 ElevenLabs official-blog 1d ago Baroness Campbell gives the UK Parliament’s first ever AI-voiced speech with ElevenLabs Baroness Campbell addressed the House of Lords in her own AI-recreated voice, a first for UK Parliament, built with ElevenLabs. 9 OpenAI official-blog 1d ago Higgsfield takes AI video from 1 minute to over 10 Higgsfield brings creators longer videos with GPT-6 Astra, precise visuals with GPT-Image-2.5, and a path to voice filmmaking with GPT-Live. 7 Vercel — AI dev-tools 1d ago Drama 3 now available on AI Gateway Drama 3 from Fish Audio is now available on AI Gateway, and 80% off for 30 days (through Nov 12). The text-to-speech model is currently in preview and lets you direct voice performances with natural-language instructions in your script, making it useful for voiceovers, character… 35 The Information — AI news-outlet 2d ago Microsoft Debuts New Homegrown AI Chip, Plans to Deploy Multiple Gigawatts Next Year Microsoft on Monday announced the latest generation of its homegrown AI chips, dubbed the Maia 300, and said it plans to set up “multi-gigawatt deployments” of the chip starting next year. The move shows how Microsoft is aiming to reduce its dependence on Nvidia-designed GPUs,… 17 The Information — AI news-outlet 2d ago Microsoft Debuts New Homegrown AI Chip, Plans to Deploy Multiple Gigawatts Next Year Microsoft on Monday announced the latest generation of its homegrown AI chips, dubbed the Maia 300, and said it plans to set up “multi-gigawatt deployments” of the chip starting next year. The move shows how Microsoft is aiming to reduce its dependence on Nvidia-designed GPUs,… 31 ElevenLabs official-blog 2d ago JavaScript speech recognition tutorial: Build voice UX Build live transcription and voice commands with this JavaScript speech recognition tutorial. Learn the Web Speech API and when to switch to ElevenAPI. 27 arXiv — NLP / Computation & Language research 2d ago People Making Conversation: Evaluating How Naturally Speech Models Converse arXiv:2610.12802v1 Announce Type: new Abstract: A conversational speech model has to decide, at every pause, whether to speak. Existing evaluations test boundary detection, policy adherence, or aggregate statistics, not this decision. We place real-time speech systems at 427… 6 arXiv — NLP / Computation & Language research 2d ago From 2.1M Hours of Raw Broadcast Audio to Finnish Speech SSL: Confidence Filtering and Architectural Analysis at Scale arXiv:2610.13102v1 Announce Type: new Abstract: Broadcast archives offer scale and diversity for self-supervised learning (SSL) but contain substantial noisy, non-speech, and multilingual content. Prior work typically relies on voice activity detection or language identification… 9 arXiv — NLP / Computation & Language research 2d ago Personalization Without Stereotyping: Do Speech LLMs Know When to Turn a Deaf Ear? arXiv:2610.13550v1 Announce Type: new Abstract: Recent speech LLMs can leverage rich paralinguistic cues, enabling more complex and personalized interactions. However, little work investigates how this sensitivity can lead to stereotyping, and existing evaluations largely… 18 arXiv — NLP / Computation & Language research 2d ago Error Rate is Not Enough: Costs of Augmentation in Low-Resource ASR arXiv:2610.13807v1 Announce Type: new Abstract: Data augmentation is standard practice for low-resource automatic speech recognition (ASR), but its benefits are almost always reported as aggregate error rates, leaving open why and when a method helps. On four low-resource… 18 OpenAI Python SDK releases dev-tools 3d ago v3.29.0 3.29.0 (2026-10-11) Features api: add billing_not_active session error code ( #4052 ) ( c88b320 ) api: add shida to named Live voices ( #4053 ) ( 7352cf5 ) api: add vault updates and metadata filters ( #4047 ) ( e72f493 ) api: align beta pagination limits and non-null parameters… 11 r/LocalLLaMA community 3d ago Whistle: speech to text in 16.9 MB   submitted by   /u/namanyayg [link]   [comments] 38 TechCrunch — AI news-outlet 3d ago These execs think voice AI hasn’t reached its ChatGPT moment yet Voice AI's often misses important points for its context layer, and causes the whole pipeline to break 10 r/LocalLLaMA community 3d ago Local Voice Assistant based on Qwen3.5 4B with skills/toolcalling. No dedicated GPU. Local STT+TTS STT: Voxtral TTS: Pocket Longer video: https://www.youtube.com/watch?v=1WmvMO-f-24   submitted by   /u/Leading_Yogurt7025 [link]   [comments] 13 r/LocalLLaMA community 4d ago Fully local conversational AI: Whisper + Hermes 8B + Kokoro, zero cloud, running inside a plush toy A conversational AI plush toy where nothing leaves my network. Everything runs on my LAN: STT: Whisper LLM: Hermes 3 Llama 3.1 8B (Q8_0) TTS: Kokoro Memory: per-person (LangGraph). It knows who it's talking to and remembers past conversations Vision: face identity (dlib) +… 18 r/LocalLLaMA community 4d ago SlopSoup TV. A live, never-ending 24/7 pixel-art TV network inspired by old-school late night Adult Swim. No human makes any of it. SlopSoup TV is a live, never-ending pixel-art TV network. Every script, character, voice, camera cut and schedule decision is made by models. It's made to be very absurd, dark and strange. Hardware: one Hugging Face Space, 16 vCPU, no GPU. Everything below runs on CPU next to a… 31 Simon Willison community 5d ago A new feature for my, blog built using my voice I shipped a new feature for my blog today: the Newsletters page, which offers an index of all of the newsletters I've sent out, both my free weekly Substack and my monthly sponsors-only updates. I built the feature almost entirely using my voice, chatting away to my laptop while… 33 ElevenLabs official-blog 5d ago Defining how AI agents interact with your business ElevenLabs joins the Personal Agent Protocol and introduces synthetic voice detection and routing in ElevenAgents. 8 ElevenLabs official-blog 5d ago What is voice activity detection and how does it work? Voice activity detection (VAD) classifies audio frames as speech or silence. Learn how VAD works, how it differs from endpointing, and how to test it 15 arXiv — Machine Learning research 5d ago How Hackable Is Your Speech Quality Metric? A Corrected Protocol, a Benchmark, and What Patching Buys arXiv:2610.10899v1 Announce Type: new Abstract: Speech quality predictors are increasingly used as rewards, yet no agreed measure of their hackability exists. The usual measurement has two flaws. First, the perturbation reaches the predictor through a processing chain -- here a… 31 arXiv — NLP / Computation & Language research 5d ago Disentangling Linguistic and Paralinguistic Information with Routed Sparse Autoencoders arXiv:2610.10865v1 Announce Type: new Abstract: Self-supervised speech encoders contain linguistic and paralinguistic information in a shared, entangled representation space. We combine a TopK sparse autoencoder with route-specific supervision and cross-factor adversaries.… 28 arXiv — NLP / Computation & Language research 5d ago Prompts versus Rules: Auditing and Controlling Speech Naturalness Behaviors in Voice User Simulators arXiv:2610.11015v1 Announce Type: new Abstract: As voice agents gain more popularity commercially, the user simulators used to evaluate the deployed agents are also being developed to include more realistic, variable, and diverse speech naturalness behaviors -- disfluency,… 32 arXiv — NLP / Computation & Language research 5d ago Local Prototype Reconstruction for Text-Compatible Speech-to-LLM Bridge Pretraining arXiv:2610.11159v1 Announce Type: new Abstract: Speech-to-LLM systems often connect a frozen speech encoder to a frozen large language model (LLM) through a small trainable bridge. The bridge is usually treated as plumbing, but it in fact defines the geometry of the… 12 arXiv — NLP / Computation & Language research 5d ago Phonological Interference in Multilingual Speech Models arXiv:2610.11275v1 Announce Type: new Abstract: Phoneme-level models transcribe or generate speech as a sequence of phonemes, the smallest sound units that distinguish words. These models enable fine-grained pronunciation control and understanding, yet often fail on input that… 23 arXiv — NLP / Computation & Language research 5d ago When Can You Prune Your Network? A Study of Intermediate Neurons in Multilingual Speech Parsing arXiv:2610.11520v1 Announce Type: new Abstract: End-to-end speech parsing, a task recently proposed, consists in predicting both the transcription and the syntactic tree for a spoken utterance. Existing architectures for speech parsing often utilise intermediate neural networks.… 18 arXiv — NLP / Computation & Language research 5d ago Prosody-to-Text: Predicting text from low-pass filtered speech arXiv:2610.11544v1 Announce Type: new Abstract: While predicting prosody from text is an established task in the field, the opposite direction, predicting text that fits a given prosodic pattern, remains largely overlooked. We find this unfortunate, because this opposite… 20 arXiv — NLP / Computation & Language research 5d ago Phonologically Informed Tokenization for German Speech Recognition: A Cross-Domain Study arXiv:2610.11646v1 Announce Type: new Abstract: German is a morphologically rich language whose syllable structure is exceptionally well-predicted by the Knuth--Liang hyphenation algorithm. We ask whether phonologically informed tokenization can serve as a competitive target for… 10 arXiv — NLP / Computation & Language research 5d ago EgoVoice: Proactive Spoken Assistance from Egocentric Multimodal Streams arXiv:2610.12248v1 Announce Type: new Abstract: Wearable augmented reality (AR) assistants are moving toward continuous real-world interaction, where they perceive the user's activity through first-person video and audio and provide timely spoken guidance without being… 20 arXiv — NLP / Computation & Language research 5d ago Conversational Voice Aesthetic Model with Reinforcement Learning from Human Listeners arXiv:2610.10868v1 Announce Type: cross Abstract: We introduce Conversational Voice Aesthetic Model, a speech large language model for describing the voice aesthetics of real or synthetic speech responses in natural conversational contexts. Given a context and a response speech,… 4 Hacker News — AI on Front Page community 6d ago Whistle: Speech to Text in 16.9 MB Article URL: https://cactuscompute.com/blog/whistle Comments URL: https://news.ycombinator.com/item?id=50008427 Points: 244 # Comments: 67 36 r/LocalLLaMA community 6d ago OpenAI-compatible TTS endpoint using OmniVoice: 0.3s response time I want to share a TTS server with an OpenAI-compatible API that generates speech really fast (about 0.3 seconds for a sentence on an RTX 3080) and can clone a voice from a short reference clip. I’ve optimized the server so generation starts quickly, and it processes long text in… 16 r/LocalLLaMA community 6d ago [audio.cpp] Recent updates you might have missed: Higgs Audio TTS use 48% less VRAM (< 6GB), HTDemucs 2.2× faster, PocketTTS 2.2× faster on CPU, and WebUI generation history feature Hi all, a bunch of performance improvements have been landed in audio.cpp. The biggest highlight is Higgs Audio TTS, which now runs with around 6 GB VRAM , a 48% reduction in peak memory usage compared to the previous implementation. Thanks to https://github.com/mirek190 We also… 12 ElevenLabs official-blog 6d ago ElevenLabs launches in Singapore ElevenLabs launches in the Singapore, opening an office to bring voice AI to Southeast Asian enterprises. 16 r/LocalLLaMA community 6d ago I trained Turkish TTS from scratch using the Drifting method with an RTX 5090. Github: https://github.com/kadirnar/drifting-tts Demo: https://huggingface.co/spaces/Vyvo/drifting-tts-tr-demo   submitted by   /u/kadir_nar [link]   [comments] 22 OpenAI Python SDK releases dev-tools 6d ago v3.26.1 3.26.1 (2026-10-08) Bug Fixes api: correct custom voice creation parameters ( #4038 ) ( b9bc5c1 ) 30 arXiv — Machine Learning research 6d ago Breaking Adversarial Transferability in Fine-Tuned Speech Recognition arXiv:2610.09109v1 Announce Type: new Abstract: Many organizations fine-tune publicly available pretrained Automatic Speech Recognition (ASR) models and deploy them in black-box settings, assuming limited access provides protection. We show this assumption is fragile:… 31 arXiv — Machine Learning research 6d ago From Retrieval to Customer Context: Evaluating Frontier-Model Systems for Voice-of-Customer Analysis arXiv:2610.09375v1 Announce Type: new Abstract: Organizations increasingly use frontier language models to analyze customer feedback, but answer quality also depends on how that feedback is organized and made available. We define a \emph{customer context graph} as a unified… 32 arXiv — NLP / Computation & Language research 6d ago Child ASR Adaptation with Adult Retention: An Empirical Study arXiv:2610.08827v1 Announce Type: new Abstract: Automatic Speech Recognition (ASR) systems often underperform for children and non-native speakers, while adapting adult ASR models to child speech can cause adult-speech forgetting. We study child ASR adaptation with adult… 18 arXiv — NLP / Computation & Language research 6d ago When Forgetting Looks Like Improvement: Metric Masking in Streaming Diarizer Adaptation and the Price of Rehearsal arXiv:2610.08828v1 Announce Type: new Abstract: Small-data adaptation can improve speech detection while degrading speaker attribution. We study this discrepancy in a released streaming diarizer adapted on 7.5 h of two-party conversation and evaluated across six corpora.… 26 arXiv — NLP / Computation & Language research 6d ago Steering Follows Geometry, Not Labels: Emotion Directions in a Full-Duplex Speech Model arXiv:2610.08887v1 Announce Type: new Abstract: Full-duplex voice agents need to modulate emotion and delivery during real-time conversations, when de-escalating a complaint, carrying urgency in dispatch, softening a clinical result. Emotion and delivery control is well studied… 20 arXiv — NLP / Computation & Language research 6d ago Dialect-Robust Speech Language Models with Synthetic Pseudo-Dialect Augmentation arXiv:2610.09321v1 Announce Type: new Abstract: Speech Language Model (SLM) performance often degrades on dialects due to data scarcity. Conventional text-to-speech (TTS) augmentation struggles to cover diverse dialects as it requires a certain amount of real dialect speech. We… 27 arXiv — NLP / Computation & Language research 6d ago BanglaRhet: Benchmarking Classical and Transformer Models for Rhetorical and Persuasion Detection in Bangla Political Speech arXiv:2610.09464v1 Announce Type: new Abstract: Political discourse often uses rhetorical and persuasive language to frame narratives, influence public opinion, and mobilize audiences. While Bangla natural language processing has made progress in sentiment analysis and opinion… 4 arXiv — NLP / Computation & Language research 6d ago From Pareto to Preference: Personalized Test-Time Scaling via Amortized Agentic Policy Discovery arXiv:2610.09684v1 Announce Type: new Abstract: Test-time scaling (TTS) improves the reasoning capabilities of large language models by allocating additional inference computation. Existing approaches to improving TTS efficiency largely optimize accuracy against one resource… 29 arXiv — NLP / Computation & Language research 6d ago Itgan at NADI 2026 shared task: Parameter-Efficient Whisper Adaptation for Robust, Mixed-Dialect and Code-Switched Arabic ASR arXiv:2610.09934v1 Announce Type: new Abstract: We describe the Itgan systems for the three ASR subtasks of NADI 2026, namely robust country-level ASR (1.1), mixed-dialect ASR (1.2), and Tunisian code-switched ASR (1.3). All three share one recipe, Whisper adapted with LoRA on… 36 arXiv — NLP / Computation & Language research 6d ago EmphTTS: an emphasis-control TTS with reinforcement learning arXiv:2609.27599v2 Announce Type: cross Abstract: Generating controllable and human-like emphasis remains an open challenge in text-to-speech, even when explicit emphasis control signals are provided in the text input, limiting the communicative accuracy of synthetic speech in… 15 arXiv — NLP / Computation & Language research 6d ago Is Word Error Rate Enough? Rethinking Privacy Evaluation in Speech with Entity-Aware Metrics arXiv:2610.08831v1 Announce Type: cross Abstract: As the use of smart devices continues to increase, their potential to capture sensitive speech content raises growing privacy concerns. It is therefore critical to develop techniques that prevent information leakage while… 31 arXiv — NLP / Computation & Language research 6d ago Phoneme-Guided Initialization for LLM-based Speech Recognition arXiv:2610.08994v1 Announce Type: cross Abstract: Speech large language models (speech LLMs) perform well on automatic speech recognition (ASR) when sufficient paired speech-text data is available, but their performance degrades in low-resource settings. A cascaded pipeline that… 24 arXiv — NLP / Computation & Language research 6d ago Boundary-Free Contextual Biasing: Depth-Adaptive Gating and Reading-Space Matching for Unsegmented Languages arXiv:2610.09467v1 Announce Type: cross Abstract: Contextual biasing supplies an ASR system with a list of expected words at inference time, but existing methods rely on word boundaries that Japanese and Chinese do not provide. We present a boundary-free biasing decoder for… 38 arXiv — NLP / Computation & Language research 6d ago Mitigating Accent-Language Confusion in Self-Supervised Speech Representations for Language Identification arXiv:2610.09486v1 Announce Type: cross Abstract: Spoken language identification (LID) aims to recognize the target language regardless of accent. In practice, however, LID models fine-tuned from self-supervised speech representations frequently confuse accents with languages,… 36 Page 1 of 10 · 500 articles Older →