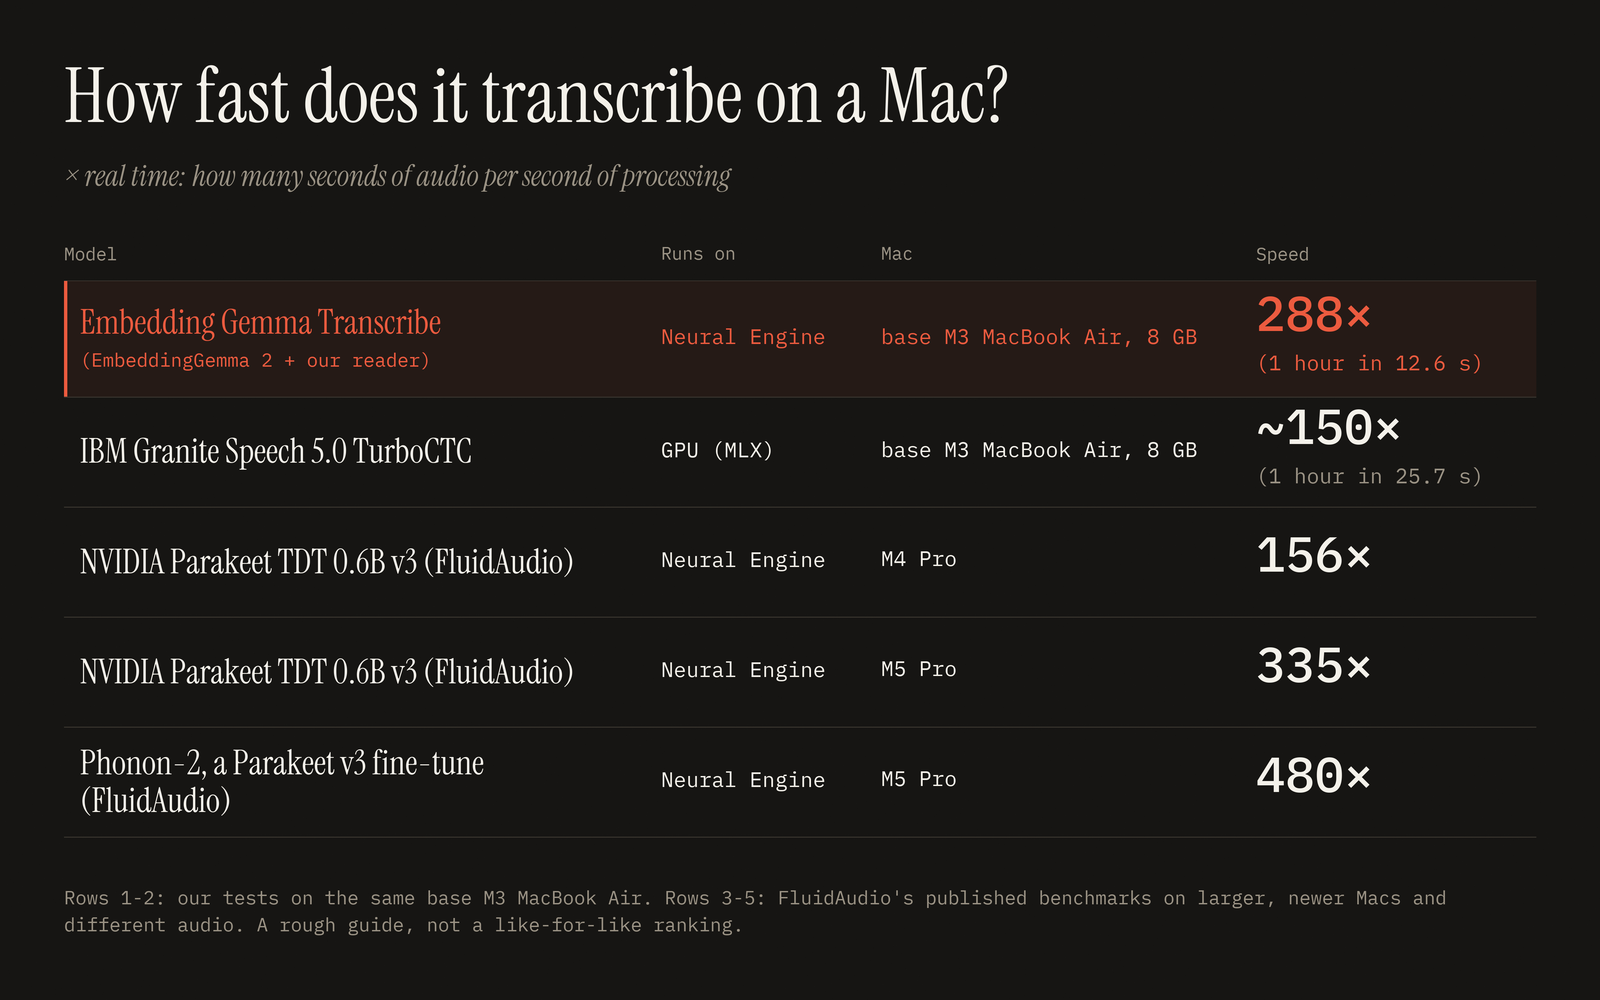
News / #music Tag Music 500 articles archived under #music · RSS Sign in to follow Hacker News — AI on Front Page community 1d ago An hour of audio transcribed in about 13s on MacBook Air Article URL: https://eg2.haku.sh/ Comments URL: https://news.ycombinator.com/item?id=50069971 Points: 232 # Comments: 57 14 Vercel — AI dev-tools 1d ago Drama 3 now available on AI Gateway Drama 3 from Fish Audio is now available on AI Gateway, and 80% off for 30 days (through Nov 12). The text-to-speech model is currently in preview and lets you direct voice performances with natural-language instructions in your script, making it useful for voiceovers, character… 35 r/LocalLLaMA community 2d ago VectorDash: A full Windows search replacement incorporating Embeddinggemma-2 Inspired by DigUp for macOS, VectorDash aims to be a full Windows 11 search replacement, powered by EmbeddingGemma 2 . Full indexing: search by meaning or exact words across photos, screenshots, audio, video, PDFs and Office documents. Find “images of dogs,” a podcast… 23 arXiv — NLP / Computation & Language research 2d ago From 2.1M Hours of Raw Broadcast Audio to Finnish Speech SSL: Confidence Filtering and Architectural Analysis at Scale arXiv:2610.13102v1 Announce Type: new Abstract: Broadcast archives offer scale and diversity for self-supervised learning (SSL) but contain substantial noisy, non-speech, and multilingual content. Prior work typically relies on voice activity detection or language identification… 9 arXiv — NLP / Computation & Language research 2d ago What Do Audio-Language Judges of Generated Music Listen For? Four Probes with Controls from Expert Ratings arXiv:2610.13247v1 Announce Type: cross Abstract: Open audio-language models are used as judges of generated music: given a clip and its text prompt, the model rates the clip, and the judge is validated by how well its ratings correlate with expert ratings. The correlation does… 26 r/LocalLLaMA community 3d ago M5 Ultra Mac 256GB Studio - 64 core vs. 80 core version, is the inference speed difference worth the extra 10 weeks wait time? I’m seeing 6-7 week delivery wait time for M5 Ultra Mac Studio 64 core version versus 15-17 weeks for 80 core version. They both Ultra and have the same memory bandwidth. Is the speed difference that noticeable for prompt processing and token generation? Is it worth the $1200… 38 r/LocalLLaMA community 4d ago Open-source Mac app that runs EmbeddingGemma 2 locally to search your files by what’s in them DigUp is a free Mac app that runs Google DeepMind’s new EmbeddingGemma 2 locally over your own files. The model puts text, images, audio and video in one space, so you describe what you remember and land on it: “zebra in a video” opens the clip at the moment it shows up “where… 10 r/LocalLLaMA community 4d ago Been a while since I posted about my harness OpenLumara.. I only post when a huge new feature releases. I think this is one of them! This is my new meditation module for my harness OpenLumara . It started out as a demonstration of just how powerful its new webui extensions system is, but has grown to be quite the meditation app in its own right. As you will hear in the video, it's a full audiovisual… 29 r/LocalLLaMA community 5d ago tencent/Youtu-Parsing-Omni · Hugging Face Youtu-Parsing-Omni is a compact (5B) omni-modal parsing model. Given a single input — a document page, a natural image, a chart / flowchart, a geometry figure, an audio clip or an audio-visual video — it produces one structured JSON envelope that covers both perception (layout… 36 ElevenLabs official-blog 5d ago What is voice activity detection and how does it work? Voice activity detection (VAD) classifies audio frames as speech or silence. Learn how VAD works, how it differs from endpointing, and how to test it 15 arXiv — Machine Learning research 5d ago Controlled Acquisition and Abstention in Three-Channel Score Conflicts arXiv:2610.10808v1 Announce Type: new Abstract: When audio, video, and text disagree, accuracy alone does not show whether to acquire another source or abstain. We study these choices in a controlled three-score benchmark: a policy observes two signed scores, may request the… 5 arXiv — NLP / Computation & Language research 5d ago EgoVoice: Proactive Spoken Assistance from Egocentric Multimodal Streams arXiv:2610.12248v1 Announce Type: new Abstract: Wearable augmented reality (AR) assistants are moving toward continuous real-world interaction, where they perceive the user's activity through first-person video and audio and provide timely spoken guidance without being… 20 r/LocalLLaMA community 5d ago Qwen3.8-27B: 159 tok/s on R9700, 64 tok/s on Strix Halo LemonSeed Studio is an iPad editor/IDE with on-device inference on an AMD GPU in a Thunderbolt enclosure. It embeds the unmodified upstream Linux amdgpu + amdkfd driver (mac_linuxgpu) as a PCIDriverKit extension, and runs LemonSeed Engine (LSE) on the GPU. In the photos: iPad… 36 r/LocalLLaMA community 6d ago [audio.cpp] Recent updates you might have missed: Higgs Audio TTS use 48% less VRAM (< 6GB), HTDemucs 2.2× faster, PocketTTS 2.2× faster on CPU, and WebUI generation history feature Hi all, a bunch of performance improvements have been landed in audio.cpp. The biggest highlight is Higgs Audio TTS, which now runs with around 6 GB VRAM , a 48% reduction in peak memory usage compared to the previous implementation. Thanks to https://github.com/mirek190 We also… 12 ElevenLabs official-blog 6d ago ElevenReader launches in Brazil with Fábio Porchat and 70,000 Brazilian Portuguese books in audio ElevenReader launches in Brazil, Fábio Porchat joins alongside 70,000 Brazilian Portuguese titles in audio 12 llama.cpp releases dev-tools 6d ago b11488: model : add LiquidAI/d1-omni-600M decision model (#30114) model : add LiquidAI/d1-omni-600M decision model Assisted-by: Claude Opus 5.5 mtmd : keep conformer GLU sigmoid on CUDA Assisted-by: Claude Opus 5.5 server : take d1omni audio through images and input_audio, scope memory-less lfm2 to non-causal Assisted-by: Claude Opus 5.5… 11 Vercel — AI dev-tools 6d ago Grok Imagine Video 1.5 Lite on AI Gateway Grok Imagine Video 1.5 Lite from xAI is now available on AI Gateway. This lightweight model turns text prompts and images into video with native audio. The model produces clips from 1 to 15 seconds long in 480p, 720p, and 1080p. Seven aspect ratios cover widescreen, square, and… 30 TechCrunch — AI news-outlet 7d ago Google’s new SynthID website can identify AI-generated media Google on Tuesday launched a new site that lets anyone verify whether a piece of media, be it an image, a video or an audio clip, is generated using AI. 13 Hacker News — AI on Front Page community 7d ago ETH-68: Ethernet Audio Interface for Linux Article URL: https://naturalsystems.io/eth68 Comments URL: https://news.ycombinator.com/item?id=49992994 Points: 203 # Comments: 129 30 arXiv — NLP / Computation & Language research 7d ago ARIA: Audio-Driven Melody-Tone Relation Modeling for Cantonese Lyric Authoring arXiv:2610.07902v1 Announce Type: new Abstract: Cantonese lyric writing requires close alignment between lexical tones and melodic pitch. Existing melody-guided lyric generation methods typically rely on symbolic melody to generate lyrics. However, in real songwriting scenarios,… 37 arXiv — NLP / Computation & Language research 7d ago Logbook: Extremely Long-form Audio Event Understanding arXiv:2610.07338v1 Announce Type: cross Abstract: Audio benchmarks are built around short, pre-segmented clips, limiting model design to brief inputs or fixed vocabularies. To close this gap, we introduce Logbook, a benchmark for hour-scale audio understanding, with recordings… 16 r/LocalLLaMA community 7d ago Ruach Studio: a whole song studio around YuE2 on your own GPU. Score first, LoRA training, stems,remaster, DAW export. We spent the last weeks building a studio around YuE2 , the open song model by m-a-p, and today it reaches its first release candidate. Write the style and the lyrics, and it composes, sings and renders the song on your own card. Nothing leaves your machine unless you point the… 23 Google DeepMind official-blog 8d ago EmbeddingGemma 2: an open, lightweight multimodal embedding model EmbeddingGemma 2: an open, lightweight multimodal embedding model Oct 06, 2026 | x.com Facebook LinkedIn Mail EmbeddingGemma 2 is the most capable model for on-device multimodal embeddings, natively mapping combinations of text, images, audio, and video into a unified embedding… 4 r/LocalLLaMA community 8d ago Aplomb 1: open-weights 5.3B decision model, 1M context, text/image/video/audio in one request, #1 among 4B models on the Decision Index We released Aplomb 1 today, a 5.3B decision model with open weights. It reads up to 1M tokens of text, JSON, images, video and audio in a single request, and on our API it makes a decision on a 1M-token document in about 3 seconds, at $0.02 per 1M input tokens with free output… 36 r/LocalLLaMA community 8d ago Introducing EmbeddingGemma 2: A best-in-class open model for natively multimodal embeddings | Google https://huggingface.co/google/embeddinggemma-2 EmbeddingGemma 2 is an open multimodal embedding model built by Google DeepMind which maps text (incl. code), images, video, and audio inputs—and combinations thereof—into a single, unified 768-dimensional vector space. The model… 9 llama.cpp releases dev-tools 8d ago b11452 model: support embeddinggemma2 (text+vision+audio) ( #30054 ) 4 r/LocalLLaMA community 8d ago google/embeddinggemma-2 · Hugging Face EmbeddingGemma 2 is an open multimodal embedding model built by Google DeepMind which maps text (incl. code), images, video, and audio inputs—and combinations thereof—into a single, unified 768-dimensional vector space. The model has 740M total parameters, combining a 270M… 18 The Information — AI news-outlet 8d ago Ellison-Controlled Skydance Completes Warner Bros. Discovery Acquisition The Ellison family’s Paramount Skydance completed its $110 billion purchase of Warner Bros. Discovery, Paramount said Tuesday morning, creating a new company to be called Skydance. The combined company owns both the Warner Bros. and Paramount film studios, the HBO Max and… 5 ElevenLabs official-blog 9d ago How does audio transcription with timestamps and event tagging work? Learn how audio transcription with timestamps works, from word-level timing to audio event tags like laughter, and how it differs from forced alignment. 22 arXiv — Machine Learning research 9d ago OpenGameEval: Benchmarking Agentic Programming and Exploration in a Stateful Game Engine arXiv:2610.02563v1 Announce Type: new Abstract: We present OpenGameEval, a benchmark and evaluation framework for agentic game development inside Roblox Studio. It runs language models as agents in reproducible, stateful game-engine sessions and scores each run with executable… 8 arXiv — NLP / Computation & Language research 9d ago Text-Centric Post-Training for Omni-Modal Reasoning arXiv:2610.02819v1 Announce Type: new Abstract: Improving joint audio-visual reasoning in Omni Large Language Models typically incurs substantial data construction and training costs. Our diagnostics reveal multi-hop reasoning difficulties despite correct answers to all… 26 arXiv — NLP / Computation & Language research 9d ago OmniConfess: Eliciting Token Confessions to Mitigate Omni-Modal Hallucination arXiv:2610.02999v1 Announce Type: new Abstract: Omni-modal large language models (OmniLLMs) unify text, images, audio, and video, yet hallucinate when generation relies on the wrong evidence. Existing inference-time methods can reduce hallucinations, but rarely reveal which… 29 r/LocalLLaMA community 9d ago My qwen model hallucinated a signed URL to Alibaba cloud, normal or sketchy? I'm using Qwen3.8-Flash-Next running on my Mac Studio as a daily driver for coding + productivity tasks, and yesterday it did something weird: I had it do some product research on amazon, so it was doing a lot of Web tool calls to amazon.com , until it made one request to… 34 The Information — AI news-outlet 9d ago The Ellisons’ Hollywood Adventure Is About to Scale Up This is a big week for Larry Ellison. His family’s yearlong pursuit of Warner Bros. Discovery, owner of one of Hollywood’s most iconic film studios, comes to a conclusion on Tuesday when the Ellison-controlled Paramount Skydance is scheduled to complete the $110 billion purchase… 36 Hacker News — AI on Front Page community 10d ago In the wake of Tippett Studios’ closure, a digital archive appears online https://archive.org/details/tippett-archive/ Comments URL: https://news.ycombinator.com/item?id=49957812 Points: 236 # Comments: 30 29 r/LocalLLaMA community 10d ago Optimal settings for 2 GPUs in LM Studio Hello everybody. I've got a 5070ti and a 5060ti both 16GB in my system which is a 5900X and 64GB DDR4 RAM. I'm trying to run some 16-18GB models like Qwen, Cydonia, Skyfall. I'm having problems utilising the VRAM I have to get the best usage out of it. LM Studio sees the 32GB… 8 r/LocalLLaMA community 11d ago Two local Qwen ( 3.8 27b unsloth Q6 and Qwen flash next strata coder ) models vs Claude Opus 4.6 on the same 3 coding tasks. One of them tied it. Not here to start a fight, just sharing numbers Innanzitutto, due cose per evitare fraintendimenti. Non sto cercando di sostenere che un modello o un'azienda siano migliori. Non ho alcun interesse personale in nessuno di essi. Volevo solo verificare personalmente come si comportano nello stesso contesto lavorativo. E il… 19 ElevenLabs official-blog 12d ago How to add pauses in AI voiceover with Eleven v4 Learn three ways to control pauses in AI voiceover with Eleven v4: the [pause] and [long pause] Audio Tags, and punctuation. Includes audio examples. 5 arXiv — Machine Learning research 12d ago Role-guided Speaker Deletion Verification in Clinical Psychiatry Speech Recordings with Audio Language Models arXiv:2609.38491v1 Announce Type: new Abstract: Clinical research in psychiatry increasingly relies on large scale collection of spoken language data to identify acoustic and linguistic biomarkers. Yet evolving consent and protocol requirements can oblige investigators to remove… 27 arXiv — NLP / Computation & Language research 13d ago TutlAit v1: a crowdsourced Moroccan Tamazight speech dataset with Arabic transcriptions and regional accent labels arXiv:2609.38219v1 Announce Type: new Abstract: Tamazight (Amazigh) is, together with Arabic, one of the two official languages of Morocco, yet it remains severely under-resourced for speech technology: pub licly available labelled audio is scarce, generally lacks information on… 26 arXiv — NLP / Computation & Language research 13d ago Fairness Beyond a Single Run: Training-Seed Variability in Speech LLM Adaptation arXiv:2609.38976v1 Announce Type: new Abstract: Demographic fairness gaps in automatic speech recognition are almost always reported from a single training run. We fine-tune the Q-former projector and LoRA adapters of a speech LLM at five audio compression factors and six random… 21 arXiv — NLP / Computation & Language research 13d ago LEAP: Learned Block-wise Evidence Retrieval for Long Audio-Video Perception arXiv:2609.39938v1 Announce Type: new Abstract: Hour-scale audio-visual question answering is constrained by a context dilemma: dense whole-recording encoding rapidly exhausts context limits, whereas uniform temporal compression severely dilutes fine-grained acoustic and visual… 28 r/LocalLLaMA community 13d ago Open source inference engine (like LM Studio or Unsloth Desktop) that optimizes itself for your exact hardware. Compiles and tunes its kernels on your device, so open models run up to 2x faster than llama.cpp. Works on Apple Silicon, NVIDIA, AMD or nothing but a CPU.   submitted by   /u/paranoidray [link]   [comments] 34 r/MachineLearning community 14d ago Qwen-family LLMs are quietly becoming the backbone of modern audio models; One chart for the architectures of 100+ audio models [R] I started mapping the building blocks shared across all the models in audio.cpp. The result ended up being more interesting than I expected. Qwen has become by far the most common language backbone in this collection: 32 audio model families use a Qwen-family architecture, and… 10 ElevenLabs official-blog 14d ago The Eleven v4 Audio Tags list: Try them, then write your own Browse the ElevenLabs Audio Tags list for Eleven v4, from emotions to sound effects, and learn to write your own tags with natural language in the TTS app. 16 r/LocalLLaMA community 14d ago Thank You, Mradermacher. best iq quants in the biz, got me gemma 4 26b to run 75tok/s tg and 1500 pp on 2x 4060 8gb using lmstudio serving to hermes, much work has been done.   submitted by   /u/Spiritual_Impress_30 [link]   [comments] 24 r/LocalLLaMA community 14d ago Qwen-family LLMs are quietly becoming the backbone of modern audio models; One chart for the architectures of 100+ audio models I started mapping the building blocks shared across all the models in audio.cpp. The result ended up being more interesting than I expected. Qwen has become by far the most common language backbone in this collection: 32 audio model families use a Qwen-family architecture, and… 22 arXiv — Machine Learning research 15d ago Reliability-aware Cross-sample Enhancement for Robust Multimodal Sentiment Analysis arXiv:2609.30470v1 Announce Type: new Abstract: Multimodal Sentiment Analysis (MSA) aims to infer human emotions from multiple modalities such as text, audio, and vision. In practice, inputs are often corrupted by noise and missing modalities, which degrades performance.… 20 arXiv — Machine Learning research 15d ago Attention-Based Adaptive Policies for Simultaneous Speech-to-Text Translation arXiv:2609.30839v1 Announce Type: new Abstract: Simultaneous speech-to-text translation (Simul-S2TT) consists of generating partial translations while the incoming audio frames are processed by the system. However, the streaming nature of this setup creates the challenge of… 16 arXiv — Machine Learning research 15d ago Audio emotion recognition for atypical hearing arXiv:2609.31168v1 Announce Type: new Abstract: My doctoral work aims to explore Audio Emotion Recognition (AER) in the context of atypical listening. This research focuses on auditory hypersensitivity in people with autism, a phenomenon that is often difficult to evaluate and… 8 Page 1 of 10 · 500 articles Older →