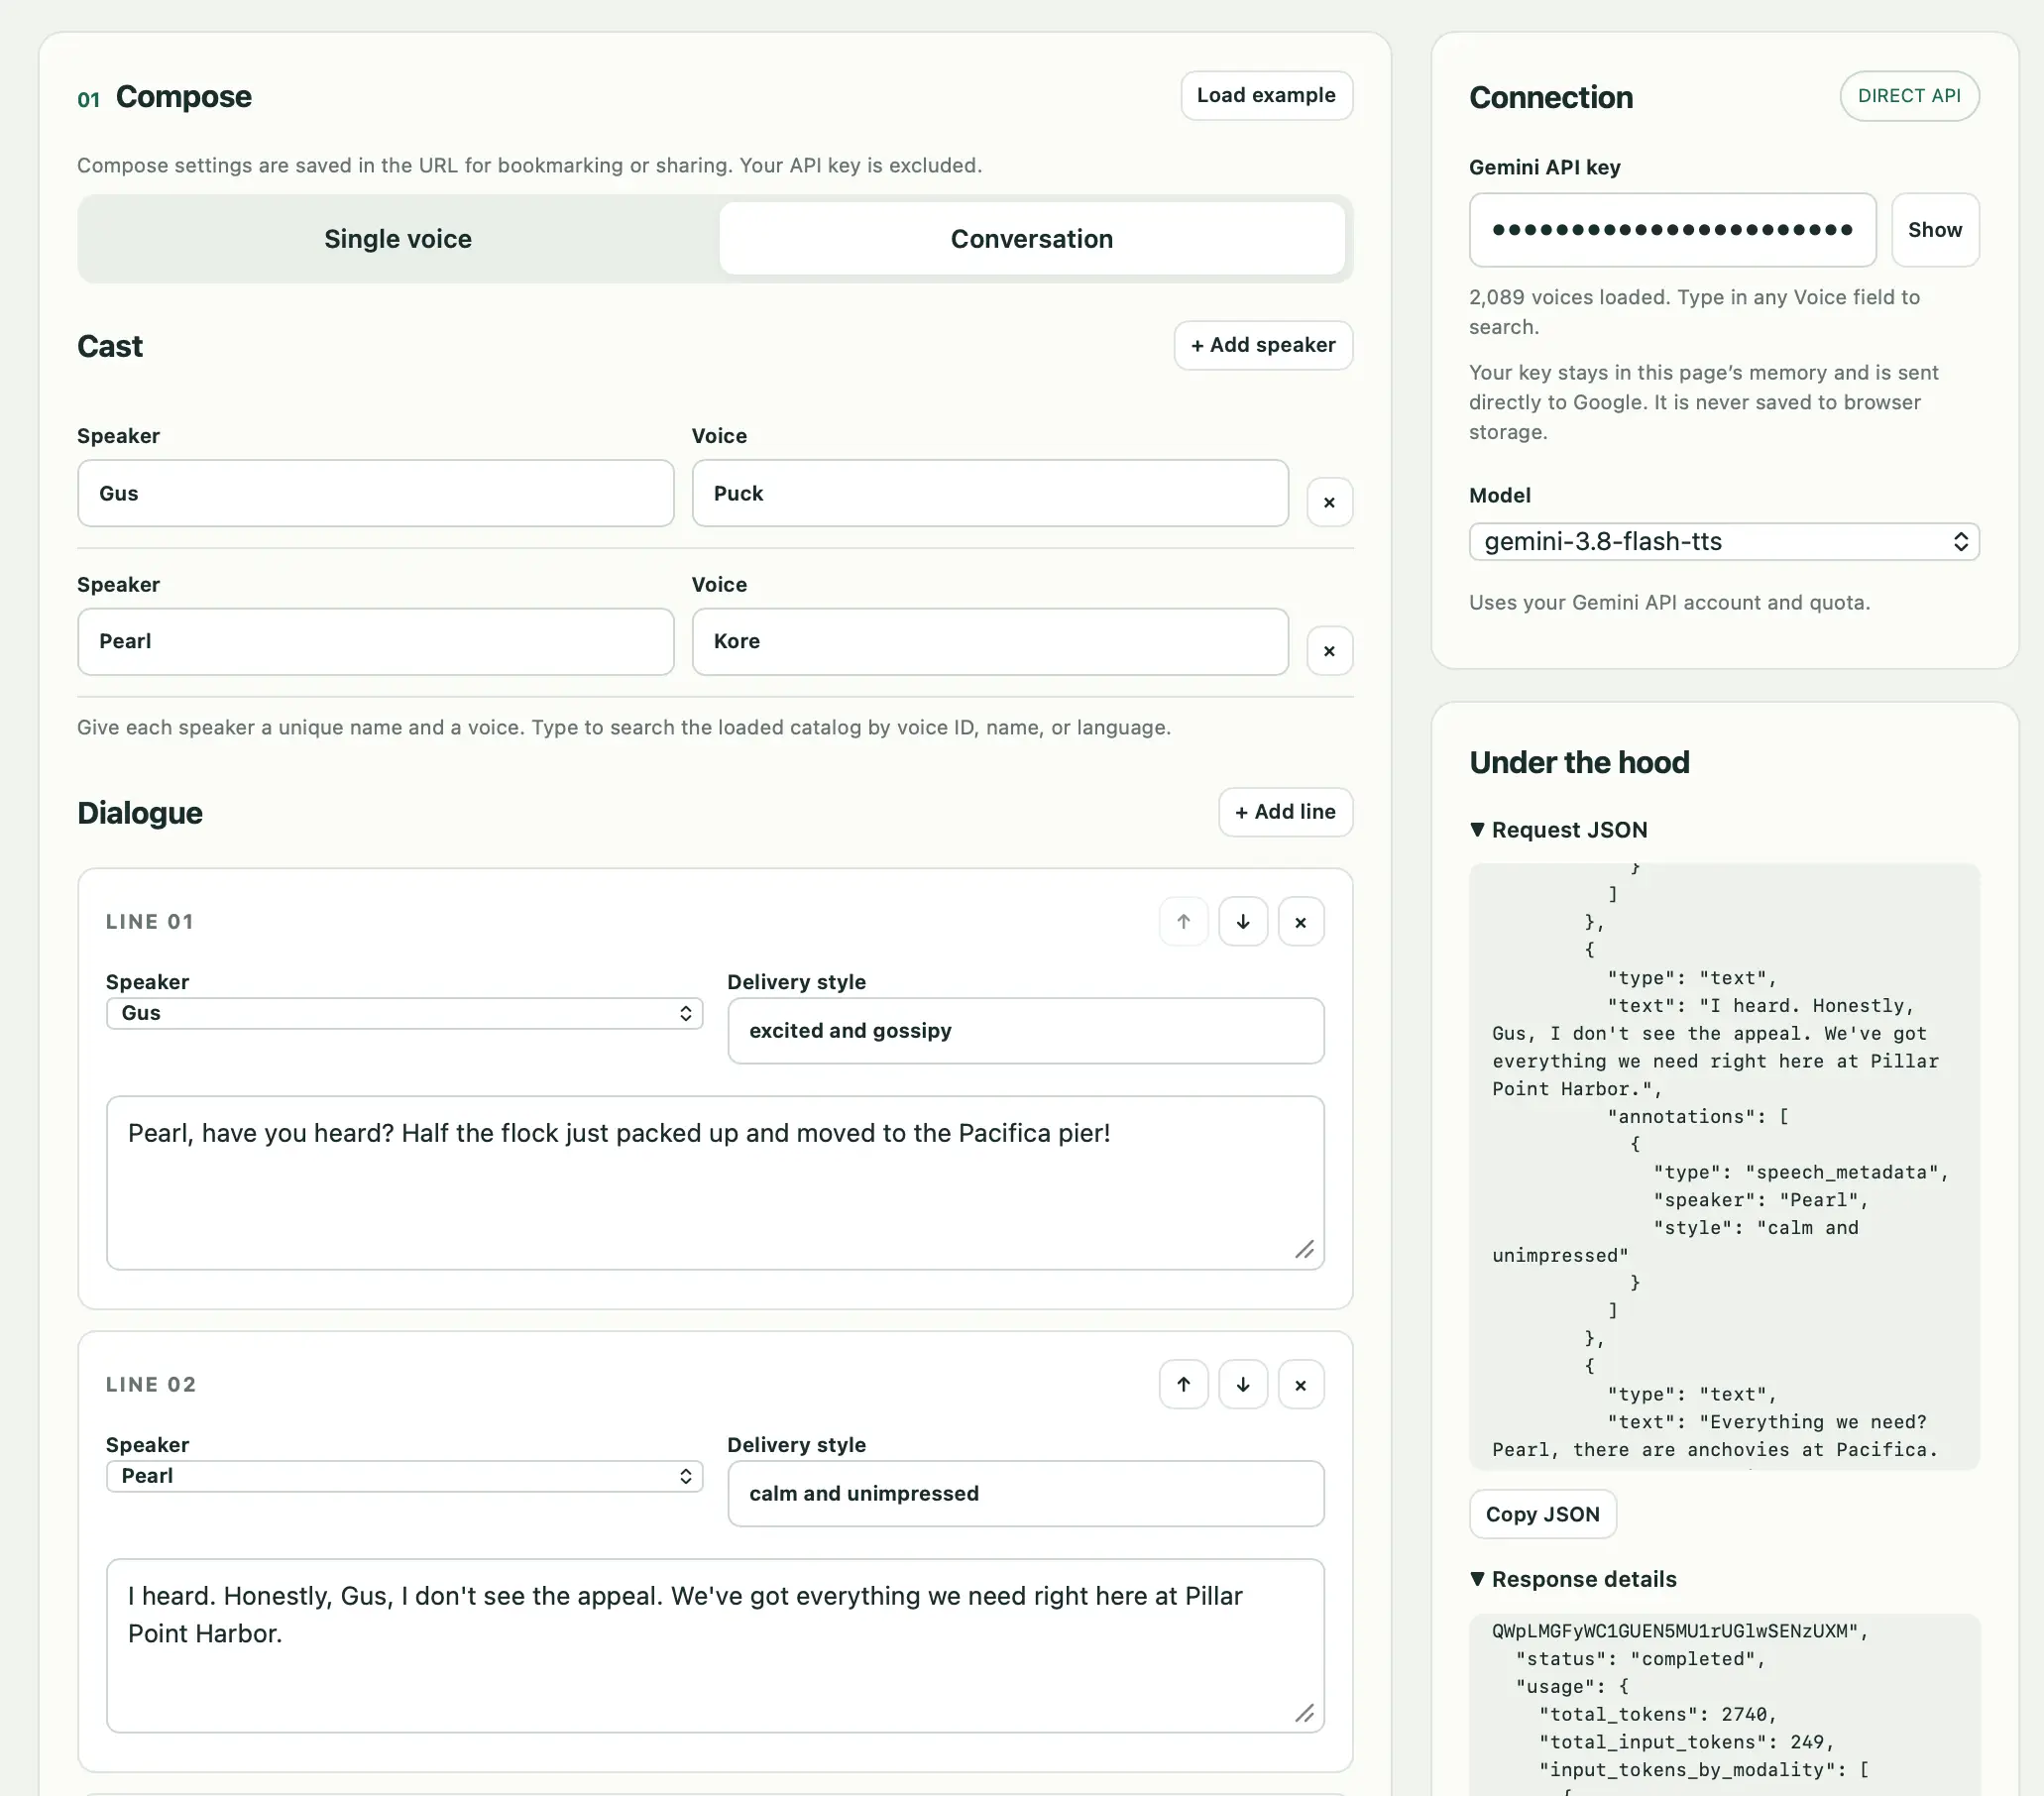
News / #voice Tag Voice 500 articles archived under #voice · RSS Sign in to follow arXiv — NLP / Computation & Language research 20d ago NADI 2026: The Second Multidialectal Arabic Speech Processing Shared Task arXiv:2609.27086v1 Announce Type: new Abstract: NADI 2026 is the seventh edition of the Nuanced Arabic Dialect Identification (NADI) shared task series and the second dedicated to multidialectal Arabic speech processing. This edition comprises five tasks and eight subtasks… 23 arXiv — NLP / Computation & Language research 20d ago Phonemizing User-Generated Text: A Benchmark, Taxonomy, and Compositional Approach arXiv:2609.27205v1 Announce Type: new Abstract: Text-to-speech systems increasingly process user-generated text (UGT) such as ppl and imo, whose pronunciation must be inferred from the canonical rather than surface form. We introduce UGTPhon, the first grapheme-to-phoneme (G2P)… 17 arXiv — NLP / Computation & Language research 20d ago Ruby-ASR: Evidence-Preserving Supervision for Joint Orthographic and Lexical-Reading Recognition arXiv:2609.27289v1 Announce Type: new Abstract: Conventional Japanese automatic speech recognition (ASR) is supervised by an orthographic transcript, although the same written form can correspond to different lexical readings realized in speech. Such utterances receive an… 38 arXiv — NLP / Computation & Language research 20d ago Brain-to-Language Decoding: Tasks, Signals, Methods, Evaluation, Practical Use and Beyond arXiv:2609.27650v1 Announce Type: new Abstract: Brain-to-language decoding translates neural activity associated with language production, internal speech and perception into linguistic or expressive outputs. It offers a route to restoring communication after speech loss and a… 25 arXiv — NLP / Computation & Language research 20d ago Six Layers Less: Encoder Pruning for Whisper with Label-Free Recovery arXiv:2609.27980v1 Announce Type: new Abstract: Pruning large pre-trained transformer-based ASR models such as OpenAI's Whisper has seen great adoption, as pruning the decoder led to significant end-to-end transcription speedups. For instance, the {\tt whisper-large-v3-turbo}… 32 arXiv — NLP / Computation & Language research 20d ago A Native-Reference Coordinate Geometry for L2 Pronunciation Deviation Using Self-Supervised Speech Models arXiv:2609.28060v1 Announce Type: new Abstract: Self-supervised speech models encode rich phonetic information, but it remains unclear how to transform this information into interpretable metrics for second-language (L2) pronunciation assessment in spontaneous speech. We propose… 34 arXiv — NLP / Computation & Language research 20d ago Text Scores Can Miss Waveform Use: A Qwen2-Audio Quantization Case Study arXiv:2609.26823v1 Announce Type: cross Abstract: Post-training quantization of speech language models is often summarized with text-output scores and nominal bit widths. Those numbers alone do not establish behavior that depends on information missing from a transcript, or… 38 arXiv — NLP / Computation & Language research 20d ago Quieter Than the Room: Representation Drift and Task Robustness in Speech Encoders arXiv:2609.27195v1 Announce Type: cross Abstract: Non-speech interference can change a speech representation without causing comparable task loss. We test eight frozen encoders on four tasks, adding non-speech sounds throughout recordings, during speech, or in pauses. Under… 16 arXiv — NLP / Computation & Language research 20d ago Psychoacoustically Aligned Latent Smoothing for Adversarial Robustness of Full-Duplex Speech-to-Speech Dialogue Models arXiv:2609.27378v1 Announce Type: cross Abstract: End-to-end speech-to-speech dialogue models listen and speak simultaneously, so a continuously open acoustic channel is exposed to adversarial manipulation. We formalize imperceptible attacks on full-duplex agents as optimization… 22 arXiv — NLP / Computation & Language research 20d ago When Entanglement Lower-Bounds Disparity: Auditing and Repairing Demographic Fairness in Audio Understanding Models arXiv:2609.27382v1 Announce Type: cross Abstract: Speech technology penalizes some voices: recognition errs nearly twice as often for Black speakers, and accuracy declines for second-language accents and older speakers. We introduce TRIAD, an audit grid crossing 120 texts, 24… 8 Simon Willison community 21d ago Gemini 3.8 TTS Playground Tool: Gemini 3.8 TTS Playground Google released two new Gemini text-to-speech models today - gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts . They come with a library of over 2,000 voices, plus the ability to create a custom voice with "just a 30-second audio sample of your… 16 TechCrunch — AI news-outlet 21d ago ChatGPT mobile app gets voice-based agentic features Pro and Plus users will be able to use the Work tab on their phones to complete agentic tasks. 14 Hacker News — AI on Front Page community 21d ago Gemini 3.8 text-to-speech Article URL: https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-8-text-to-speech/ Comments URL: https://news.ycombinator.com/item?id=49817615 Points: 214 # Comments: 111 35 Google DeepMind official-blog 21d ago Gemini 3.8 text-to-speech says hello Gemini 3.8 text-to-speech says hello Sep 23, 2026 | x.com Facebook LinkedIn Mail Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS are our most expressive audio generation models yet. Generate custom character voices and direct scene dialogue across Google AI Studio, Gemini… 26 r/LocalLLaMA community 21d ago Streaming Nemotron 3 Diarization I’ve been playing with Nemotron 3 Diarization , and it fills a gap I’ve had with local voice agents: keeping track of who is speaking. It’s a diarization model, so it gives you speaker labels rather than transcriptions or people’s names. It can stream its output and track up to… 4 ElevenLabs official-blog 21d ago Python speech recognition tutorial: From audio file to transcript Explore speech-to-text API integration in this Python speech recognition tutorial. Transcribe with advanced voice models without coding from scratch. 27 arXiv — NLP / Computation & Language research 21d ago "As a Language Model...": Chat Template Switches LLM Self-Referential Voice and Activation Steering Reproduces It arXiv:2609.25021v1 Announce Type: cross Abstract: Large Language Models (LLMs) tend to add disclaimers like "I'm just an AI" when asked about something related to themselves. The self-reports from such responses are used in debates about AI safety or self-knowledge of the… 21 arXiv — Machine Learning research 21d ago A Practical Recipe for Semi-Supervised Federated ASR: Online Pseudo-Labels with Server Update Stabilization arXiv:2609.25471v1 Announce Type: new Abstract: Semi-supervised federated learning (SSFL) trains models on clients' unlabeled data using a teacher to generate pseudo-labels, with a small labeled seed dataset on the server. Automatic Speech Recognition (ASR) is particularly… 36 arXiv — NLP / Computation & Language research 21d ago Rethinking Length-Based Training: Batch Composition and Loss Normalization in Speech Token Language Models arXiv:2609.25890v1 Announce Type: new Abstract: Short-to-long training is a simple curriculum for speech models, but its gains can be difficult to interpret. In speech token language models, length-based training can change the shuffle policy, batch composition, token retention,… 6 arXiv — NLP / Computation & Language research 21d ago Enriching Speech Emotion Representations with Conversational Context arXiv:2609.26422v1 Announce Type: new Abstract: Detecting emotions is necessary for building systems that can accurately and adaptively interact with humans. Speech Emotion Recognition (SER) has become an important research focus to develop intelligent spoken interfaces.… 15 arXiv — NLP / Computation & Language research 21d ago Transcribe, Translate, and Optimize: Joint Reward Learning for Speech Translation arXiv:2609.26536v1 Announce Type: new Abstract: In LLM-based speech translation, transcription-based chain-of-thought (CoT) suffers from a mismatch between reference transcripts used in supervised fine-tuning (SFT) and model-generated transcripts at inference. To address this,… 24 arXiv — NLP / Computation & Language research 21d ago Qwen-Audio-3.1-Realtime: Towards Reliable Agentic Voice Interaction arXiv:2609.25176v1 Announce Type: cross Abstract: Real-time voice assistants must reason over evolving requests, execute actions, and follow conversational rules. Qwen-Audio-3.1-Realtime brings these requirements together through Think, Act, and Speak and Coordinate. Think… 9 arXiv — NLP / Computation & Language research 21d ago Challenges of Multi-Speaker Extraction for Real Conversational Speech Enhancement arXiv:2609.25948v1 Announce Type: cross Abstract: Target-speaker and multi-speaker extraction are techniques for extracting speech from a desired speaker or desired speakers in the presence of other speakers and/or noise. Neural network approaches for this task are often trained… 25 Vercel — AI dev-tools 21d ago Gemini 3.8 text-to-speech models now available on AI Gateway Gemini 3.8 Flash-Lite TTS and Gemini 3.8 Flash TTS from Google are now available on AI Gateway . Both models take text and generate speech in more than 100 languages. They support long-form narration, control over delivery, and two-speaker dialogue.… 20 ElevenLabs official-blog 22d ago Scribe v2 Medical is now available to everyone Scribe v2 Medical, our speech to text model fine-tuned for clinical audio, is now generally available on the ElevenLabs API. 22 arXiv — NLP / Computation & Language research 22d ago The Bairong System for MLC-SLM 2026: Dynamic Question-Aware Evidence Routing for Multilingual Conversational Speech Understanding arXiv:2609.22214v1 Announce Type: new Abstract: Long multilingual conversational spoken question answering requires systems to balance long-range transcript semantics with sparse acoustic and speaker-sensitive cues. We present the Bairong system for the MLC-SLM 2026 Challenge,… 9 arXiv — NLP / Computation & Language research 22d ago Used, Mentioned, or Condemned? A Controlled Contrast-Set Diagnostic for the Use-Mention Distinction in Code-Mixed Hinglish Misogyny Detection arXiv:2609.22261v1 Announce Type: new Abstract: Lexicon-driven misogyny detectors cannot, by construction, distinguish a slur used against a woman from the same slur mentioned in counter-speech ("don't call her that") -- yet exactly this distinction governs whether moderation… 30 arXiv — NLP / Computation & Language research 22d ago Vox-Infinity: Benchmarking the Limits of Long-Context Spoken Language Models arXiv:2609.22452v1 Announce Type: new Abstract: Long-context understanding remains a fundamental challenge for large language models, as excessively long inputs often lead models to forget salient information. This issue is even more pronounced in the speech domain, where audio,… 33 arXiv — NLP / Computation & Language research 22d ago COT-TTS: Audio Context-Aware Text-to-Speech with Chain-of-Thought Reasoning arXiv:2609.22697v1 Announce Type: new Abstract: Recently, text-to-speech systems have made significant progress in speech expressiveness and controllability. However, the speaking style of generated speech typically relies on clear user-specified instructions. In natural… 7 r/LocalLLaMA community 23d ago XiaomiMiMo/MiMo-V2.6-Distill-Qwen-9B we're so back?!?   submitted by   /u/VoiceApprehensive893 [link]   [comments] 24 MIT Technology Review — AI news-outlet 23d ago She died at the San Diego border. A surveillance camera was in plain sight She had only walked for a couple of hours, and already she was lost.  It was early afternoon on Sept. 14, 2025, when 30-year-old Graciela Gómez Hernández crossed the border from the eastern edge of Tijuana into Southern California, sending voice messages to her mother and… 38 ElevenLabs official-blog 23d ago Webinar Recap: Build Full Campaigns With AI Building a full creative campaign: from a product photo to a finished vertical video, using AI voice, music, image, and video models in one workspace. 30 ElevenLabs official-blog 23d ago Introducing Studio 4.0 in ElevenCreative Studio 4.0 generates video, voice, music, and sound effects inside your project, then lets you edit, caption, and export without leaving the editor. 23 arXiv — Machine Learning research 23d ago Talk to Me, Jarvis: An Open-Source Edge-Deployable Voice Assistant Framework for Autonomous Racecars arXiv:2609.21109v1 Announce Type: new Abstract: Recent advances in large language models have improved their effectiveness as back-end components for voice assistants, particularly in intent understanding and context-aware input classification. However, online-hosted models… 13 arXiv — Machine Learning research 23d ago Multi-Subject Pretraining Enables Short-Calibration Personalization for Closed-Corpus Surface EMG Speech Decoding arXiv:2609.21288v1 Announce Type: new Abstract: Surface electromyography (sEMG)-based silent speech interfaces are limited by cross-user variability and calibration burden. We study a limited-data setting in which each of 27 speech-typical participants contributed less than 0.5… 5 arXiv — NLP / Computation & Language research 23d ago Beyond WER: Entity and Disfluency Recall in Accented Conversational ASR arXiv:2609.20828v1 Announce Type: new Abstract: ASR systems optimised for Word Error Rate (WER) often miss named entities and filled pauses in accented conversational English, both critical for language-learning feedback. We present a three-stage pipeline for speakers from… 13 arXiv — NLP / Computation & Language research 23d ago Transsion's Speaker-Attributed Multilingual ASR System for the MLC-SLM 2026 Challenge arXiv:2609.20833v1 Announce Type: new Abstract: This paper presents the Transsion Speech Team submission to Task 1 of the MLC-SLM 2026 Challenge, which focuses on speaker-attributed transcription for multilingual conversational speech. We propose a cascaded framework consisting… 25 arXiv — NLP / Computation & Language research 23d ago Curriculum-Based Noise Adaptation for Phoneme-to-Text Reconstruction in Visual Speech Recognition arXiv:2609.20839v1 Announce Type: new Abstract: Phoneme-centric visual speech recognition reconstructs sentences from intermediate phoneme predictions, making overall recognition performance highly dependent on the robustness of the phoneme-to-text reconstruction model. Existing… 23 arXiv — NLP / Computation & Language research 23d ago Omni Demand Understanding: A Benchmark for Contextual User-Intent Inference in Multimodal Interaction arXiv:2609.21392v1 Announce Type: new Abstract: Natural audio-visual interaction is emerging as an important interface for AI assistants, allowing users to communicate through speech and vision rather than carefully composed text prompts. However, existing benchmarks of… 28 arXiv — NLP / Computation & Language research 23d ago Rethinking Human-Aligned Evaluation: An Analysis of Semantic Metrics Beyond WER arXiv:2609.21663v1 Announce Type: new Abstract: Word Error Rate (WER), the most commonly used metric for Automatic Speech Recognition (ASR), treats every lexical deviation from the reference as equally costly, regardless of whether it changes meaning. This raises the question:… 11 arXiv — NLP / Computation & Language research 23d ago Per-Aetiology Contrastive Severity Embeddings with Phonological Pseudo-Labelling for Multilingual Dysarthric Speech arXiv:2609.21789v1 Announce Type: new Abstract: Most multilingual dysarthria-severity systems either train on a single aetiology-language pair or pool heterogeneous aetiologies into one label space. We test that pooling assumption with four matched HuBERT-base contrastive… 22 arXiv — NLP / Computation & Language research 23d ago Reusing Latent Speech Representations for Query-Conditioned Topic Localization in Transcripts arXiv:2609.21844v1 Announce Type: new Abstract: Long transcripts are costly inputs for downstream NLP systems and often contain irrelevant context. We study query-conditioned topic localization: predicting the sentence span in a transcript that best addresses a topic-title… 23 arXiv — NLP / Computation & Language research 23d ago NemotronLabs VoiceChat: An Open Full-duplex Speech-to-Speech Model with Tool Calling Capabilities arXiv:2609.21967v1 Announce Type: new Abstract: We introduce NemotronLabs VoiceChat, an open full-duplex speech-to-speech model with native tool-calling capabilities. NemotronLabs VoiceChat combines a streaming speech encoder and decoder-only language model with parallel… 33 arXiv — NLP / Computation & Language research 23d ago Cross-Lingual Parkinson's Disease Severity Assessment Using Pre-trained Speech Embeddings: A Multi-Class Evaluation arXiv:2609.20875v1 Announce Type: cross Abstract: Parkinson's disease (PD) often manifests through speech impairments, facilitating accessible, non-invasive, and cost-effective severity assessment for early diagnosis and progression tracking. Despite advances in speech… 31 arXiv — NLP / Computation & Language research 23d ago Voice-Light: A Full-Duplex Cascaded Voice Agent with Causal Turn-Taking and Speculative Generation arXiv:2609.20995v1 Announce Type: cross Abstract: Natural spoken interaction requires more than streaming ASR, language generation, and speech synthesis: a system must react to overlap without canceling on every acknowledgment, prepare a response before a turn is certain, and… 21 arXiv — NLP / Computation & Language research 23d ago The Hidden Cost of Digits: Number Normalization and WER in ASR Systems arXiv:2609.21084v1 Announce Type: cross Abstract: Modern automatic speech recognition (ASR) systems trained on extremely large datasets can produce transcripts with numbers written in Arabic numerals. This creates a need for fair comparison with models that output verbatim texts… 9 arXiv — NLP / Computation & Language research 23d ago Listen Before You Speak: Response Planning from Listener Facial Reactions for Conversational Speech Generation arXiv:2609.21683v1 Announce Type: cross Abstract: Conversational speech depends on dialogue context and the listener's immediately preceding behavior. We propose ReACT-TTS, a two-stage framework that uses a one-second pre-response listener facial sequence to plan the next… 12 arXiv — NLP / Computation & Language research 23d ago Hierarchical attention interpretation: an interpretable speech-level transformer for bi-modal depression detection arXiv:2309.13476v3 Announce Type: replace Abstract: Depression is a common mental disorder. Automatic depression detection tools using speech, enabled by machine learning, help early screening of depression. This paper addresses two limitations that may hinder the clinical… 18 r/MachineLearning community 24d ago Inside sanoTTS — a 294,279-parameter TTS system [P] How sanoTTS works? I have vibe coded this site to show what's inside sanoTTS? Every tensor shown on the page is a real intermediate value captured from the shipped int8 model while it synthesized an actual sentence; no mock-ups, no stand-in data. Just check this out:… 35 r/LocalLLaMA community 25d ago What is the best tts to create audio books? One that support emotions? I tried google and on almost each mode.people complains it’s not good enough? is there any good tts right now that support English and can express emotions for audio and not read it in monotone voice?   submitted by   /u/Alarmed_Wind_4035 [link]   [comments] 21 Page 4 of 10 · 500 articles ← Newer Older →