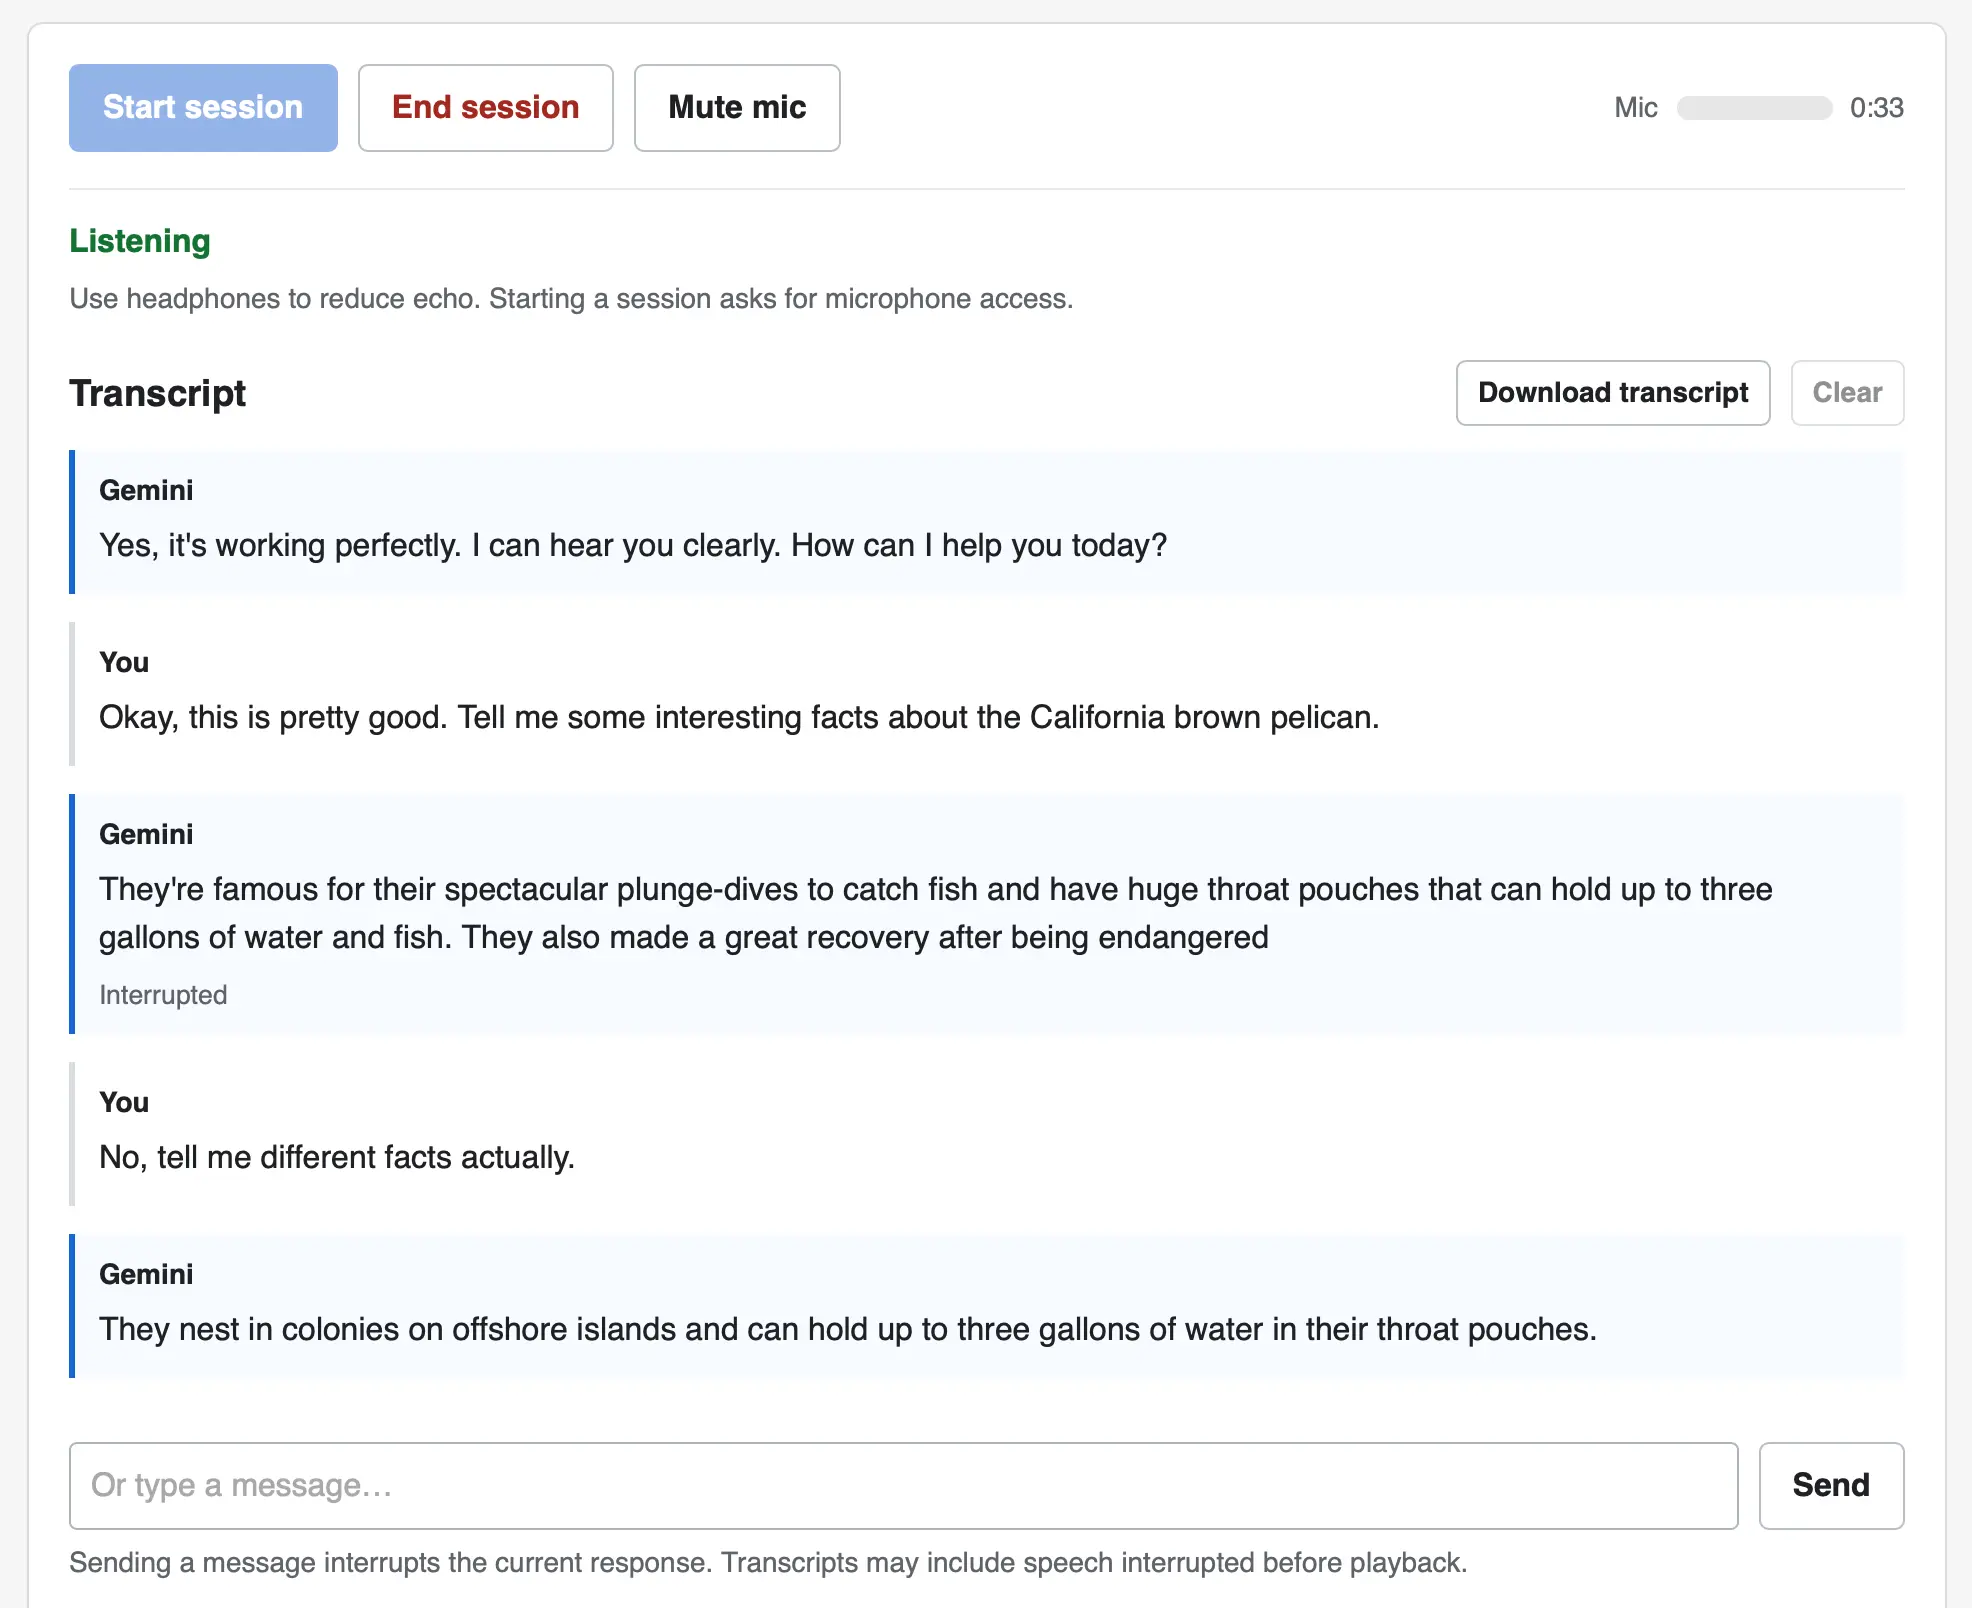
News / #voice Tag Voice 500 articles archived under #voice · RSS Sign in to follow r/LocalLLaMA community 25d ago Ternary Bonsai 2 27B (1.75bpw) vs. Gemma 26B-A4B MoE Introduction My audiobook pipeline that has to decide who speaks each line of dialogue in a novel, so the TTS can cast voices per character. It's been running on Gemma 4 26B-A4B (QAT Q4). Bonsai 2 27B looked like it should win: a 27B-class model in 5.9 GB means a stronger base… 13 arXiv — NLP / Computation & Language research 26d ago A frontend-backend architecture for tool calls in full-duplex speech models arXiv:2609.19334v1 Announce Type: new Abstract: Full-duplex speech-to-speech (S2S) models provide natural, low-latency conversational interaction and would benefit from the ability to use external tools and complete voice-agent tasks. We propose a frontend-backend architecture… 38 arXiv — NLP / Computation & Language research 26d ago Full-Duplex Speech Models Take the Floor When Asked, Not When Needed arXiv:2609.19596v1 Announce Type: new Abstract: Full-duplex speech models listen and speak at once, promising always-on assistants. Yet they must also decide when they should speak. Human listeners speak when addressed or when the speaker stops, but also self-select to correct a… 14 arXiv — NLP / Computation & Language research 26d ago Dictionary-Constrained Grapheme-to-Phoneme for Unsegmented Languages from LLM-Annotated Data arXiv:2609.19805v1 Announce Type: new Abstract: Grapheme-to-phoneme (G2P) conversion turns raw text into its phonemic form and is an essential part of both text-to-speech (TTS) and automatic speech recognition (ASR) systems. It is required to be fast, stable and context-aware.… 14 arXiv — NLP / Computation & Language research 26d ago Reading Emotions in the Token Space: Discriminative Adaptation of SpeechLLMs for Emotion Recognition arXiv:2609.20081v1 Announce Type: new Abstract: SpeechLLMs have shown strong potential for emotion recognition, yet they read the predicted emotion off a generative decoder not suited for classification: it can emit labels outside the target set and favors frequent classes. We… 29 arXiv — NLP / Computation & Language research 26d ago Design of the IBM Granite 5.0 TurboCTC ASR Model arXiv:2609.20104v1 Announce Type: new Abstract: We describe the architecture, training methodology and inference speedups of Granite 5.0 Turbo CTC, a 470 million parameter encoder-only model with an excellent speed-accuracy tradeoff. The architecture uses pyramidal temporal… 24 arXiv — NLP / Computation & Language research 26d ago Before the Warning Comes Too Late: Incremental Phone-Scam Detection from Speech arXiv:2609.20223v1 Announce Type: new Abstract: We study weakly supervised incremental telecom fraud detection from raw telephone audio, where training provides only conversation-level labels and predictions must be updated before a call ends. We introduce StreamFraudNet, which… 34 arXiv — NLP / Computation & Language research 26d ago The Public Discourse Corpus (PDC): A Speaker-Attributed Dataset for Valence and Epistemic Modality with Target Speaker Participation arXiv:2609.20232v1 Announce Type: new Abstract: We introduce the \textbf{Public Discourse Corpus (PDC)}, the first dataset of public-figure interview speech jointly annotated for affective valence and epistemic modality. The corpus contains 998 videos from 100 speakers across… 34 arXiv — NLP / Computation & Language research 26d ago Unifying Models of Intergroup Hostility in Online Discourse arXiv:2609.20808v1 Announce Type: new Abstract: Hostile rhetoric toward social groups can normalize exclusion and justify mistreatment, as well as contribute to rising polarization and political violence. Efforts to moderate hostile rhetoric in online speech draw on foundational… 33 arXiv — NLP / Computation & Language research 26d ago A Cross-Lingual Acoustic Disease-Alignment Framework for Respiratory Health Assessment from Spontaneous Speech arXiv:2609.19398v1 Announce Type: cross Abstract: Spontaneous speech offers a scalable, noninvasive signal for respiratory health assessment, yet interpretable models that generalize across languages remain challenging because disease-related acoustic changes are confounded by… 6 arXiv — NLP / Computation & Language research 26d ago From Intent to Action: Benchmarking LLM Safety in Vehicle Voice Command Authorization arXiv:2609.19630v1 Announce Type: cross Abstract: Large language models (LLMs) are increasingly integrated into vehicle voice assistants. But linking natural-language requests to vehicle functions creates a safety-critical authorization problem. Before executing a command, the… 25 arXiv — NLP / Computation & Language research 26d ago Model-Agnostic and Language-Agnostic Voice Pipeline Improvement for the Agriculture Domain arXiv:2609.20504v1 Announce Type: cross Abstract: FarmerChat is Digital Green's AI-powered agricultural advisory assistant for smallholder farmers, who access it in their own language through text, voice, or photographs. Voice is a critical channel for this population, yet… 26 The Information — AI news-outlet 27d ago Microsoft Execs Voiced Concern About OpenAI’s Data Use, New York Times Claims Microsoft executives expressed concerns in recent years that OpenAI’s use of paywalled articles from the New York Times and other publishers to train its models could pose legal issues, and OpenAI executives discussed how doing so could threaten those publishers’ businesses—but… 25 ElevenLabs official-blog 27d ago How Cadence cut response times to at-risk patients by 97% with ElevenAgents How Cadence uses HIPAA-compliant voice agents built with ElevenAgents to screen vital sign alerts and reach at-risk patients faster. 10 TechCrunch — AI news-outlet 27d ago Iceland-based Treble raises $18 million for its voice simulation platform Treble's voice simulation platform is used by voice AI model developers, AI wearable, and robotics companies 34 arXiv — NLP / Computation & Language research 27d ago Myovox: Reading Speech from the Muscles of the Face arXiv:2609.17548v1 Announce Type: new Abstract: Myovox, from myo (muscle) and vox (voice), decodes open-vocabulary English text from 31-channel surface electromyography (sEMG) recorded from the muscles of the face during vocalized speech. It takes the single-subject emg2speech… 24 arXiv — NLP / Computation & Language research 27d ago T-SANDHI: Tone Sandhi-aware Adaptive Network with Decoupled Hybrid Injection for Low-resource Taiwanese Hokkien Speech Recognition arXiv:2609.18194v1 Announce Type: new Abstract: In Taiwanese Hokkien automatic speech recognition (ASR), prior studies often treat tone sandhi as a major challenge under the assumption that models fail to process implicit phonological variations. However, our experiments on… 36 arXiv — NLP / Computation & Language research 27d ago Align, Integrate, and Fire: Efficient Token-Level Alignment for Zero-Shot SpeechLLMs arXiv:2609.18516v1 Announce Type: new Abstract: While Large Language Models excel in natural language processing, efficiently extending their capabilities to spoken input remains a significant challenge. Existing methods for building SpeechLLMs often rely on computationally… 11 arXiv — NLP / Computation & Language research 27d ago A Probe Shift Is Not a Fairness Fix: The Limits of Representation Steering in Speech Models arXiv:2609.18533v1 Announce Type: new Abstract: Automatic speech recognition (ASR) systems exhibit unequal error rates across speaker groups, motivating interventions on their internal representations. We ask whether speaker-linked attributes that are linearly readable from… 9 arXiv — NLP / Computation & Language research 27d ago Voice of Reason: Reinforcement Learning for Spoken Math arXiv:2609.18677v1 Announce Type: new Abstract: Speech language models enable richer spoken interactions between humans and machines than cascaded systems, allowing access to paralinguistic information and lower latency. However, their accuracy on mathematical reasoning… 16 arXiv — NLP / Computation & Language research 27d ago HearInContext: A Benchmark for Implicit Context in Speech Recognition arXiv:2609.18680v1 Announce Type: new Abstract: Contextual ASR can benefit from semantic cues or from target words explicitly provided in the context. We introduce HearInContext, a Mandarin--English benchmark that pairs shared synthetic speech with assistant replies supporting… 13 arXiv — NLP / Computation & Language research 27d ago Encoder Awakening via Adapters: Effective Domain-Adaptive Fine-tuning of Speech-LLMs arXiv:2609.17981v1 Announce Type: cross Abstract: Speech Large Language Models (Speech-LLMs), typically built from a pre-trained speech encoder, a modality projector, and an LLM fine-tuned with Low-Rank Adapters (LoRA), have shown strong Automatic Speech Recognition (ASR)… 32 arXiv — NLP / Computation & Language research 27d ago G-Mamba: Sparse Graph-Guided Mamba for Audio-Visual Speech Enhancement arXiv:2609.18009v1 Announce Type: cross Abstract: Lightweight audio-visual speech enhancement (AVSE) models face a critical trade-off between computational efficiency and cross-modal alignment accuracy. While simple concatenation lacks relational expressiveness, dense… 23 Vercel — AI dev-tools 28d ago GPT-Live 1 now available on AI Gateway GPT-Live 1 from OpenAI is now available on AI Gateway. GPT-Live 1 is a full-duplex voice model and can listen and speak at the same time. Many voice models use turn detection to respond. Full duplex removes that boundary, so a user can pause, interrupt, or add detail while… 27 ElevenLabs official-blog 28d ago Introducing Reception, by ElevenAgents Reception is an AI receptionist for small businesses. It answers every call in a natural voice, books jobs straight into your calendar, and goes live in a few minutes. 33 arXiv — NLP / Computation & Language research 28d ago Speaker-Specific and Language-Dependent Temporal Organization in Bilingual Political Speech arXiv:2609.16274v1 Announce Type: new Abstract: Speech rhythm helps structure persuasive speech, but most empirical work examines monolingual English. This study asks how politicians organize timing when speaking Luxembourgish and French. We analyze 400 sentences from ten… 38 arXiv — NLP / Computation & Language research 28d ago Speaker or Language? Explaining Variance in Charismatic Prosody Across Luxembourgish and French arXiv:2609.16275v1 Announce Type: new Abstract: Charismatic speech is shaped by language and speaking style, yet their relative contribution in bilingual public speaking remains unclear. We analyzed spontaneous speeches of 10 politicians who address audiences in Luxembourgish… 17 arXiv — NLP / Computation & Language research 28d ago ParsHate: A Benchmark Dataset for Hate and Target Detection in Persian arXiv:2609.16393v1 Announce Type: new Abstract: We introduce ParsHate, a manually annotated dataset of 10,000 Persian tweets spanning 2013-2022, representing the first decade-long benchmark for hate speech detection in Persian. The dataset contains 31% hateful content and… 19 arXiv — NLP / Computation & Language research 28d ago RoleBreak: Benchmarking Long-Horizon Role-Playing Robustness in Spoken Dialogue arXiv:2609.16614v1 Announce Type: new Abstract: Speech-to-speech dialogue models increasingly support persona control, yet existing spoken role-playing benchmarks remain largely character-centric and short-horizon. This leaves open whether spoken dialogue models can sustain… 15 arXiv — NLP / Computation & Language research 28d ago DiaWhisper-DPO: Role-Attributed Transcription of Clinical Interviews via Failure-Mined Preference Optimization arXiv:2609.16661v1 Announce Type: new Abstract: Automated depression screening from clinical interviews requires attribution of utterances to the clinician or patient. We evaluate two datasets: DAIC-WOZ, where participant-only recordings require re-synthesizing both sides for… 18 arXiv — NLP / Computation & Language research 28d ago Deconstructing Stereotypes: Scope-Conditioned Generation for Effective Multilingual Counterspeech arXiv:2609.16906v1 Announce Type: new Abstract: Counterspeech (CS) - direct responses that counter online Hate Speech (HS) using reasoning and alternative viewpoints - has emerged as an alternative to content removal. Current automatic CS generation methods, however, frequently… 37 arXiv — NLP / Computation & Language research 28d ago Language Orthogonalization for Zero-Shot Cross-Lingual Audio Deepfake Detection arXiv:2609.16458v1 Announce Type: cross Abstract: Audio deepfake detectors need to transfer to languages absent from training, as multilingual speech synthesis outpaces labeled anti-spoofing resources. While detectors increasingly rely on self-supervised speech models (S3Ms),… 10 arXiv — NLP / Computation & Language research 28d ago Audio-Visual Turn-taking Prediction in Cocktail Party Scenarios arXiv:2609.17056v1 Announce Type: cross Abstract: Current predictive turn-taking models (PTTMs) achieve strong performance on benchmarks with controlled acoustic conditions and clean audio signals. Their generalisation to conversations with overlapping speech and background… 28 r/LocalLLaMA community 28d ago What's the next local model you are excited about? And why?   submitted by   /u/MrMrsPotts [link]   [comments] 35 Simon Willison community 29d ago Gemini Live audio Tool: Gemini Live audio Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live models. I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying… 35 r/LocalLLaMA community 29d ago Voice Acting Arena Hey everyone! We’re launching Voice Acting Arena with LAION x TTS Arena , and we’d love your help trying it out 🙂 You’ll hear two anonymous AI performances of the same scene and script, then compare them on overall acting, how well they follow the direction, and how genuine… 15 Hugging Face Daily Papers research 29d ago Realtime-Venus: A full-duplex interaction system with asynchronous delegation Abstract Realtime-Venus is a proactive full-duplex system with separate audio-visual and audio models that integrate continuous perception, conversational control, and native speech generation via a shared causal timeline and dual-loop runtime. Generated by… 23 arXiv — Machine Learning research 29d ago Machine Unlearning for Speech Question Answering in Large Audio-Language Models arXiv:2609.13195v1 Announce Type: new Abstract: Large Audio-Language Models (LALMs) have recently shown strong capabilities in speech understanding and question answering (QA), but they also inherit privacy risks from large-scale training data, including the unintended… 26 arXiv — NLP / Computation & Language research 29d ago Token Merging for Multilingual Speech Recognition: A Systematic Study Across Model Scale and Fine-Tuning arXiv:2609.13151v1 Announce Type: new Abstract: Leading multilingual speech recognition models like Whisper transcribe diverse, low-resource languages without language-specific training but are computationally expensive to deploy. Token merging mitigates this inefficiency by… 38 arXiv — NLP / Computation & Language research 29d ago CVSS-X: A Multilingual Speech-to-Speech Translation Corpus for 28 Languages arXiv:2609.13413v1 Announce Type: new Abstract: We introduce CVSS-X, a large-scale synthetic speech-to-speech translation corpus that extends CVSS by reversing the translation direction. While CVSS translates from 21 languages into English, CVSS-X enables translation from… 27 arXiv — NLP / Computation & Language research 29d ago Causal Analysis and Mitigation of Spurious Onsets in Full-Duplex Speech LLMs arXiv:2609.13445v1 Announce Type: new Abstract: Speech-to-speech LLMs like Moshi, and its derivative PersonaPlex, can listen and speak concurrently through full-duplex generation. However, they can begin speaking inappropriately during prolonged user silence: under digital-zero… 5 arXiv — NLP / Computation & Language research 29d ago Bangla Sentence Function Classification: Corpus Development, Model Benchmarking, and Interpretability arXiv:2609.13869v1 Announce Type: new Abstract: Automatic sentence function identification is important for many downstream natural language processing (NLP) applications such as dialogue systems, text-to-speech synthesis, and machine translation. However, benchmark resources… 4 arXiv — NLP / Computation & Language research 29d ago A Multi-Stage Agentic Framework for Effective Counter-Narrative Generation and Refinement arXiv:2609.14178v1 Announce Type: new Abstract: The rapid diffusion of hate speech and misinformation on social networks challenges democratic societies, since direct suppression efforts may deepen polarization, fuel public distrusts, and strengthen extremist narratives.… 38 arXiv — NLP / Computation & Language research 29d ago Neyshekar: An Open Persian Read-Speech Corpus for Automatic Speech Recognition arXiv:2609.14542v1 Announce Type: new Abstract: Neyshekar is presented as an open Persian read-speech corpus designed for coverage of both formal and informal language, named entities, and longer utterances. In version 6, 62,279 validated recordings totalling 99.02 hours are… 26 arXiv — NLP / Computation & Language research 29d ago Quantifying the Generation Modality Gap in Speech-Text Language Models arXiv:2609.14743v1 Announce Type: new Abstract: Pure speech language models often lag behind text and speech-text language models in generating coherent content, but this gap is difficult to quantify because speech and text systems are typically evaluated with different metrics… 37 arXiv — NLP / Computation & Language research 29d ago Tone on a Budget: A Reference-Free Metric for Lexical Tone in Massively Multilingual Text-to-Speech arXiv:2609.14817v1 Announce Type: new Abstract: In Yor\`ub\'a, pitch alone separates \d{o}k\d{o} (husband, Mid), \d{o}k\d{\`o} (vehicle, Low), and \d{o}k\d{\'o} (hoe, High) -- the diacritics ARE the tone marks. Yet character error rate (CER), the standard automated metric for… 8 arXiv — NLP / Computation & Language research 29d ago Typhoon ASR Streaming: Steerable Low-Latency Thai Speech Recognition with Real-Time Shallow Fusion arXiv:2609.14991v1 Announce Type: new Abstract: Open Thai automatic speech recognition (ASR) is dominated by offline, Whisper-based models that read the whole utterance before transcribing, ruling out low-latency uses such as live captioning and voice agents. We present a… 34 Vercel — AI dev-tools 1mo ago Gemini 3.8 Live models now available on AI Gateway Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking from Google are now available on AI Gateway. Both models support real-time spoken interactions for voice assistants, conversational experiences, and applications that respond through audio. google/gemini-3.8-live supports… 21 ElevenLabs official-blog 1mo ago Introducing voice, music, image, and video generation in the ElevenLabs MCP Generate voice, music, sound effects, images, and video from Claude, ChatGPT, or Cursor. Everything lands in your ElevenCreative workspace. 23 Hugging Face Daily Papers research 1mo ago Building and Evaluating Fixed-Voice Thai TTS from Synthetic Speech Abstract A compact Thai text-to-speech model is distilled from a large voice-cloning teacher using synthetic data from brief voice references, achieving strong on-device accuracy and prosody with minimal errors. Generated by thinkingmachines/Inkling-Small In low-resource… 33 Page 5 of 10 · 500 articles ← Newer Older →