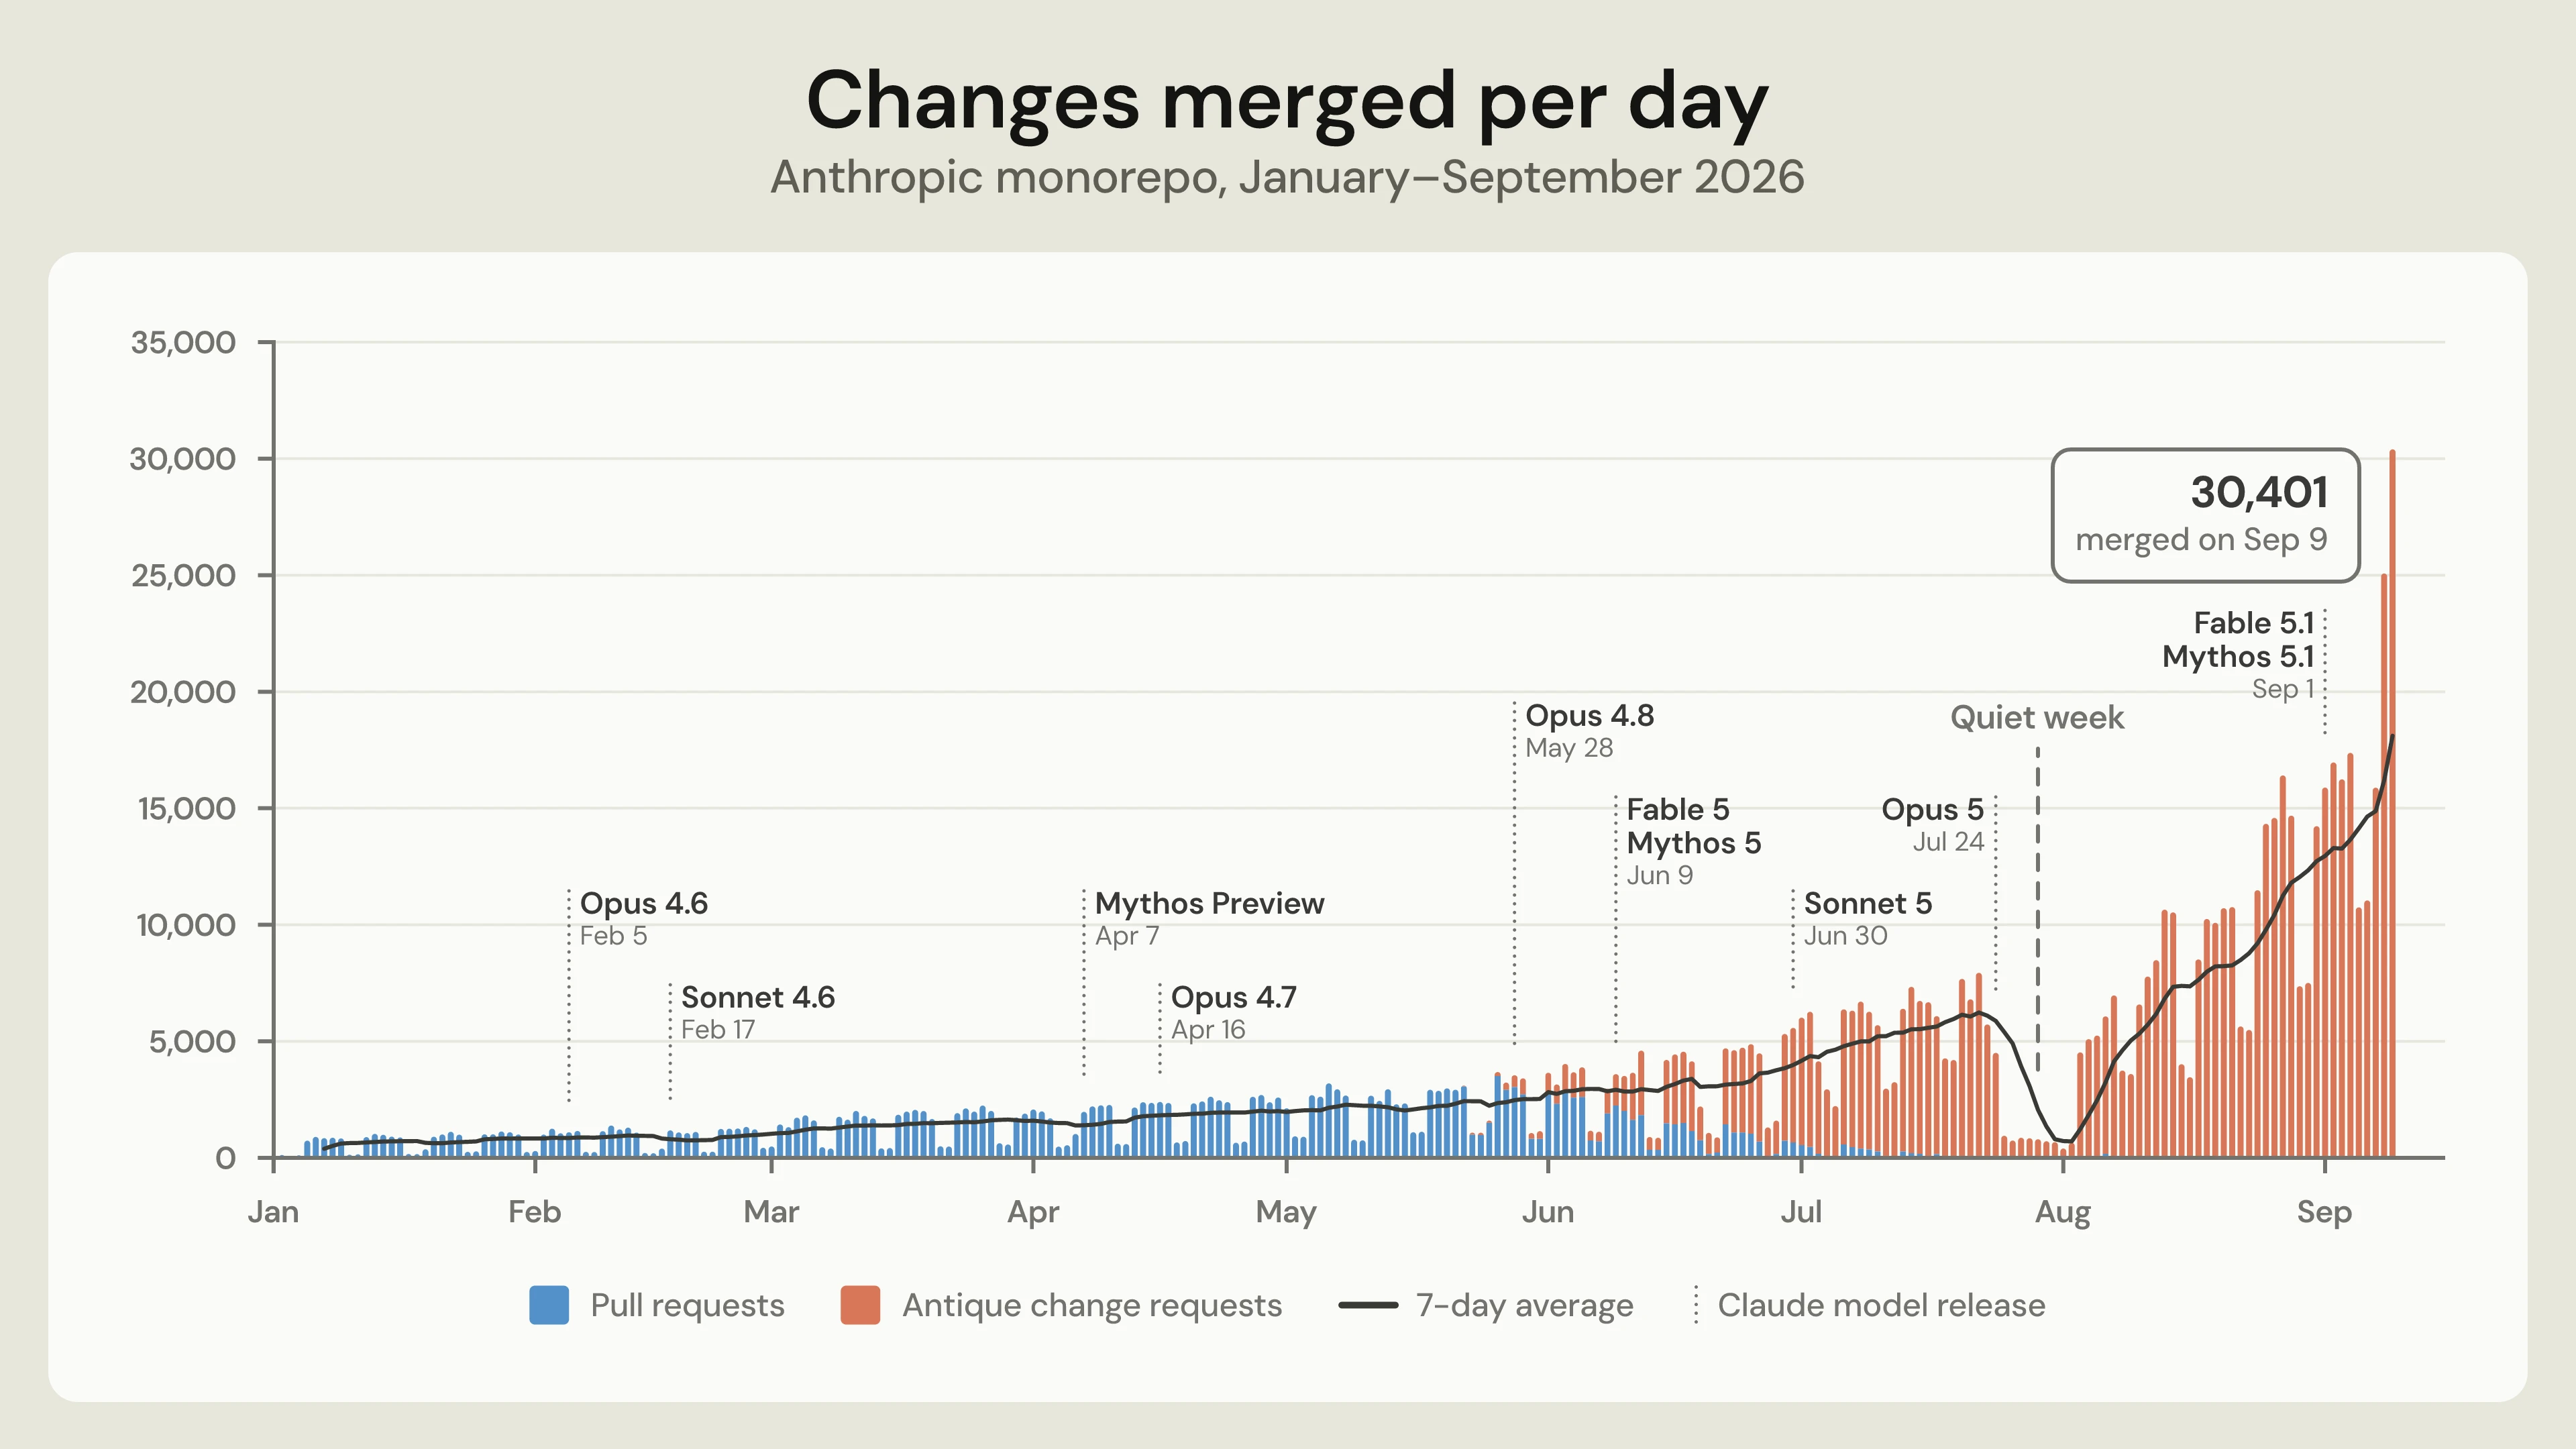
News / #rag Tag Rag 500 articles archived under #rag · RSS Sign in to follow r/MachineLearning community 10h ago Event2Vec: additive event embeddings where a linear score on a history decomposes exactly into per-event terms [P] I've been working on Event2Vec, a small library for learning embeddings of discrete event sequences (purchases, logs, clinical codes, etc.) with a deliberately simple structure: a history is the running sum of its event vectors. h_t = h_{t-1} + e_{x_t} (norm-clipped) p(x_{t+1} |… 21 OpenAI Python SDK releases dev-tools 17h ago v3.30.0 3.30.0 (2026-10-14) Features api: add beta session spending limits ( #4058 ) ( b570279 ) api: add OCI external-storage provider support ( #4060 ) ( 9eb83fe ) api: add organization Decisions usage reporting ( #4062 ) ( 5e7a23e ) api: expose image tool error and moderation details… 31 r/LocalLLaMA community 18h ago Discover AI: A Learning Guide - 51 hands-on labs for learning how AI actually works. This is an offline app with 51 hands-on labs for learning how AI actually works, from neurons to agents and more... **A bit of insight** - 51 labs in 6 groups, from the basics (what a neuron is, gradient descent) through attention, RAG, agents, fine-tuning, quantization, serving… 32 Ollama releases dev-tools 20h ago v0.40.4 What's Changed llama: update llama.cpp to b11521 for decision models and EmbeddingGemma 2 by @jmorganca in #18917 server: reuse verified manifests and loaded models in inference routes by @dhiltgen in #18947 mlx: compact restored recurrent state after speculative rollback by… 33 Simon Willison community 22h ago Redesigning source control at Anthropic Redesigning source control at Anthropic Interesting piece from Anthropic describing why and how they built their own custom alternative to Git, based on the dramatic increase in rate of changes to their code after the past six months. In May 2026, Anthropic averaged around 2,500… 8 Google DeepMind official-blog 1d ago Developing Gemini 4 Argon responsibly and safely Developing Gemini 4 Argon responsibly and safely Oct 13, 2026 | x.com Facebook LinkedIn Mail Learn more about our approach to safety and security for Gemini 4 Argon. Anca Dragan VP, AI Safety & Behavior Raluca Ada Popa Head of Gemini Security, Google DeepMind Share x.com… 21 llama.cpp releases dev-tools 1d ago b11597: graph: skip the LM head for pooled embeddings (#30445) graph: skip the LM head for pooled embeddings A context that extracts pooled embeddings outputs one vector per sequence, but every model still expanded its LM head, so the graph computed n_vocab logits per token and the context kept a host buffer for them. The models now only… 31 llama.cpp releases dev-tools 1d ago b11596: tests : consolidate context state tests into test-llama-context (#30023) tests : consolidate the context state tests into test-llama-context test-save-load-state, test-recurrent-state-rollback and test-state-restore-fragmented check the same object from three places: the KV cache and the recurrent state of a llama_context, saved, loaded, copied,… 20 r/MachineLearning community 1d ago Where do LLMs actually earn their place in a recommender system? Kim Falk’s new book + 5 ebook giveaway [D] Hi r/MachineLearning , Stjepan from Manning here. The mods approved this post, and I appreciate being welcomed back to share another book with you. We’ve just launched AI Recommender Systems: Transformers, LLMs, agents, and RAG by Kim Falk in MEAP, our early-access program. Kim… 8 r/MachineLearning community 1d ago How do you handle coverage guarantees from split conformal prediction when the data shifts? [D] Split conformal prediction gives you a clean statement: with a calibration set exchangeable with future data, your prediction sets cover the true label at the rate you chose. The trouble is that production data rarely stays exchangeable. Categories get added, ticket wording… 8 Vercel — AI dev-tools 1d ago Repository checkout and Git LFS downloads are now faster Repository checkout and Git LFS downloads are now faster on Vercel, reducing the time spent preparing your project's files before a build. During rollout on build machines with more than two vCPUs: The average time to get project files ready fell by 20%. For LFS-enabled… 35 Ollama releases dev-tools 2d ago v0.40.4 What's Changed llama: update llama.cpp to b11521 for decision models and EmbeddingGemma 2 by @jmorganca in #18917 server: reuse verified manifests and loaded models in inference routes by @dhiltgen in #18947 mlx: compact restored recurrent state after speculative rollback by… 33 r/LocalLLaMA community 2d ago Qwen3.8-27B vs Frontier vs Others Here're results from my final test of coding, coding (panda/numpy), data analysis, data-driven decision-making, and local RAG domains I interact with most often. This test, which is refined from a 500+ pack, now provides a differentiating signal between models after having… 24 NVIDIA Developer Blog official-blog 2d ago ReplaySSM: Rethinking State Storage for Faster Hybrid-Model Decoding Hybrid models interleave state-space model (SSM) layers with a few attention layers. NVIDIA Nemotron 3, Qwen3.5 through Qwen3.8, Kimi-K3, and GLM-5.3-Flash are... 26 r/LocalLLaMA community 2d ago Boole-1.7B: A 1-bit Qwen3-1.7B model that outperforms Bonsai-1.7B We're launching Precision Numerics by releasing Boole-1.7B, a 1-bit version of Qwen3-1.7B. 247 MB packed weights: 13.9× smaller than BF16. 85.9% of the BF16 model’s average score across our 10-task evaluation - outperforms 1-bit Bonsai-1.7B and nearly matches 1.58-bit… 10 r/LocalLLaMA community 2d ago A "free" multi-modal "embedding" model (already) included with your LLM: vLLM plugin + upstream PR Disclaimer: I work for NuMind, the company behind this plugin. TLDR: Text/image (simili-)embeddings from the LLM you already have loaded :-) I've been working on making it easier to obtain embeddings from a LLM (preferably multi-modal) that is already being served by vLLM. The… 37 r/LocalLLaMA community 2d ago LLC: lightweight Open WebUI alt now with Agents+MCP+RAG+Image Editing Quick context: LocalLightChat (LLC) is a chat frontend for local LLMs. Download it, run it, that's it. No installation (unless you want to), no dependencies, and it runs on pretty much anything, including ancient hardware. I originally built it because Open WebUI kept feeling… 23 r/LocalLLaMA community 2d ago LSearch - Spotlight for windows with embedding I built a spotlight search for windows. It has an embedding model and a MoE models to go with it. The MoE It's 2 Qwen 3.5 4B models, I fine tuned one for coding work and another for agentic work, and then I combined them both into an MoE. I didn't want to shove it into… 9 r/LocalLLaMA community 2d ago VectorDash: A full Windows search replacement incorporating Embeddinggemma-2 Inspired by DigUp for macOS, VectorDash aims to be a full Windows 11 search replacement, powered by EmbeddingGemma 2 . Full indexing: search by meaning or exact words across photos, screenshots, audio, video, PDFs and Office documents. Find “images of dogs,” a podcast… 23 arXiv — Machine Learning research 2d ago STAPLE: Static Sparse Upcycling of Pretrained Checkpoints via Embedding Modules arXiv:2610.12599v1 Announce Type: new Abstract: Sparse computation can scale the parametric capacity of LLMs without proportionally increasing active computation, but pretraining sparse architectures remains expensive and data-hungry. Existing sparse upcycling methods mainly… 17 arXiv — Machine Learning research 2d ago CopRoute: Dependence-Aware Conformal Routing for Language Models arXiv:2610.13276v1 Announce Type: new Abstract: Set-based language model routing aims to increase the coverage of the event where at least one model answers a query correctly while controlling the number of inference calls made. Existing risk-controlled routing policies bound… 5 arXiv — NLP / Computation & Language research 2d ago MADS: Multi-Agent Dialog Simulation for Robust Conversational Agents arXiv:2610.12757v1 Announce Type: new Abstract: Task-oriented conversational agents remain fragile under realistic conditions, especially when users exhibit non-cooperative behavior. Existing function-calling benchmarks underrepresent adversarial conversation trajectories,… 4 arXiv — NLP / Computation & Language research 2d ago Rethinking the Roles of Diffusion and Decoding: Predictive-State Flows for Parallel Language Generation arXiv:2610.12898v1 Announce Type: new Abstract: In continuous diffusion language models (DLMs), latents generated by the diffusion prior are mapped almost deterministically to tokens, either by a decoder or through a token embedding matrix. Unlike in image generation, where… 5 arXiv — NLP / Computation & Language research 2d ago Personalization Without Stereotyping: Do Speech LLMs Know When to Turn a Deaf Ear? arXiv:2610.13550v1 Announce Type: new Abstract: Recent speech LLMs can leverage rich paralinguistic cues, enabling more complex and personalized interactions. However, little work investigates how this sensitivity can lead to stereotyping, and existing evaluations largely… 18 arXiv — NLP / Computation & Language research 2d ago Benchmarking Embedding Geometries and Clustering Algorithms for Unsupervised Patent Claim Classification arXiv:2610.12997v1 Announce Type: cross Abstract: Prior-art retrieval systems are structurally organized around classification codes, making cross-code discovery difficult. This paper asks if an unsupervised representation trained on patent text can recover relevant connections… 37 arXiv — NLP / Computation & Language research 2d ago Locate, Judge, Read: Role-Specialized Tool Agents over a Knowledge-Point Index for Open-Domain Multimodal Document QA arXiv:2610.13128v1 Announce Type: cross Abstract: Question answering over large heterogeneous document collections requires first finding the right passages and then reading them, yet current retrieval-augmented agents give one model both kinds of tools and let it schedule… 38 arXiv — NLP / Computation & Language research 2d ago Beyond the Final Embedding: Retrieving Memories from Token-Level Evidence arXiv:2610.13277v1 Announce Type: cross Abstract: Memory-augmented assistants retrieve evidence from stored conversations and documents to answer queries. Most embedding-based retrievers compare single-vector representations of queries and memories, even when relevance depends… 24 r/MachineLearning community 3d ago Sliced Wasserstein embeddings + HNSW for color-scheme search over 48k paintings [P] Palette Atlas ( https://itzik123.github.io/PaletteAtlas/ ) searches public-domain paintings by color scheme. Each image is reduced to 128 colors of equal weight, so the natural distance is the Earth Mover's Distance, which is too slow for nearest-neighbor search over 48,695… 6 r/LocalLLaMA community 3d ago I trained a 102M recursive BitNet-v2 model from scratch: 64K context, trained on less than 5B tokens DISCLAIMER: the post and the model card was made with the assist of AI. Hiya, I’m releasing Recursive BitNet N-Gram 102M, a small experiment combining ternary weights, shared transformer layers, and hashed n-gram embeddings, trained with a whooping budget of 100€ Weights,… 23 r/LocalLLaMA community 4d ago Open-source Mac app that runs EmbeddingGemma 2 locally to search your files by what’s in them DigUp is a free Mac app that runs Google DeepMind’s new EmbeddingGemma 2 locally over your own files. The model puts text, images, audio and video in one space, so you describe what you remember and land on it: “zebra in a video” opens the clip at the moment it shows up “where… 10 r/MachineLearning community 4d ago Real-time neural weather restyling for Minecraft on a GTX 1650 (1.4M-param U-Net, distilled from FLUX.2 klein, 30-40 FPS realtime on budget GPU) [P] Teacher: FLUX.2 klein 4B paints ~3k frames (snow / wet / night at 3 strengths). Student: 1.4M-param U-Net with FiLM sliders, 512×288, ~26 ms/frame via ONNX Runtime inside a Fabric mod; the HUD stays untouched. Pixel loss (L1+MSE) gave a washed-out “average” because the teacher… 20 r/LocalLLaMA community 4d ago Is there a music embedding model? Has anybody built/released a music embedding model trained on a large library of diverse music?   submitted by   /u/unraveleverything [link]   [comments] 29 llama.cpp releases dev-tools 5d ago b11537 graph : reorder get_rows for embeddings ( #30160 ) graph : reorder get_rows for embeddings cont : fix gemma4 and improve input embedding construction logic cont : add TODO for lora cont : fix raw embeddings path gemma4 : avoid ple cast in embeddings path Website:… 31 Vercel — AI dev-tools 5d ago Deployment Storage billing begins for existing Pro teams Deployment Storage and Functions Storage billing will begin for all Pro teams at $0.10 per GB-month. Check your email for details about when billing will start for your team. To keep storage costs low, the deployment retention window also changes to 30 days. Deployments older… 38 r/MachineLearning community 5d ago I built ALHR: A tree based sparse attention system that achieves sub-quadratic inference while retaining accuracy. [P] ALHR - Adaptive Learnable Hierarchical Routing, uses static binary trees and learnable functions to minimize the amount of keys to be read. It does use a dense teacher while phase 1 of training however. MQAR TEST AT 1024 TOKENS - Average keys read per query by dense - 512 Keys… 5 llama.cpp releases dev-tools 5d ago b11523 ci: fix Models Backend webgpu by supporting GGML_OP_DUP ( #30216 ) The mixed batch path of PR-29622 writes the token rows with set_rows into a dup of the embeddings. WebGPU did not support DUP, so the dup ran on the CPU while the set_rows writing into it was scheduled on WebGPU,… 32 r/LocalLLaMA community 5d ago [Paper] EngramEdit: Decoupled Knowledge Updates in LLMs through Conditional Memory Conditional memory architectures such as DeepSeek Engram use input n-grams to look up learned embeddings, expanding the capacity of large language models (LLMs) with limited additional computation. Beyond model scaling, this architecture has demonstrated the potential to… 15 arXiv — Machine Learning research 5d ago Coverage, Not Difficulty, Sets How Much Synthetic Data an Activation Probe Needs arXiv:2610.10594v1 Announce Type: new Abstract: Activation probes that monitor deployed language models are trained on synthetic conversations, and how many a probe needs is open. We trace learning curves over 10-590 synthetic samples for three monitoring concepts, high-stakes… 7 arXiv — Machine Learning research 5d ago Coverage-Aware Reasoning with Medical Tokens for Diagnosis Prediction arXiv:2610.10641v1 Announce Type: new Abstract: Large language models (LLMs) offer promising potential for next-visit diagnosis prediction, owing to their ability to integrate longitudinal clinical evidence and reason over it in natural language. However, reinforcement learning… 11 arXiv — Machine Learning research 5d ago Beyond the Ergodic Wall: A Discrete Geometric Physics Sandbox for Analysing AI Scaling Limits and Complexity Collapse arXiv:2610.10651v1 Announce Type: new Abstract: This paper exposes the ergodic ceiling and thermodynamic inefficiency of current deep learning, which converges to a statistical average of historic human knowledge. True semantic novelty requires a path-dependent, spatiotemporally… 33 arXiv — Machine Learning research 5d ago MemoWM: How World Models Change What Agents Need to Remember arXiv:2610.10778v1 Announce Type: new Abstract: Long-term agents face growing storage demands as they accumulate experience. World models capture reusable regularities that can reduce the information stored for each experience. We formulate the problem of memory allocation… 16 arXiv — Machine Learning research 5d ago How Many Repeated Pairwise Comparisons Are Needed for Ranking under Heterogeneity? arXiv:2610.10795v1 Announce Type: new Abstract: We study ranking models by population-average utility from pairwise comparisons when preferences vary across users and tasks. Prior work shows that a single comparison per user can be insufficient to identify the alternative with… 5 arXiv — Machine Learning research 5d ago Budgeted Multi-Source Counterfactual Annotation for Off-Policy Evaluation arXiv:2610.10974v1 Announce Type: new Abstract: Off-policy evaluation (OPE) estimates the value of a target policy from logged data, but limited behavior-policy coverage can force high-variance reweighting or reward-model extrapolation. Counterfactual annotations can add… 38 arXiv — Machine Learning research 5d ago Optimizing Large Language Models with Chained LMOs arXiv:2610.10975v1 Announce Type: new Abstract: Muon has motivated a growing family of optimizers that compose multiple matrix normalizations, but these methods remain fragmented and lack a unified perspective. We introduce chained linear minimization oracles (chained LMOs),… 33 arXiv — Machine Learning research 5d ago Bridging KV-Cache Quantization and Linear Attention: From Theory to Pretrained Weight Migration arXiv:2610.11214v1 Announce Type: new Abstract: KV-cache quantization and linear attention are two representative approaches to tackling the storage and computational costs of Transformers. KV-cache quantization compresses individual KV entries into discrete codes but retains… 27 arXiv — Machine Learning research 5d ago Multimodal Graph Retrieval-Augmented Sequential Recommendation via Collaborative Filtering Paths arXiv:2610.11228v1 Announce Type: new Abstract: Multimodal Large Language Models (MLLMs) have demonstrated strong potential for sequential recommendation through their ability to reason over complex multimodal data. However, existing approaches either rely solely on the target… 19 arXiv — NLP / Computation & Language research 5d ago LadderEdit: Edit-Level Residual Compression for Memory-Efficient Lifelong Editing of LLMs arXiv:2610.11160v1 Announce Type: new Abstract: Lifelong editing of LLMs requires storing thousands of edits after acquisition. A widely used family of approaches attaches one LoRA adapter per edit, which preserves behavior but grows linearly in storage. To address this… 38 arXiv — NLP / Computation & Language research 5d ago RAG-Stress: Probing the Limits of Evidence Reliance in Retrieval-Augmented Generation arXiv:2610.11183v1 Announce Type: new Abstract: Following retrieved evidence does not guarantee factual correctness: misleading evidence can induce a model to replace an answer it previously gave correctly. Standard accuracy measures obscure this behavior by combining answer… 6 arXiv — NLP / Computation & Language research 5d ago From Retrieval to Reconstruction: Constructing Evolvable Cognitive Memory for Long-Term Dialogue arXiv:2610.11314v1 Announce Type: new Abstract: Large Language Models (LLMs) serving as long-term dialogue agents require memory systems that support reliable reasoning over extended interactions. However, existing Retrieval-Augmented Generation (RAG) frameworks typically treat… 29 arXiv — NLP / Computation & Language research 5d ago SignRAG: Unified Retrieval-Augmented Gloss-Free Sign Language Translation arXiv:2610.11371v1 Announce Type: new Abstract: Contemporary decoder-only large language models (LLMs) have demonstrated strong capabilities across a wide range of domains. However, existing pretraining paradigms for gloss-free sign language translation (SLT) are largely… 36 Page 1 of 10 · 500 articles Older →